Tackling Noisy Labels With Network Parameter Additive Decomposition
Related Experiment Video
Updated: Jun 29, 2025

Closed-loop Neuro-robotic Experiments to Test Computational Properties of Neuronal Networks
Published on: March 2, 2015

Abstract:
Given data with noisy labels, over-parameterized deep networks suffer overfitting mislabeled data, resulting in poor generalization. The memorization effect of deep networks shows that although the networks have the ability to memorize all noisy data, they would first memorize clean training data, and then gradually memorize mislabeled training data. A simple and effective method that exploits the memorization effect to combat noisy labels is early stopping. However, early stopping cannot distinguish the memorization of clean data and mislabeled data, resulting in the network still inevitably overfitting mislabeled data in the early training stage. In this paper, to decouple the memorization of clean data and mislabeled data, and further reduce the side effect of mislabeled data, we perform additive decomposition on network parameters. Namely, all parameters are additively decomposed into two groups, i.e., parameters w are decomposed as w=σ+γ. Afterward, the parameters σ are considered to memorize clean data, while the parameters γ are considered to memorize mislabeled data. Benefiting from the memorization effect, the updates of the parameters σ are encouraged to fully memorize clean data in early training, and then discouraged with the increase of training epochs to reduce interference of mislabeled data. The updates of the parameters γ are the opposite. In testing, only the parameters σ are employed to enhance generalization. Extensive experiments on both simulated and real-world benchmarks confirm the superior performance of our method.


Related Concept Videos
 01:04
¹³C NMR: ¹H–¹³C Decoupling
A broadband decoupling technique is used to simplify these complex, sometimes overlapping, signals. Broadband decoupling relies on a...
 01:11
Residuals and Least-Squares Property
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
 01:25
Network Function of a Circuit
 01:30
Classification of Signals
A continuous-time signal holds a value at every instant in time, representing information seamlessly. In contrast, a discrete-time signal holds values only at specific moments, often denoted as x(n), where...
 01:10
Interpreting ¹H NMR Signal Splitting: The (n + 1) Rule
 01:09
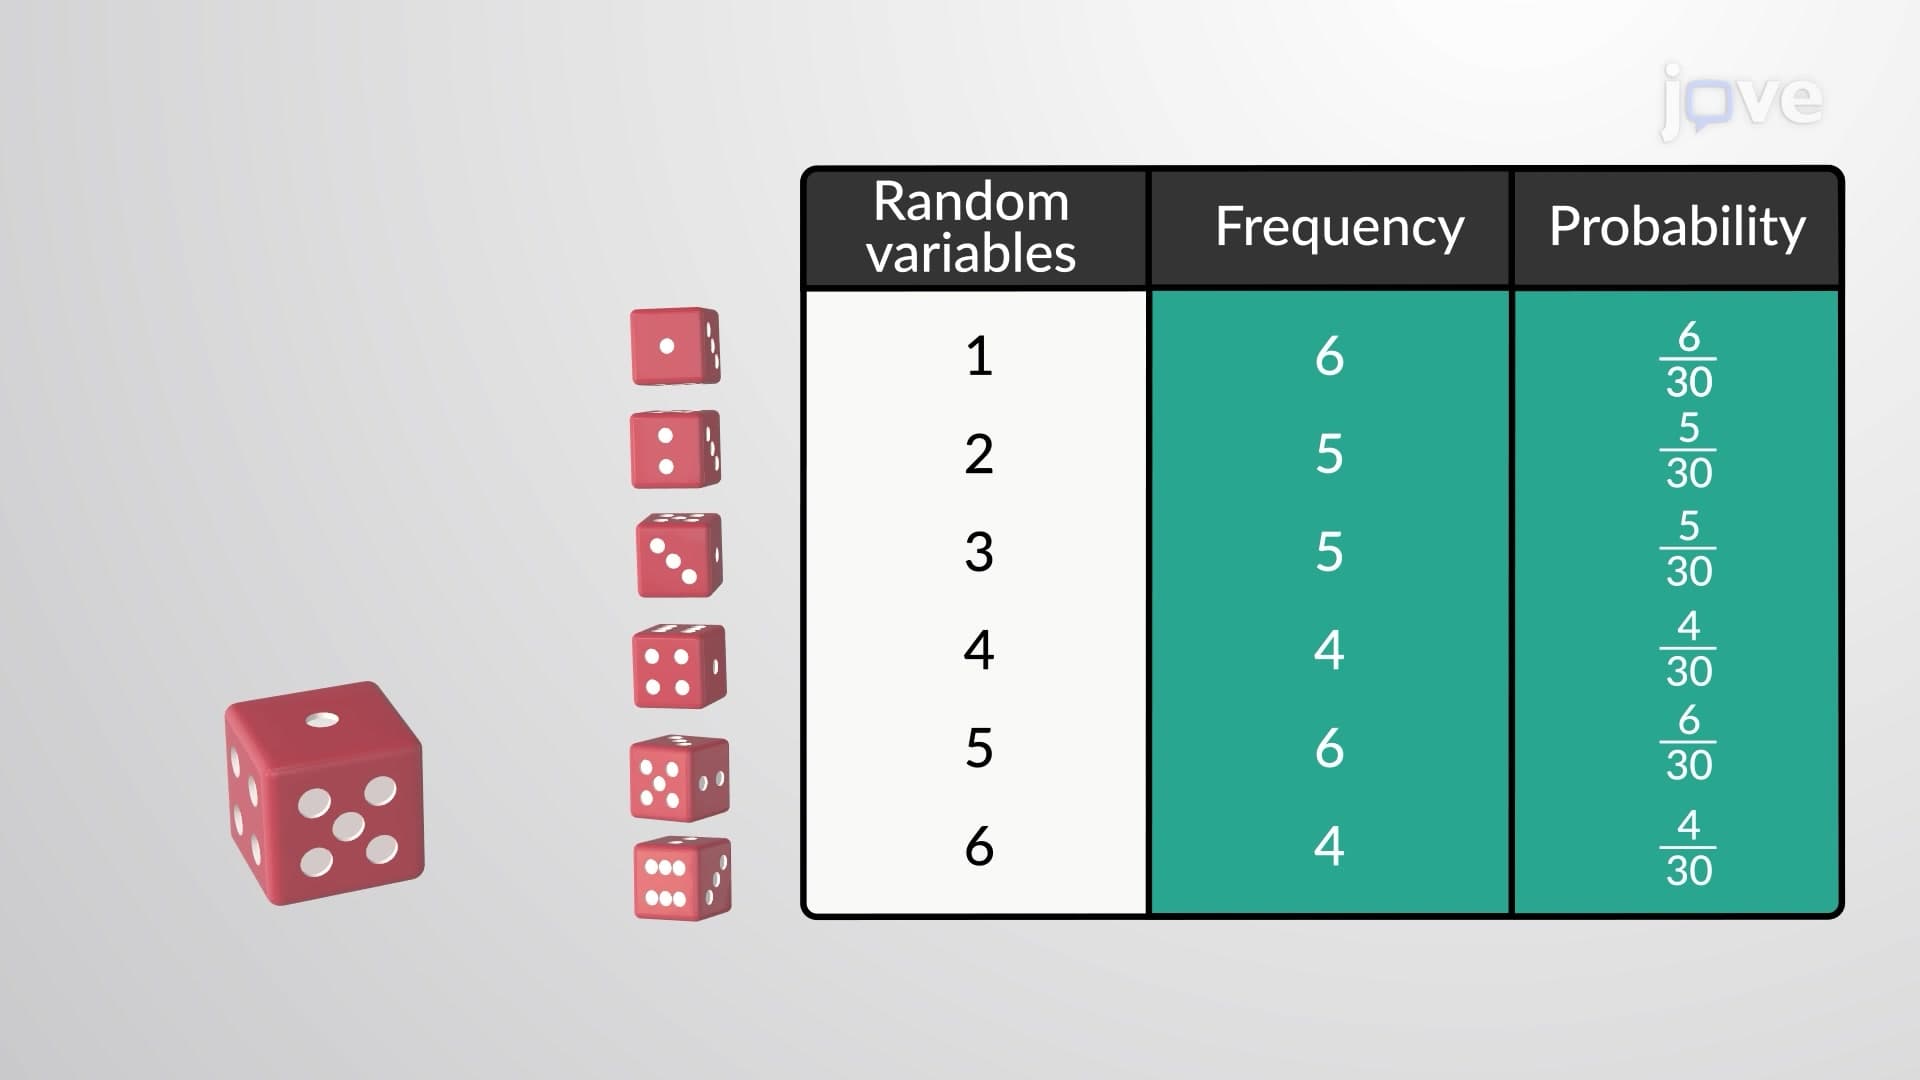
Random Variables
Uppercase letters such as X or Y denote a random variable. Lowercase letters like x or y denote the value of a random variable. If X is a random variable, then X is written in words, and x is given as a number.
For example, let X = the...