Measuring the prediction difficulty of individual cases in a dataset using machine learning
Hyunjin Kwon1,2, Matthew Greenberg3, Colin Bruce Josephson4,5
1Department of Biomedical Engineering, Schulich School of Engineering, University of Calgary, Calgary, Alberta, Canada.

Abstract:
Different levels of prediction difficulty are one of the key factors that researchers encounter when applying machine learning to data. Although previous studies have introduced various metrics for assessing the prediction difficulty of individual cases, these metrics require specific dataset preconditions. In this paper, we propose three novel metrics for measuring the prediction difficulty of individual cases using fully-connected feedforward neural networks. The first metric is based on the complexity of the neural network needed to make a correct prediction. The second metric employs a pair of neural networks: one makes a prediction for a given case, and the other predicts whether the prediction made by the first model is likely to be correct. The third metric assesses the variability of the neural network's predictions. We investigated these metrics using a variety of datasets, visualized their values, and compared them to fifteen existing metrics from the literature. The results demonstrate that the proposed case difficulty metrics were better able to differentiate various levels of difficulty than most of the existing metrics and show constant effectiveness across diverse datasets. We expect our metrics will provide researchers with a new perspective on understanding their datasets and applying machine learning in various fields.
Related Concept Videos
 01:03
Prediction Intervals
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
 01:19
Variation
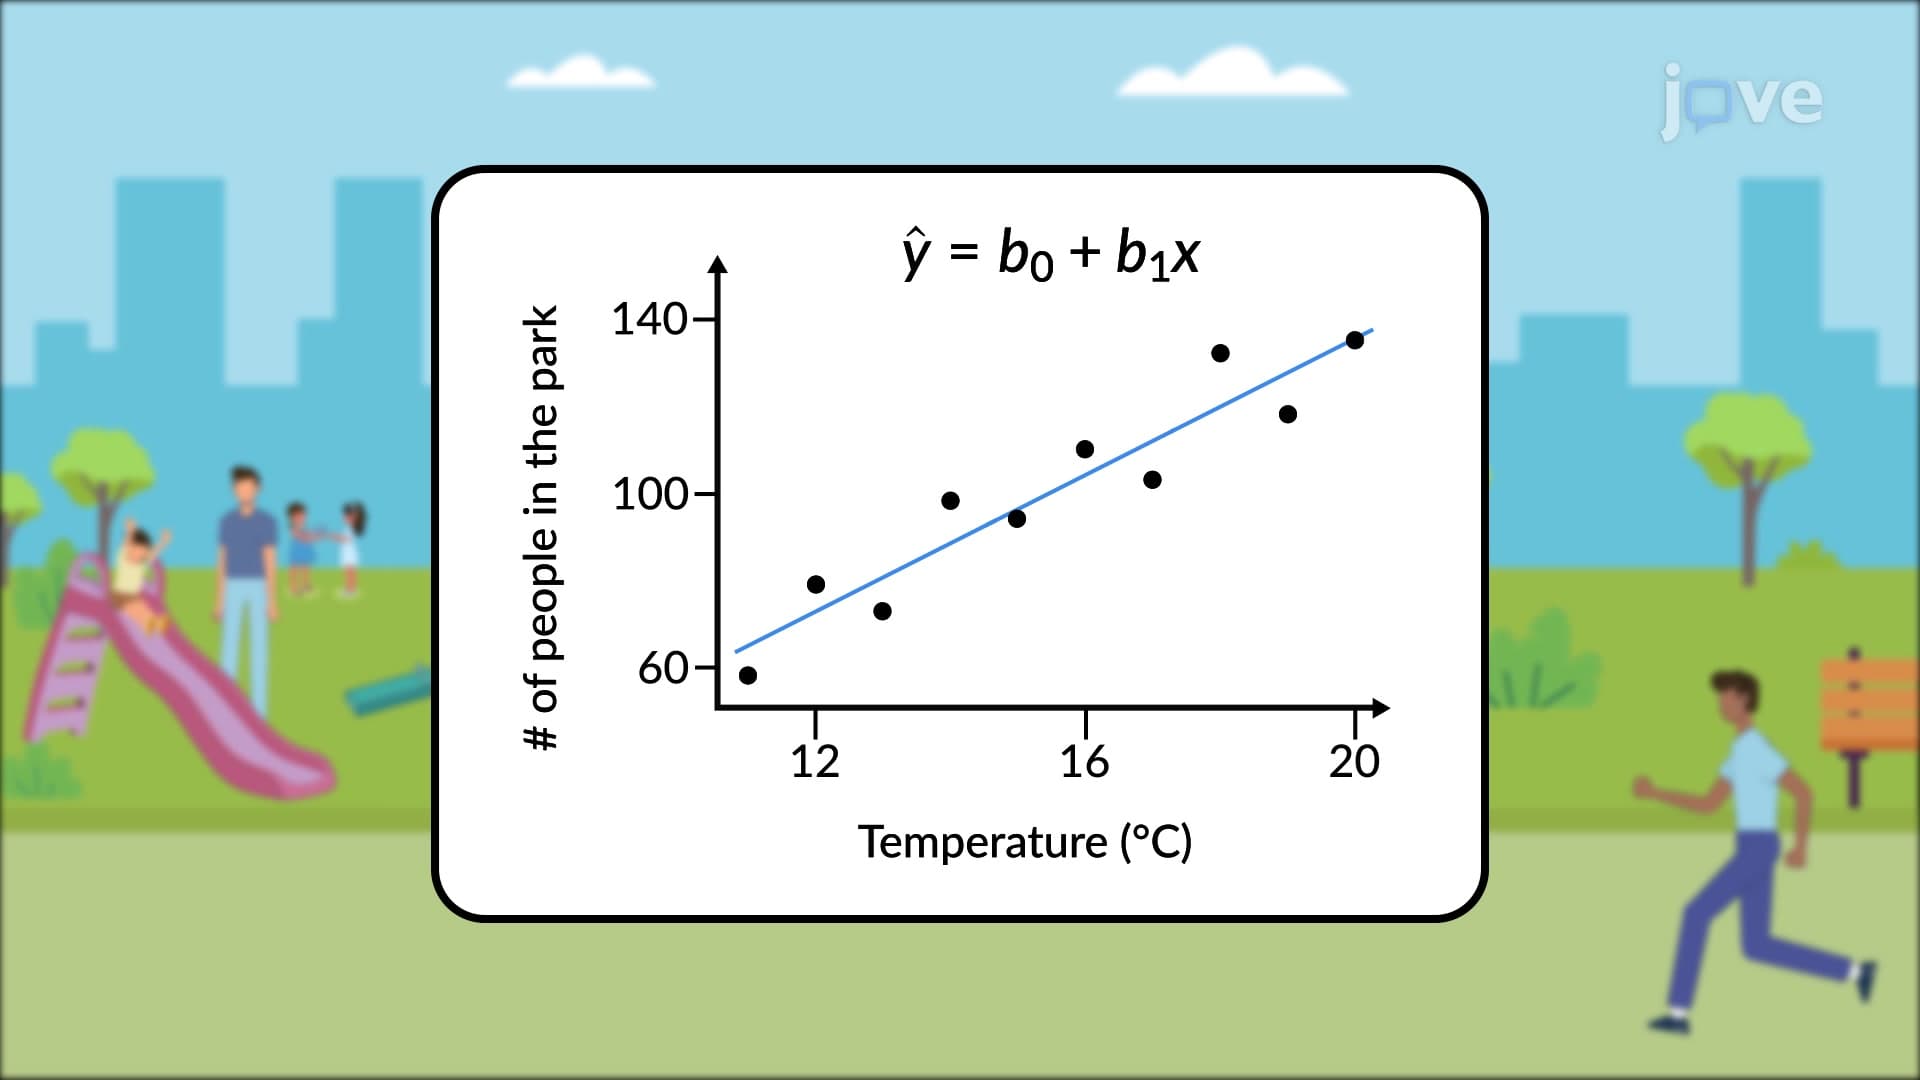
When independent and dependent variables are plotted on a scatter plot, the slope of a line is a value that describes the rate of change between the two...
 01:11
Residuals and Least-Squares Property
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
 01:13
Sensitivity, Specificity, and Predicted Value
Sensitivity is the...
 01:25
Multiple Regression
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
 01:19
Survival Tree
Building a Survival Tree
Constructing a...