Related Experiment Video
Updated: Jun 26, 2025

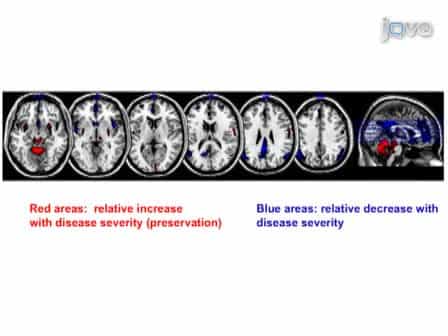
Identification of Disease-related Spatial Covariance Patterns using Neuroimaging Data
Published on: June 26, 2013
Improved clinical data imputation via classical and quantum determinantal point processes
Skander Kazdaghli1, Iordanis Kerenidis1,2, Jens Kieckbusch3
1QC Ware, Paris, France.

Abstract:
Imputing data is a critical issue for machine learning practitioners, including in the life sciences domain, where missing clinical data is a typical situation and the reliability of the imputation is of great importance. Currently, there is no canonical approach for imputation of clinical data and widely used algorithms introduce variance in the downstream classification. Here we propose novel imputation methods based on determinantal point processes (DPP) that enhance popular techniques such as the multivariate imputation by chained equations and MissForest. Their advantages are twofold: improving the quality of the imputed data demonstrated by increased accuracy of the downstream classification and providing deterministic and reliable imputations that remove the variance from the classification results. We experimentally demonstrate the advantages of our methods by performing extensive imputations on synthetic and real clinical data. We also perform quantum hardware experiments by applying the quantum circuits for DPP sampling since such quantum algorithms provide a computational advantage with respect to classical ones. We demonstrate competitive results with up to 10 qubits for small-scale imputation tasks on a state-of-the-art IBM quantum processor. Our classical and quantum methods improve the effectiveness and robustness of clinical data prediction modeling by providing better and more reliable data imputations. These improvements can add significant value in settings demanding high precision, such as in pharmaceutical drug trials where our approach can provide higher confidence in the predictions made.
Related Concept Videos
 01:06
Model Approaches for Pharmacokinetic Data: Distributed Parameter Models
The distributed parameter models are specifically designed to account for variations and differences in some drug classes. This model is particularly useful for assessing regional concentrations of anticancer or...
 00:59
Model-Independent Approaches for Pharmacokinetic Data: Noncompartmental Analysis
One important characteristic of noncompartmental analyses is that drug exposure increases proportionally with increasing doses. This...
 01:14
Model Approaches for Pharmacokinetic Data: Compartment Models
Two primary types of compartment models are recognized: mammillary and catenary. The more...
 01:16
Statistical Inference Techniques in Hypothesis Testing: Parametric Versus Nonparametric Data
Parametric statistics, as the name suggests, assumes that data follow a specific distribution, often a normal distribution. This assumption enables robust hypothesis testing and estimation. Parametric methods, like the Student's t-test or Goodness-of-fit test, are frequently employed in biostatistics due to their robustness. For instance,...
 01:05
Estimation of the Physical Quantities
 01:14
Analysis Methods of Pharmacokinetic Data: Model and Model-Independent Approaches
The model approach uses mathematical models to describe changes in drug concentration over time. Pharmacokinetic models help characterize drug behavior in patients, predict drug concentration in the body fluids, calculate optimum dosage regimens, and evaluate the risk of toxicity. However, ensuring that the model fits the experimental data accurately...