Related Experiment Video
Updated: Jun 26, 2025

Author Spotlight: Soybean Hairy Root Transformation for the Analysis of Gene Function
Published on: May 5, 2023
Does rural transformation affect rural income inequality? Insights from cross-district panel data analysis in
Al Amin Al Abbasi1, Subrata Saha1, Ismat Ara Begum2
1Department of Agribusiness and Marketing, Bangladesh Agricultural University, Mymensingh, 2202, Bangladesh.

Abstract:
Rural transformation plays a crucial role in enhancing the income and employment prospects of the rural labor force. We investigate the effects of rural transformation on rural income inequality at the district level in Bangladesh using data from five years of nationally representative Household Income and Expenditure Surveys. The Gini coefficient is used to measure rural income inequality. In contrast, the share of high-value agricultural outputs and the share of rural non-farm employment are used as indicators of rural transformation. We find that rural income inequality is positively associated with the share of high-value agricultural outputs and the share of rural non-farm employment. The non-linear regression result shows an inverted U-shaped relationship between rural transformation and income inequality, which indicates that income inequality initially increases with rural transformation but decreases in the long run. Additionally, we find that rural income inequality is positively correlated with the proportion of household education expenditures, agricultural rental activity, and the share of remittances. This study also reveals that income inequality in rural areas of Bangladesh has a significant negative correlation with the government's social safety net program.

Related Concept Videos
 01:08
Outliers and Influential Points
 01:06
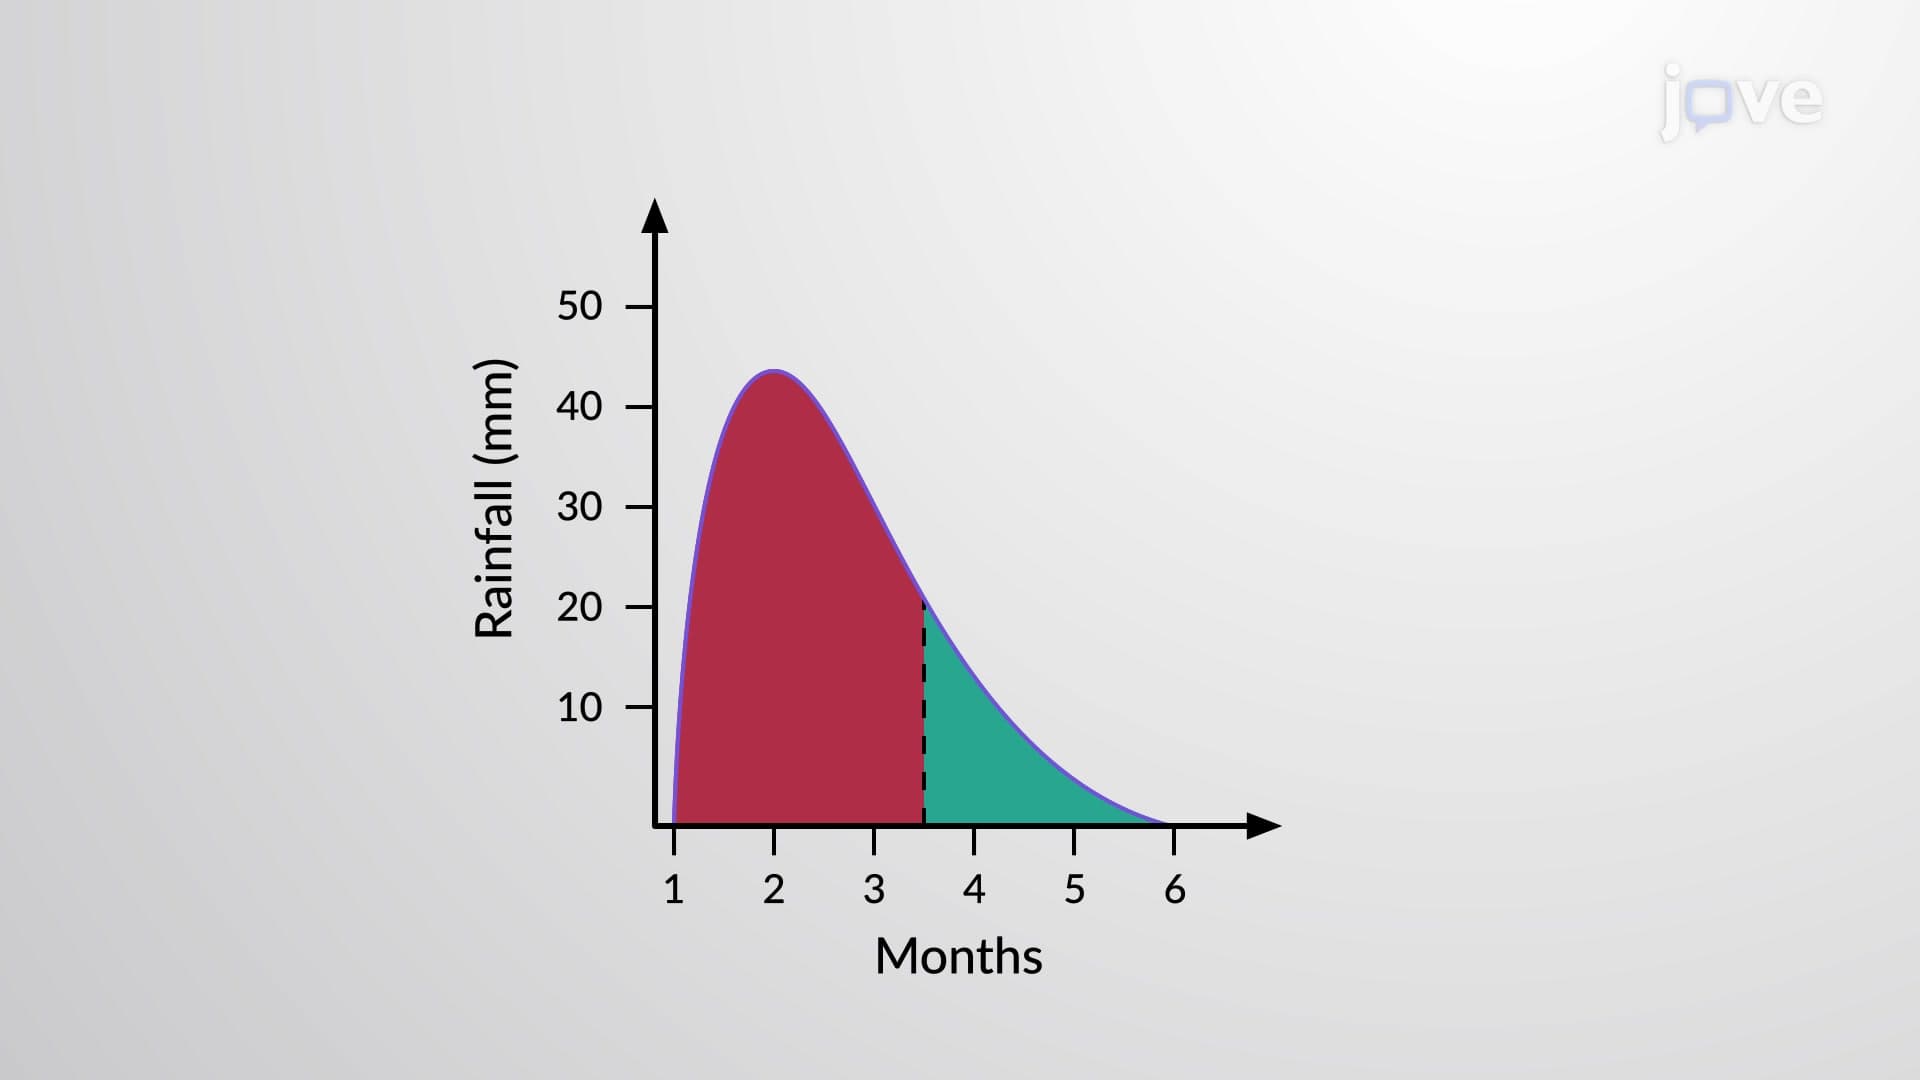
Skewness
The longer the tail of the plot on one side, the more skewed it is. The skewness of a data set’s values suggests that the measures of central tendency...
 01:50
Cross-Sectional Research
 01:20
Cluster Sampling Method
To choose a cluster sample, divide the population into clusters (groups) and then randomly select some of the clusters. All the members from these clusters are in the cluster sample. For example, if you randomly sample four departments from your...
 01:14
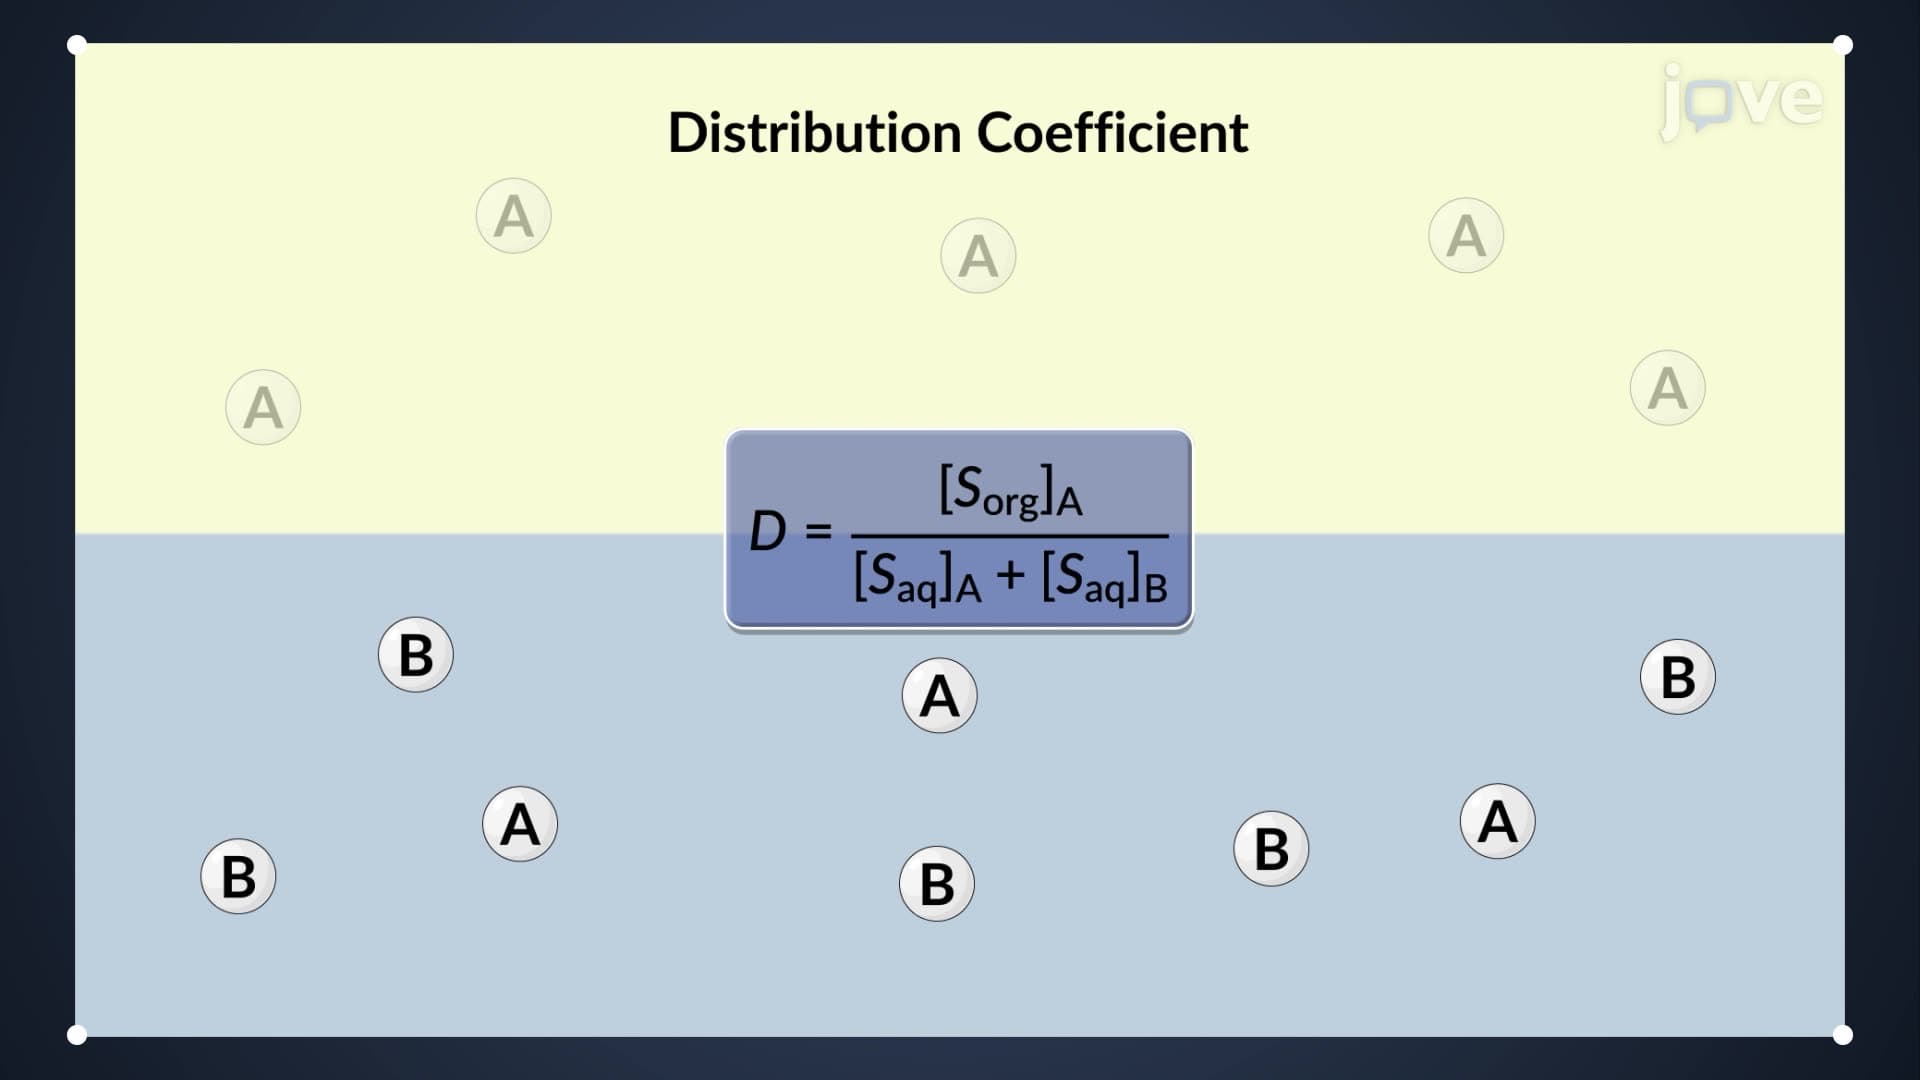
Extraction: Partition and Distribution Coefficients
For extracting a solute from an aqueous phase into an...
 01:21
Friedman Two-way Analysis of Variance by Ranks