Related Experiment Video
Updated: Jun 22, 2025

Lexical Decision Task for Studying Written Word Recognition in Adults with and without Dementia or Mild Cognitive Impairment
Published on: June 25, 2019
A comprehensive dataset for Arabic word sense disambiguation
1Computing and Applied Technology, College of Technological Innovation, Zayed University, UAE.

Abstract:
This data paper introduces a comprehensive dataset tailored for word sense disambiguation tasks, explicitly focusing on a hundred polysemous words frequently employed in Modern Standard Arabic. The dataset encompasses a diverse set of senses for each word, ranging from 3 to 8, resulting in 367 unique senses. Each word sense is accompanied by contextual sentences comprising ten sentence examples that feature the polysemous word in various contexts. The data collection resulted in a dataset of 3670 samples. Significantly, the dataset is in Arabic, which is known for its rich morphology, complex syntax, and extensive polysemy. The data was meticulously collected from various web sources, spanning news, medicine, finance, and more domains. This inclusivity ensures the dataset's applicability across diverse fields, positioning it as a pivotal resource for Arabic Natural Language Processing (NLP) applications. The data collection timeframe spans from the first of April 2023 to the first of May 2023. The dataset provides comprehensive model learning by including all senses for a frequently used Arabic polysemous term, even rare senses that are infrequently used in real-world contexts, thereby mitigating biases. The dataset comprises synthetic sentences generated by GPT3.5-turbo, addressing instances where rare senses lack sufficient real-world data. The dataset collection process involved initial web scraping, followed by manual sorting to distinguish word senses, supplemented by thorough searches by a human expert to fill in missing contextual sentences. Finally, in instances where online data for rare word senses was lacking or insufficient, synthetic samples were generated. Beyond its primary utility in word sense disambiguation, this dataset holds considerable value for scientists and researchers across various domains, extending its relevance to sentiment analysis applications.
More Related Videos
 12:49
Transcranial Direct Current Stimulation tDCS of Wernicke's and Broca's Areas in Studies of Language Learning and Word Acquisition
Published on: July 13, 2019
 09:20
Cloud-Based Phrase Mining and Analysis of User-Defined Phrase-Category Association in Biomedical Publications
Published on: February 23, 2019
Related Concept Videos
 01:11
Nomenclature of Aromatic Compounds with Multiple Substituents
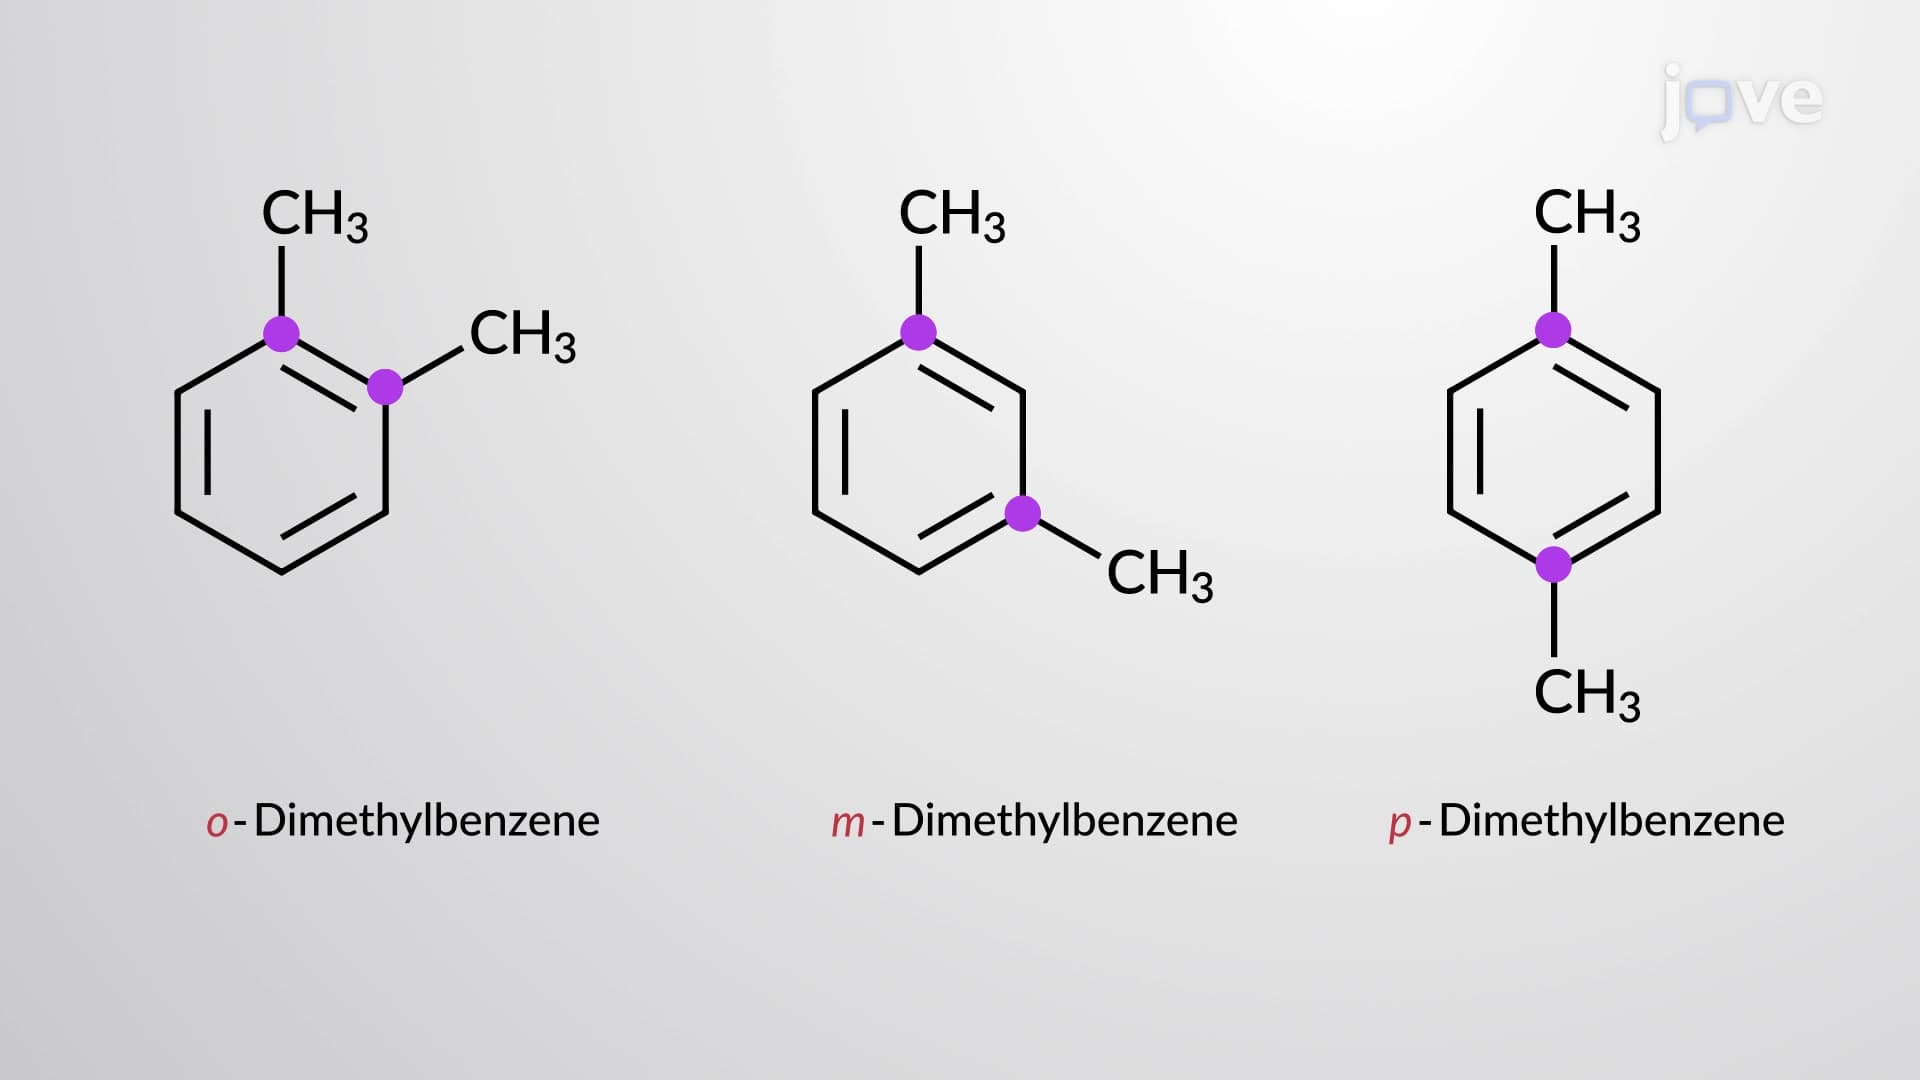
For disubstituted benzene derivatives, with two groups attached to the benzene ring, three constitutional isomers are possible. For example, consider dimethyl benzene, often called xylene, where the second methyl group can be substituted at the second, third, or fourth carbon. The relative position of the substituents is represented by prefixes ortho, meta, or...
 01:29
Aggregates Classification
Petrographic classification groups aggregates based on common mineralogical characteristics. Some of the common mineral groups found in aggregates are...
 01:12
Regional Terms
Primarily, the human body has two major regions, the axial and appendicular regions. The axial region comprises regions from the head to the abdomen and makes up the central body axis. In contrast,...
 03:36
Genome Annotation and Assembly
 01:23
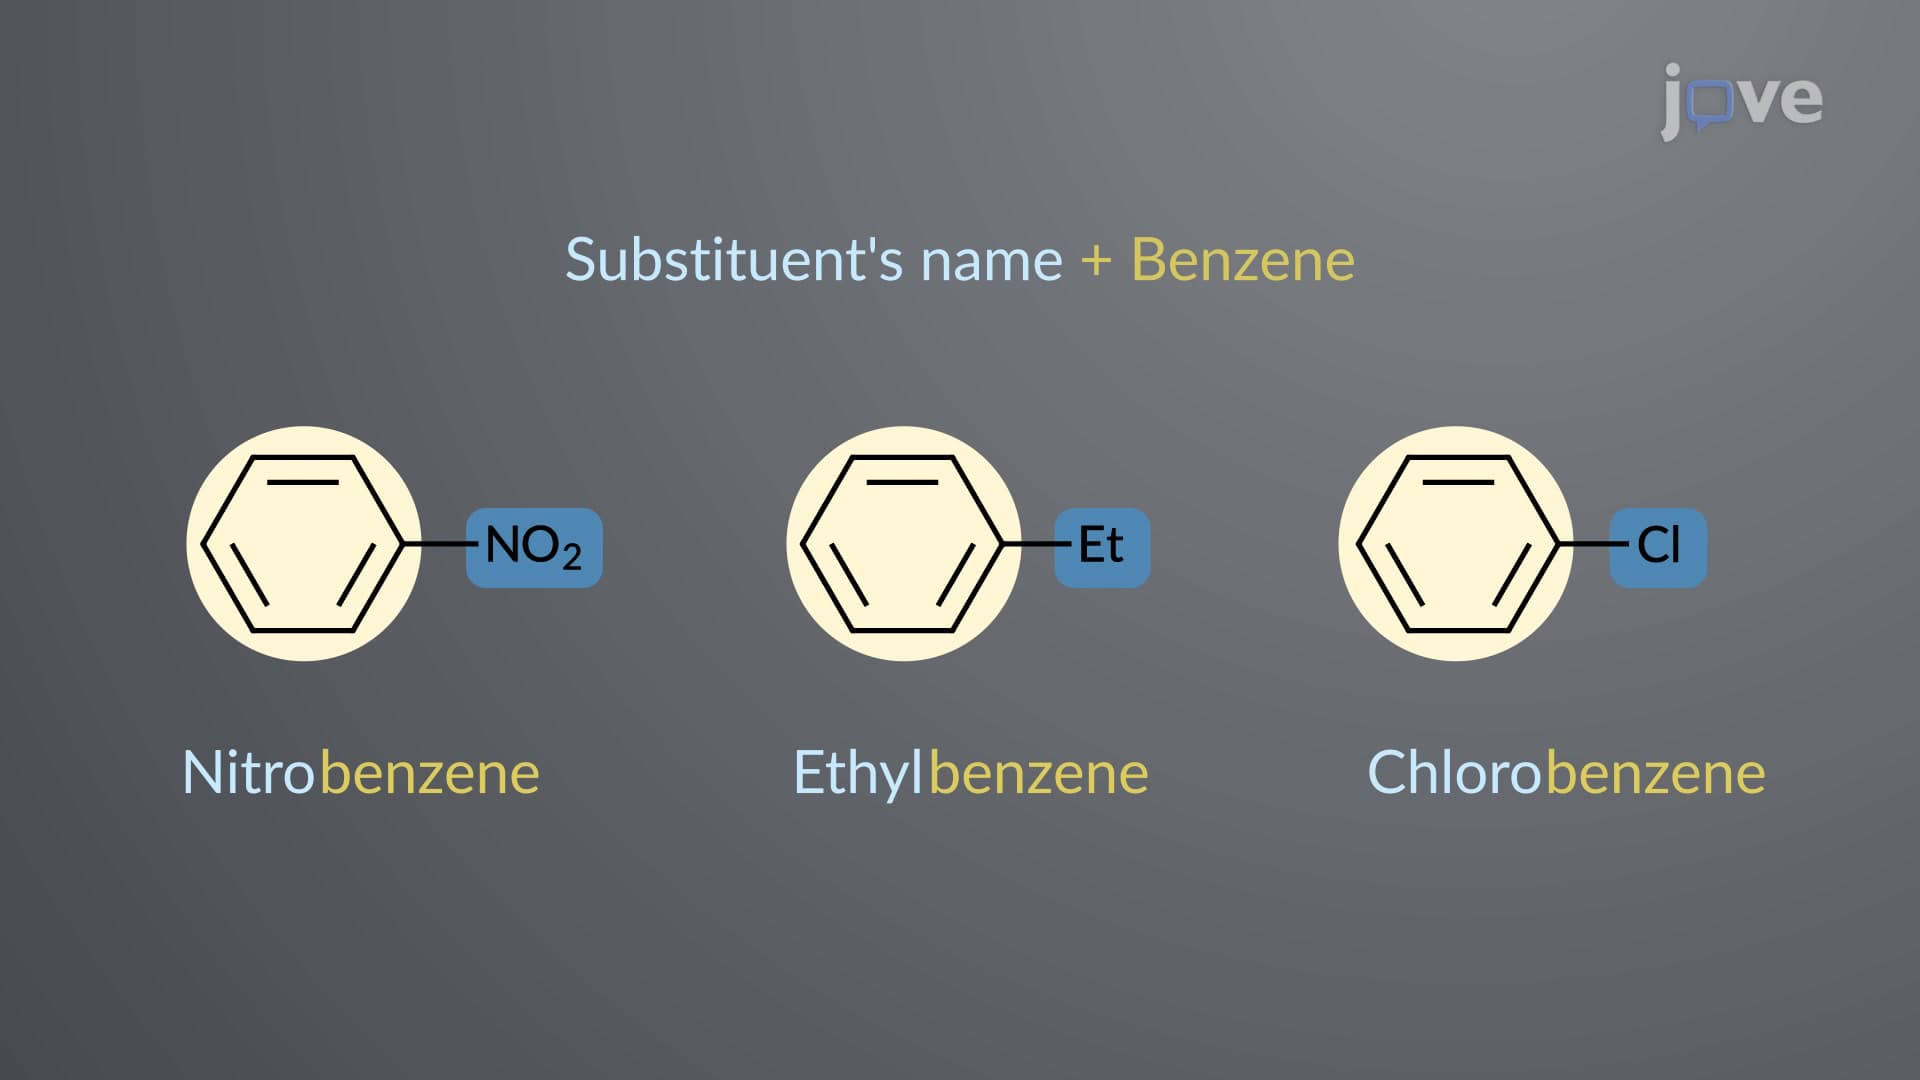
Nomenclature of Aromatic Compounds with a Single Substituent
 01:25
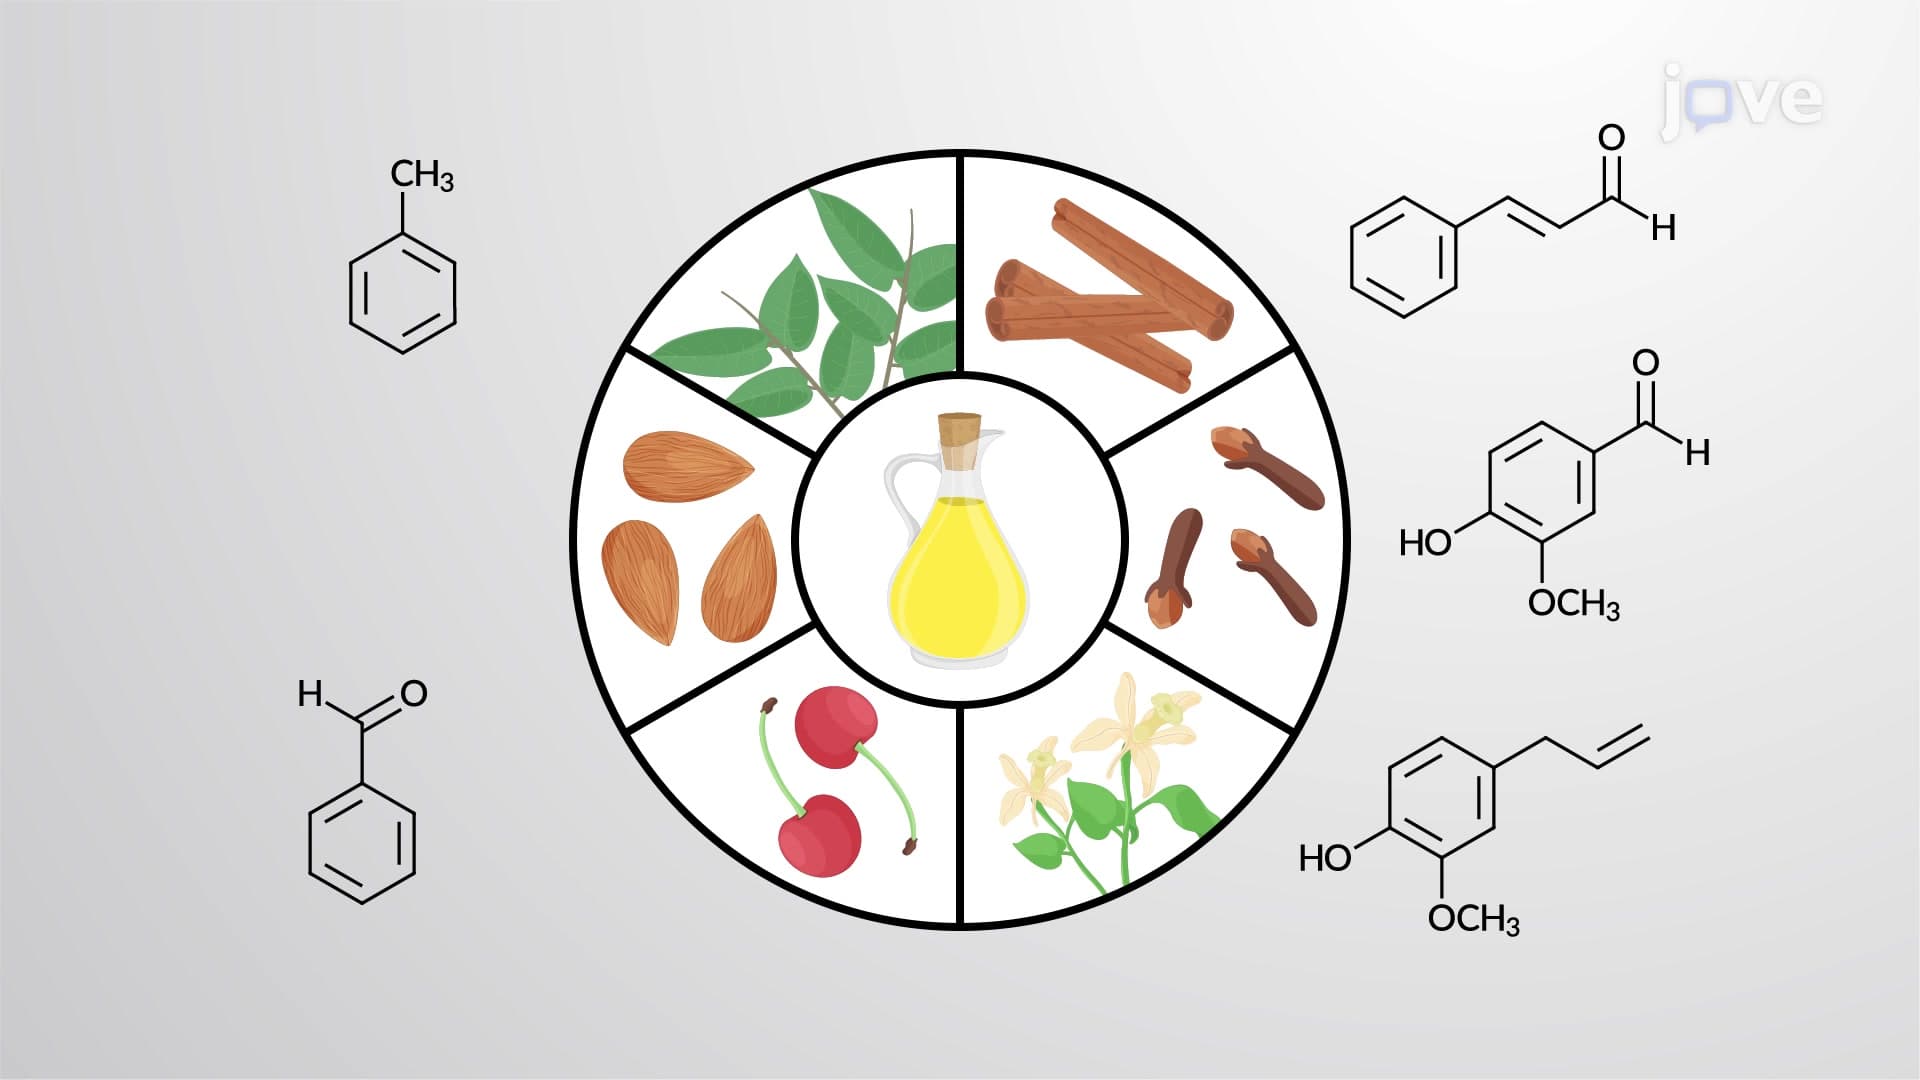
Aromatic Compounds: Overview
In 1825, Faraday...