Related Experiment Video
Updated: Jun 17, 2025
A Metadata Extraction Approach for Clinical Case Reports to Enable Advanced Understanding of Biomedical Concepts
Published on: September 20, 2018
Annotation Vocabulary (Might Be) All You Need
Logan Hallee1, Niko Rafailidis1, Colin Horger2
1Center for Bioinformatics and Computational Biology, University of Delaware.

Abstract:
Protein Language Models (pLMs) have revolutionized the computational modeling of protein systems, building numerical embeddings that are centered around structural features. To enhance the breadth of biochemically relevant properties available in protein embeddings, we engineered the Annotation Vocabulary, a transformer readable language of protein properties defined by structured ontologies. We trained Annotation Transformers (AT) from the ground up to recover masked protein property inputs without reference to amino acid sequences, building a new numerical feature space on protein descriptions alone. We leverage AT representations in various model architectures, for both protein representation and generation. To showcase the merit of Annotation Vocabulary integration, we performed 515 diverse downstream experiments. Using a novel loss function and only $3 in commercial compute, our premier representation model CAMP produces state-of-the-art embeddings for five out of 15 common datasets with competitive performance on the rest; highlighting the computational efficiency of latent space curation with Annotation Vocabulary. To standardize the comparison of de novo generated protein sequences, we suggest a new sequence alignment-based score that is more flexible and biologically relevant than traditional language modeling metrics. Our generative model, GSM, produces high alignment scores from annotation-only prompts with a BERT-like generation scheme. Of particular note, many GSM hallucinations return statistically significant BLAST hits, where enrichment analysis shows properties matching the annotation prompt - even when the ground truth has low sequence identity to the entire training set. Overall, the Annotation Vocabulary toolbox presents a promising pathway to replace traditional tokens with members of ontologies and knowledge graphs, enhancing transformer models in specific domains. The concise, accurate, and efficient descriptions of proteins by the Annotation Vocabulary offers a novel way to build numerical representations of proteins for protein annotation and design.
More Related Videos
 07:26
Executing Complexity-Increasing Queries in Relational MySQL and NoSQL MongoDB and EXist Size-Growing ISO/EN 13606 Standardized EHR Databases
Published on: March 19, 2018
 10:23
Author Spotlight: Three-Dimensional Cephalometric Landmark Annotation Demonstration on Human Cone Beam Computed Tomography Scans
Published on: September 8, 2023
Related Concept Videos
 01:42
Schemas
 01:17
Schemata
Two types of schemata are:
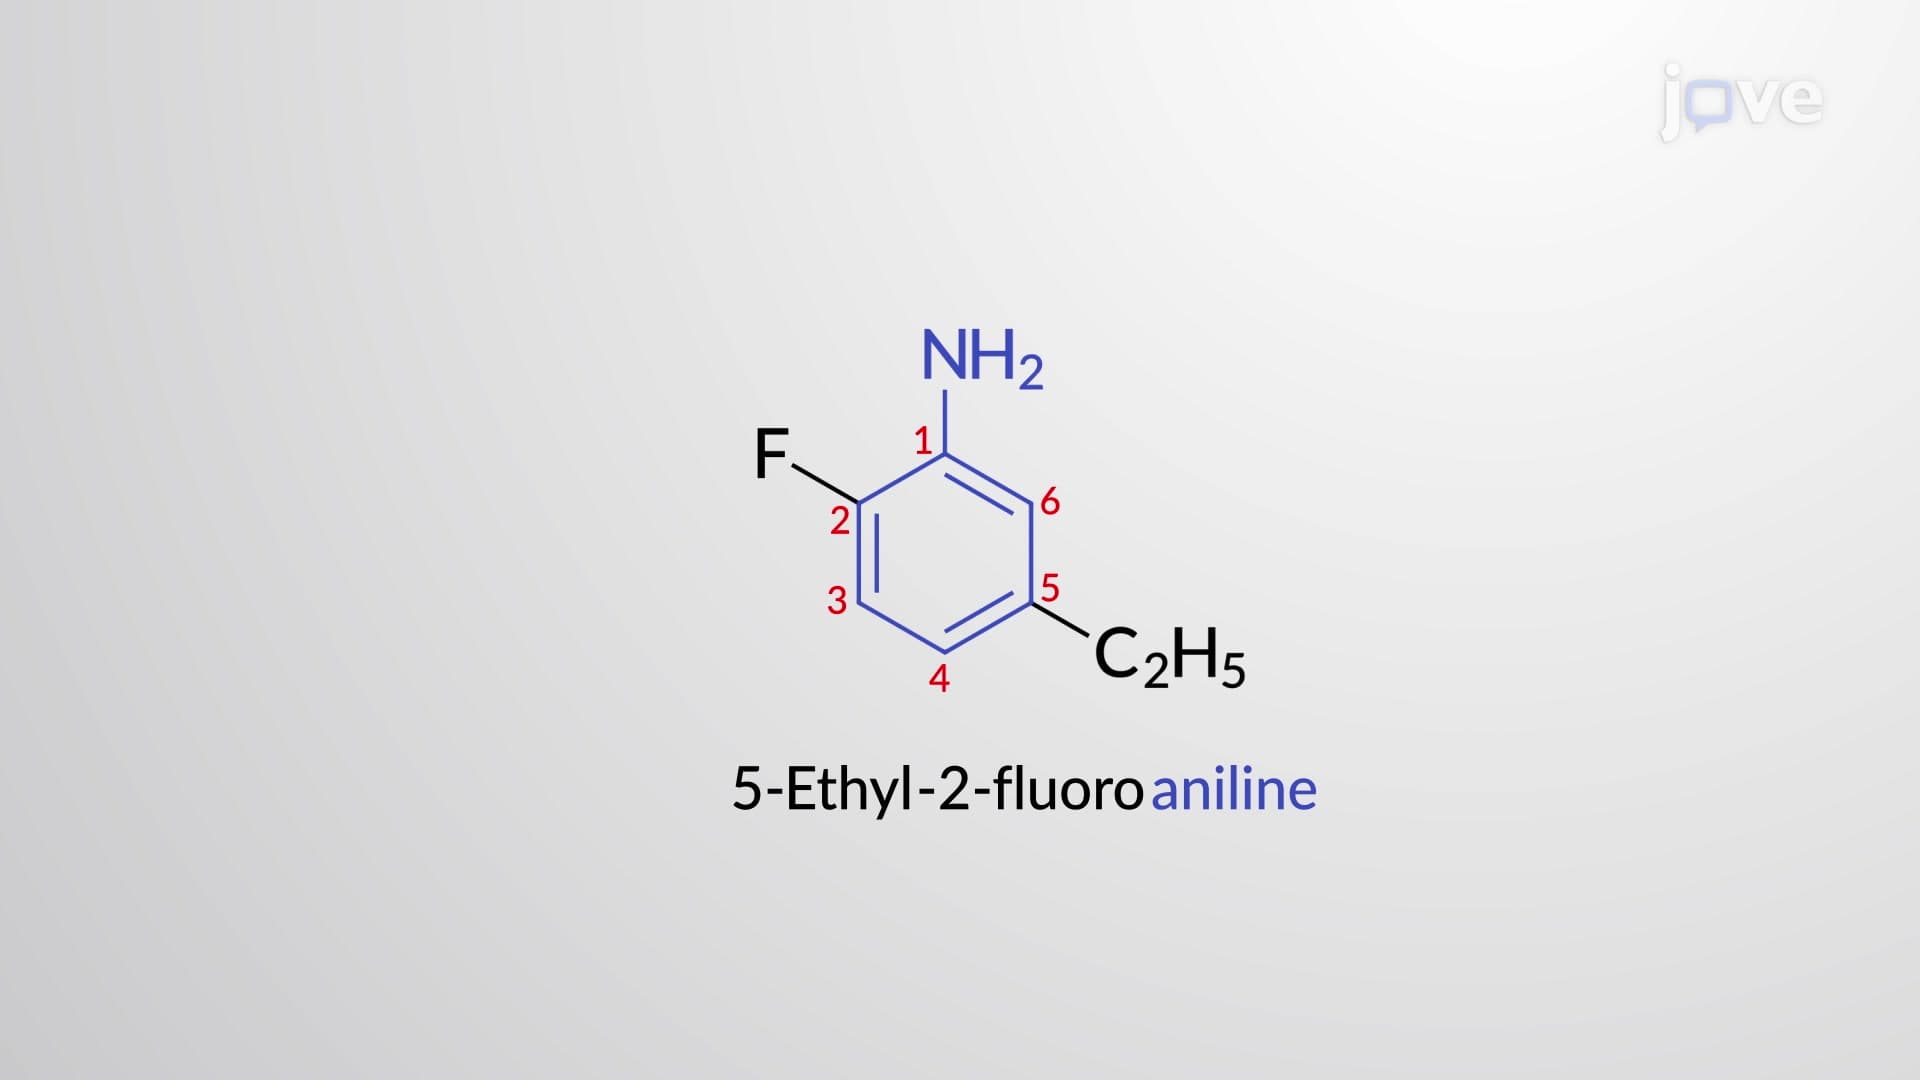 01:10
Nomenclature of Aryl and Heterocyclic Amines
 02:16
Self-Schemas
 01:29
Aggregates Classification
Petrographic classification groups aggregates based on common mineralogical characteristics. Some of the common mineral groups found in aggregates are...
 01:11
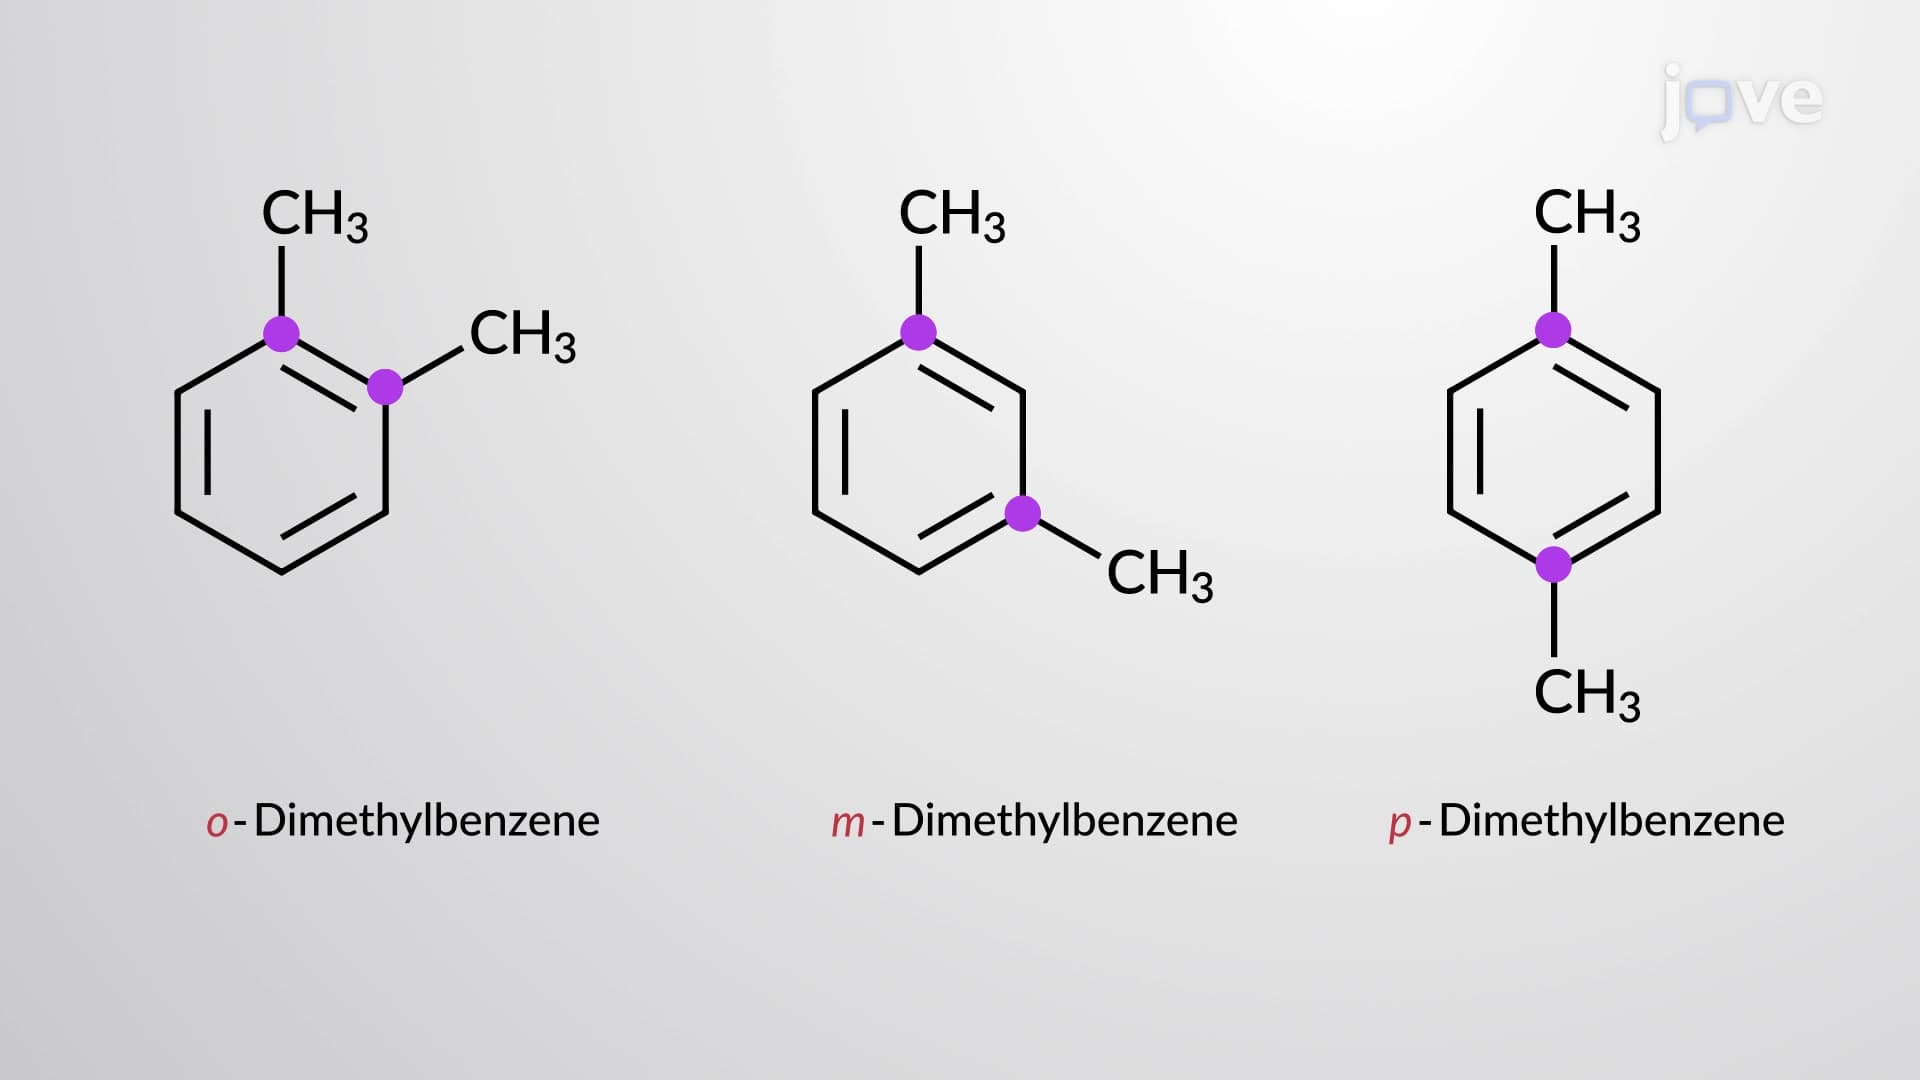
Nomenclature of Aromatic Compounds with Multiple Substituents
For disubstituted benzene derivatives, with two groups attached to the benzene ring, three constitutional isomers are possible. For example, consider dimethyl benzene, often called xylene, where the second methyl group can be substituted at the second, third, or fourth carbon. The relative position of the substituents is represented by prefixes ortho, meta, or...