
Health and income inequality: a comparative analysis of USA and Italy
Caterina A M La Porta1,2, Stefano Zapperi3,4
1Center for Complexity and Biosystems and Center for Innovation for Well-Being And Environment, Department of Environmental Science and Policy, University of Milan, Milan, Italy.

Introduction:
Socio-economic background is often an important determinant for health with low income households having higher exposure to risk factors and diminished access to healthcare and prevention, in a way that is specific to each country.
Methods:
Here, we perform a comparative analysis of the relations between health and income inequality in two developed countries, USA and Italy, using longitudinal and cross-sectional data from surveys.
Results And Discussion:
We show that the income class determines the incidence of chronic pathologies, associated risk-factors and psychiatric conditions, but find striking differences in health inequality between the two countries. We then focus our attention on a fraction of very disadvantaged households in the USA whose income in persistently at the bottom of the distribution over a span of 20 years and which is shown to display particularly dire health conditions. Low income people in the USA also display comorbidity patterns that are not found in higher income people, while in Italy income appears to be less relevant for comorbidity. Taken together our findings illustrate how differences in lifestyle and the healthcare systems affect health inequality.

Related Concept Videos
 01:29
Bias in Epidemiological Studies
 01:06
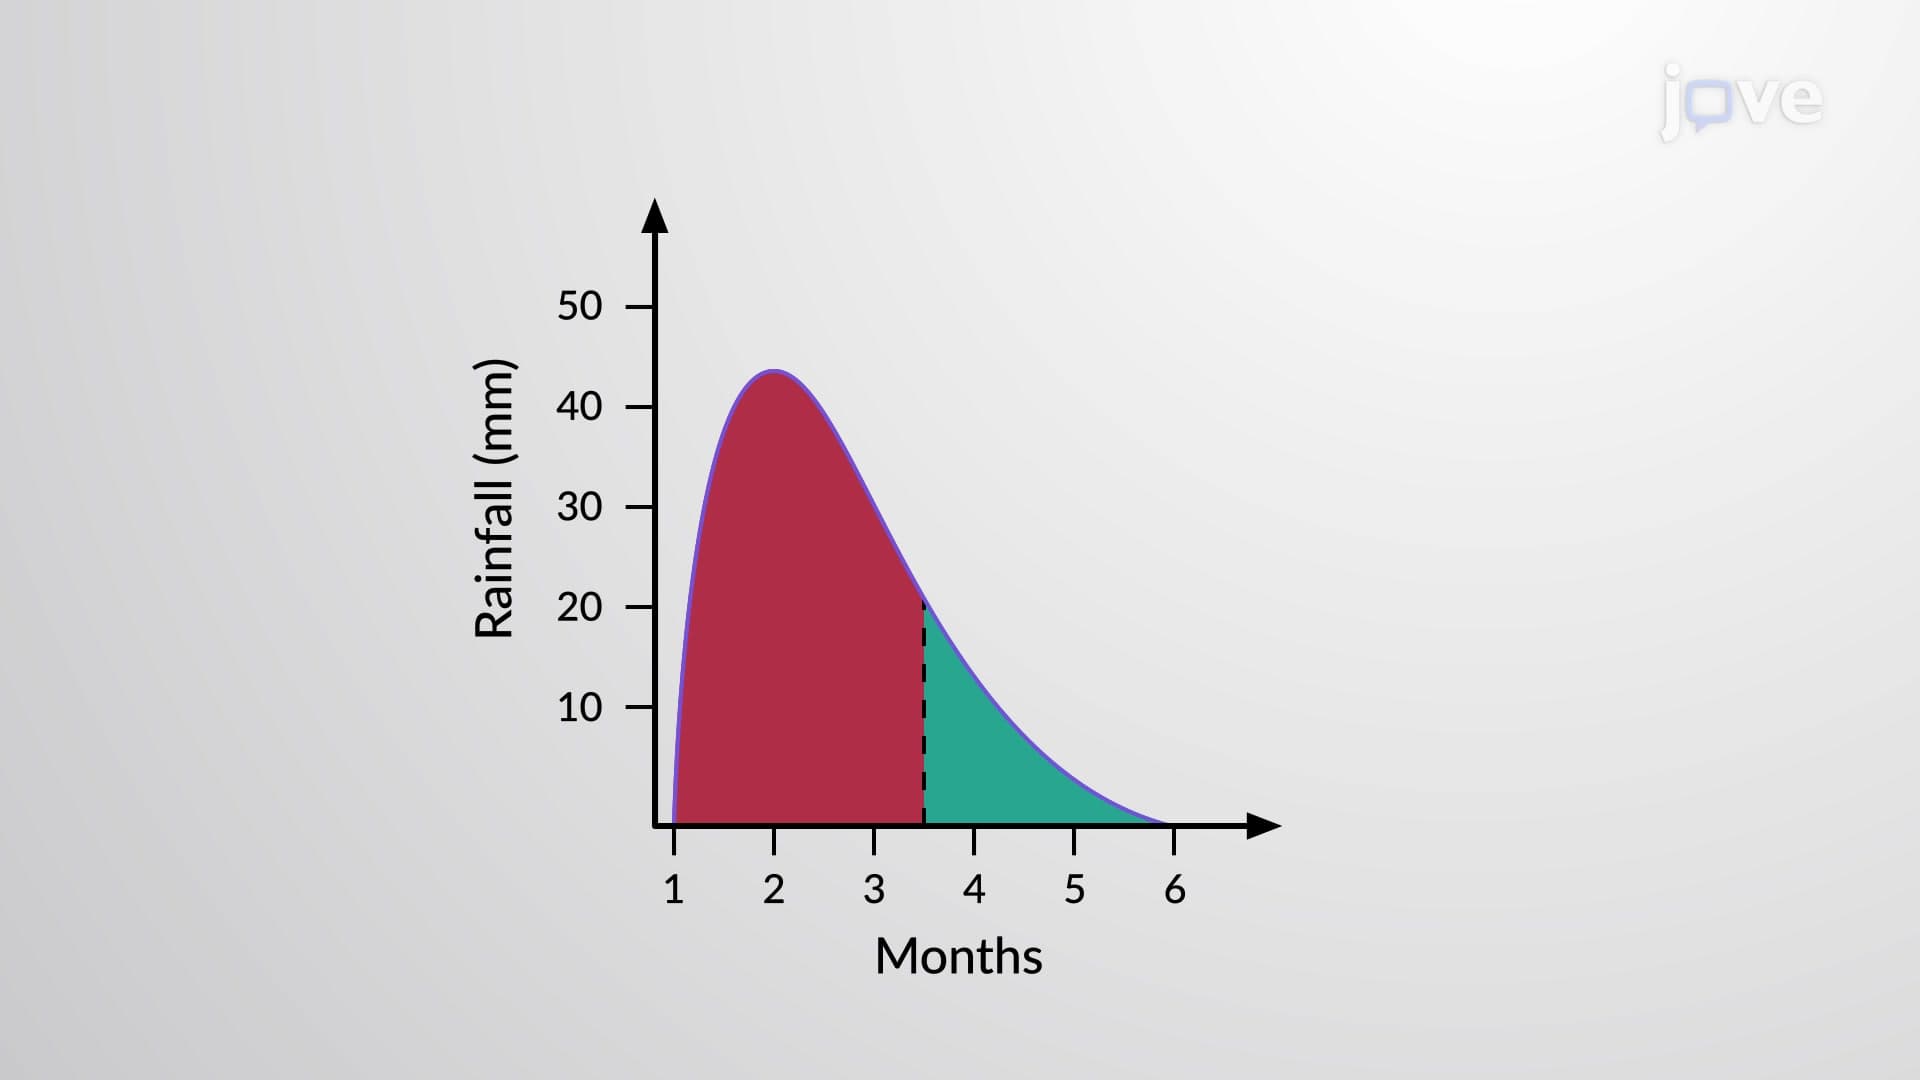
Skewness
The longer the tail of the plot on one side, the more skewed it is. The skewness of a data set’s values suggests that the measures of central tendency...
 01:23
Test for Homogeneity
 01:08
Outliers and Influential Points
 02:16
Measures of Central Tendency
 01:14
Wilcoxon Signed-Ranks Test for Median of Single Population