Vision language models in ophthalmology
Related Experiment Video
Updated: Jun 13, 2025
Development of a Gaze-Contingent Display Framework Designed for Perceptual and Oculomotor Research with Simulated Central Vision Loss
Published on: April 11, 2025
Gilbert Lim1, Kabilan Elangovan1, Liyuan Jin2
1SingHealth.

Purpose Of Review:
Vision Language Models are an emerging paradigm in artificial intelligence that offers the potential to natively analyze both image and textual data simultaneously, within a single model. The fusion of these two modalities is of particular relevance to ophthalmology, which has historically involved specialized imaging techniques such as angiography, optical coherence tomography, and fundus photography, while also interfacing with electronic health records that include free text descriptions. This review then surveys the fast-evolving field of Vision Language Models as they apply to current ophthalmologic research and practice.
Recent Findings:
Although models incorporating both image and text data have a long provenance in ophthalmology, effective multimodal Vision Language Models are a recent development exploiting advances in technologies such as transformer and autoencoder models.
Summary:
Vision Language Models offer the potential to assist and streamline the existing clinical workflow in ophthalmology, whether previsit, during, or post-visit. There are, however, also important challenges to be overcome, particularly regarding patient privacy and explainability of model recommendations.
More Related Videos
Related Concept Videos
 01:24
Vision
 01:25
Glaucoma: Overview
 01:28
Angle Closure Glaucoma: Treatment
 01:27
Open Angle Glaucoma: Treatment
Drugs such as carbonic anhydrase inhibitors, α2- and...
 01:26
Visual System
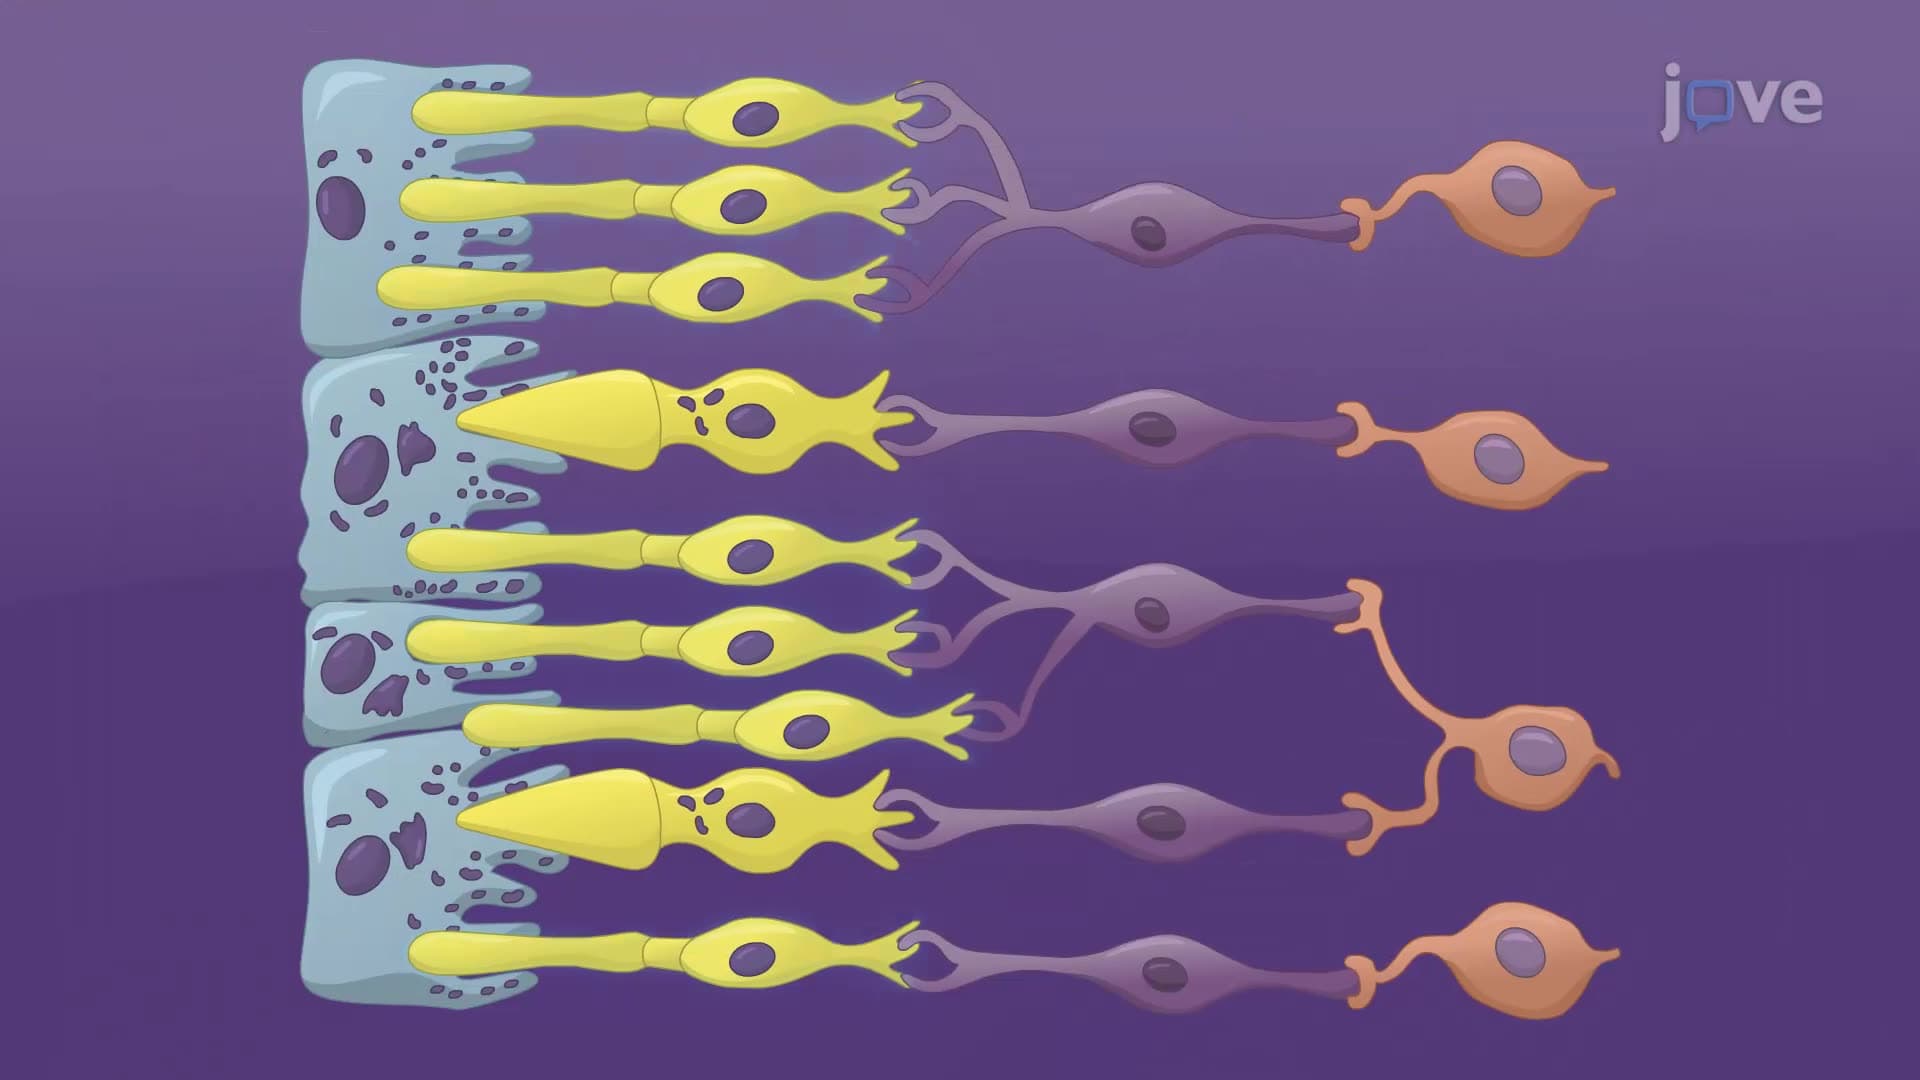
Once through the pupil, the light passes through the lens, a...
 01:22
Photoreceptors and Visual Pathways