Related Experiment Video
Updated: Jun 12, 2025
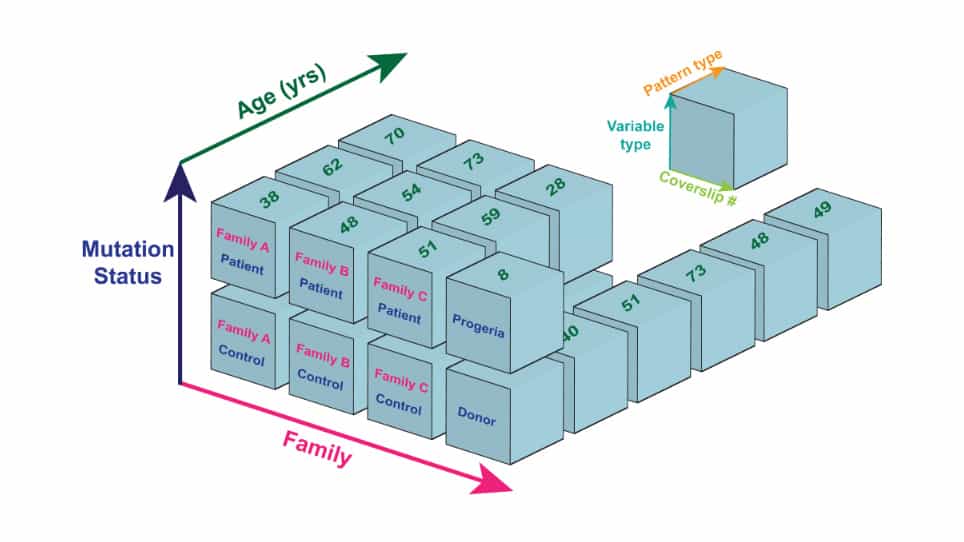

Databases to Efficiently Manage Medium Sized, Low Velocity, Multidimensional Data in Tissue Engineering
Published on: November 22, 2019
Hyperdimensional computing: A fast, robust, and interpretable paradigm for biological data
Michiel Stock1, Wim Van Criekinge2, Dimitri Boeckaerts1,3
1KERMIT Research Unit, Department of Data Analysis and Mathematical Modelling, Ghent University, Ghent, Belgium.

Abstract:
Advances in bioinformatics are primarily due to new algorithms for processing diverse biological data sources. While sophisticated alignment algorithms have been pivotal in analyzing biological sequences, deep learning has substantially transformed bioinformatics, addressing sequence, structure, and functional analyses. However, these methods are incredibly data-hungry, compute-intensive, and hard to interpret. Hyperdimensional computing (HDC) has recently emerged as an exciting alternative. The key idea is that random vectors of high dimensionality can represent concepts such as sequence identity or phylogeny. These vectors can then be combined using simple operators for learning, reasoning, or querying by exploiting the peculiar properties of high-dimensional spaces. Our work reviews and explores HDC's potential for bioinformatics, emphasizing its efficiency, interpretability, and adeptness in handling multimodal and structured data. HDC holds great potential for various omics data searching, biosignal analysis, and health applications.