Related Experiment Video
Updated: May 4, 2026

A Step-by-Step Implementation of DeepBehavior, Deep Learning Toolbox for Automated Behavior Analysis
Published on: February 6, 2020
Lazy Resampling: Fast and information preserving preprocessing for deep learning
Benjamin Murray1, Richard Brown1, Pengcheng Ma2
1School of Biomedical Engineering & Imaging Sciences, King's College London, London, UK.

Background And Objective:
Preprocessing of data is a vital step for almost all deep learning workflows. In computer vision, manipulation of data intensity and spatial properties can improve network stability and can provide an important source of generalisation for deep neural networks. Models are frequently trained with preprocessing pipelines composed of many stages, but these pipelines come with a drawback; each stage that resamples the data costs time, degrades image quality, and adds bias to the output. Long pipelines can also be complex to design, especially in medical imaging, where cropping data early can cause significant artifacts.
Methods:
We present Lazy Resampling, a software that rephrases spatial preprocessing operations as a graphics pipeline. Rather than each transform individually modifying the data, the transforms generate transform descriptions that are composited together into a single resample operation wherever possible. This reduces pipeline execution time and, most importantly, limits signal degradation. It enables simpler pipeline design as crops and other operations become non-destructive. Lazy Resampling is designed in such a way that it provides the maximum benefit to users without requiring them to understand the underlying concepts or change the way that they build pipelines.
Results:
We evaluate Lazy Resampling by comparing traditional pipelines and the corresponding lazy resampling pipeline for the following tasks on Medical Segmentation Decathlon datasets. We demonstrate lower information loss in lazy pipelines vs. traditional pipelines. We demonstrate that Lazy Resampling can avoid catastrophic loss of semantic segmentation label accuracy occurring in traditional pipelines when passing labels through a pipeline and then back through the inverted pipeline. Finally, we demonstrate statistically significant improvements when training UNets for semantic segmentation.
Conclusion:
Lazy Resampling reduces the loss of information that occurs when running processing pipelines that traditionally have multiple resampling steps and enables researchers to build simpler pipelines by making operations such as rotation and cropping effectively non-destructive. It makes it possible to invert labels back through a pipeline without catastrophic loss of accuracy. A reference implementation for Lazy Resampling can be found at https://github.com/KCL-BMEIS/LazyResampling. Lazy Resampling is being implemented as a core feature in MONAI, an open source python-based deep learning library for medical imaging, with a roadmap for a full integration.
Related Concept Videos
 01:06
Sampling Methods: Overview
In analytical chemistry, the choice of...
 01:20
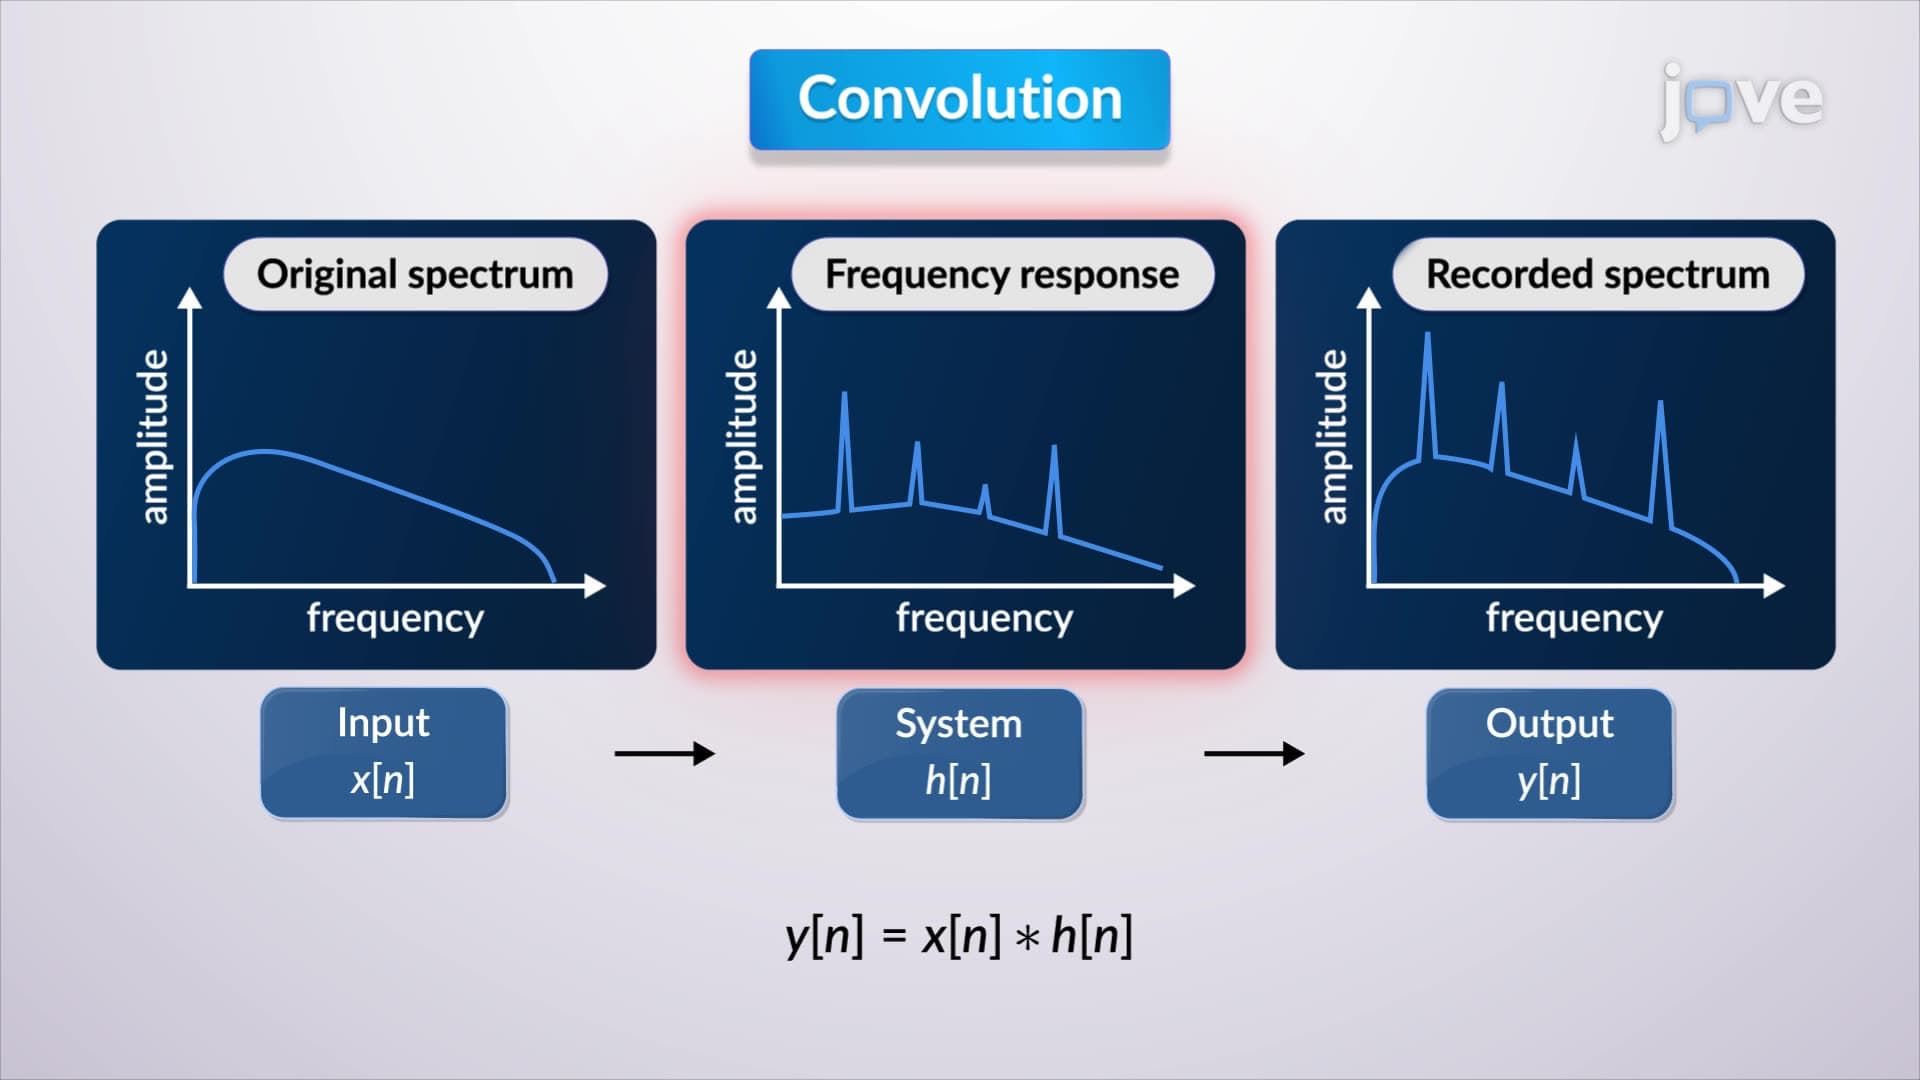
Deconvolution
Deconvolution involves several mathematical techniques to derive the impulse response. One common approach is polynomial division. In this method, the input and output sequences are treated as coefficients of...
 01:11
Sampling Continuous Time Signal
In the...
 01:10
Reconstruction of Signal using Interpolation
 01:20
Downsampling
The Fourier transform of the decimated sequence reveals a combination of scaled and shifted versions of the original spectrum. This...
 01:22
Upsampling