Deblurring Videos Using Spatial-Temporal Contextual Transformer With Feature Propagation
Related Experiment Video
Updated: Jun 9, 2025
Profiling Maternal Behavior Responses During Whole-Brain Imaging
Published on: January 24, 2025

Abstract:
We present a simple and effective approach to explore both local spatial-temporal contexts and non-local temporal information for video deblurring. First, we develop an effective spatial-temporal contextual transformer to explore local spatial-temporal contexts from videos. As the features extracted by the spatial-temporal contextual transformer does not model the non-local temporal information of video well, we then develop a feature propagation method to aggregate useful features from the long-range frames so that both local spatial-temporal contexts and non-local temporal information can be better utilized for video deblurring. Finally, we formulate the spatial-temporal contextual transformer with the feature propagation into a unified deep convolutional neural network (CNN) and train it in an end-to-end manner. We show that using the spatial-temporal contextual transformer with the feature propagation is able to generate useful features and makes the deep CNN model more compact and effective for video deblurring. Extensive experimental results show that the proposed method performs favorably against state-of-the-art ones on the benchmark datasets in terms of accuracy and model parameters.
More Related Videos
 13:13
Time-Lapse Imaging of Neuronal Arborization using Sparse Adeno-Associated Virus Labeling of Genetically Targeted Retinal Cell Populations
Published on: March 19, 2021
 08:25
Combining Eye-tracking Data with an Analysis of Video Content from Free-viewing a Video of a Walk in an Urban Park Environment
Published on: May 7, 2019
Related Concept Videos
 01:20
Deconvolution
Deconvolution involves several mathematical techniques to derive the impulse response. One common approach is polynomial division. In this method, the input and output sequences are treated as coefficients of...
 01:20
Downsampling
The Fourier transform of the decimated sequence reveals a combination of scaled and shifted versions of the original spectrum. This...
 01:15
Depth Perception and Spatial Vision
 01:17
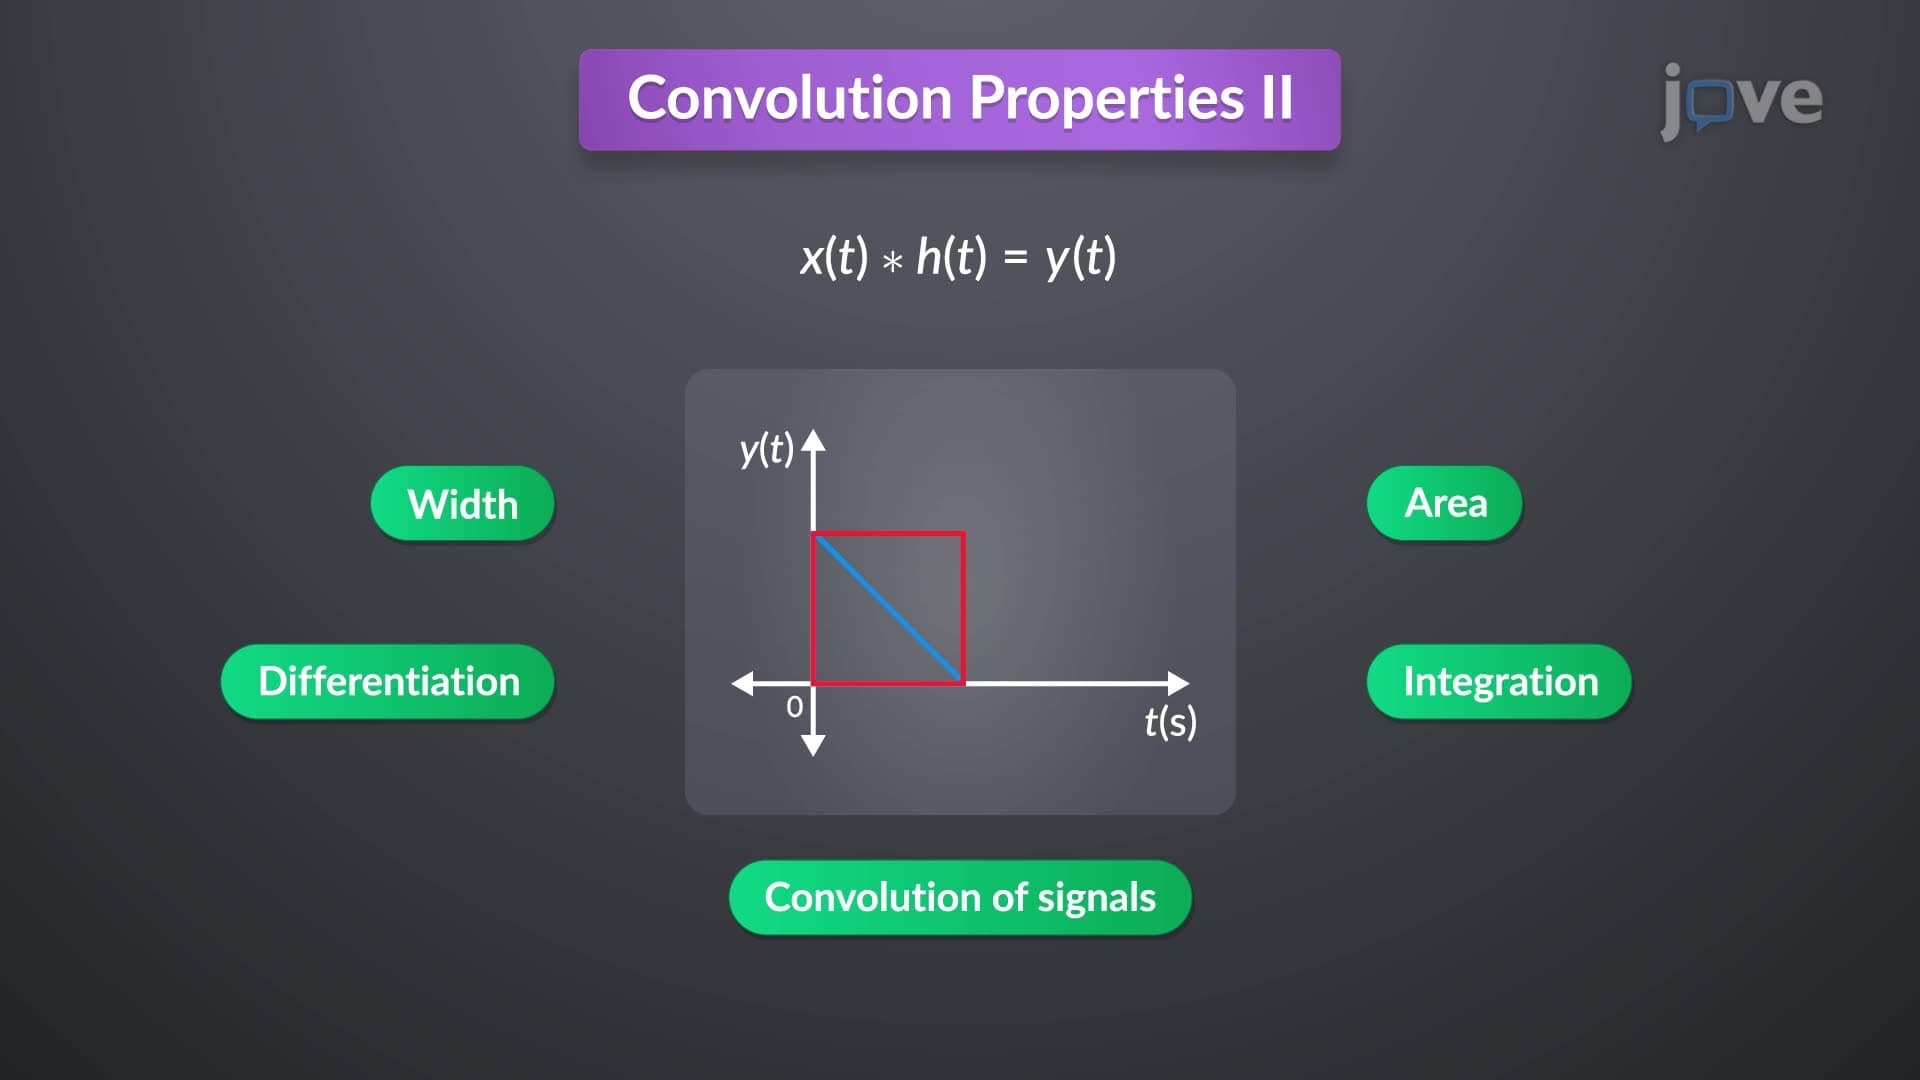
Convolution Properties II
The width property indicates that if the durations of input signals are T1 and T2, then the width of the output response equals the sum of both durations, irrespective of the shapes of the two functions. For instance, convolving two rectangular pulses with durations of 2 seconds and 1 second results in a function with a width of 3 seconds.
The area property asserts that the area under the...
 01:10
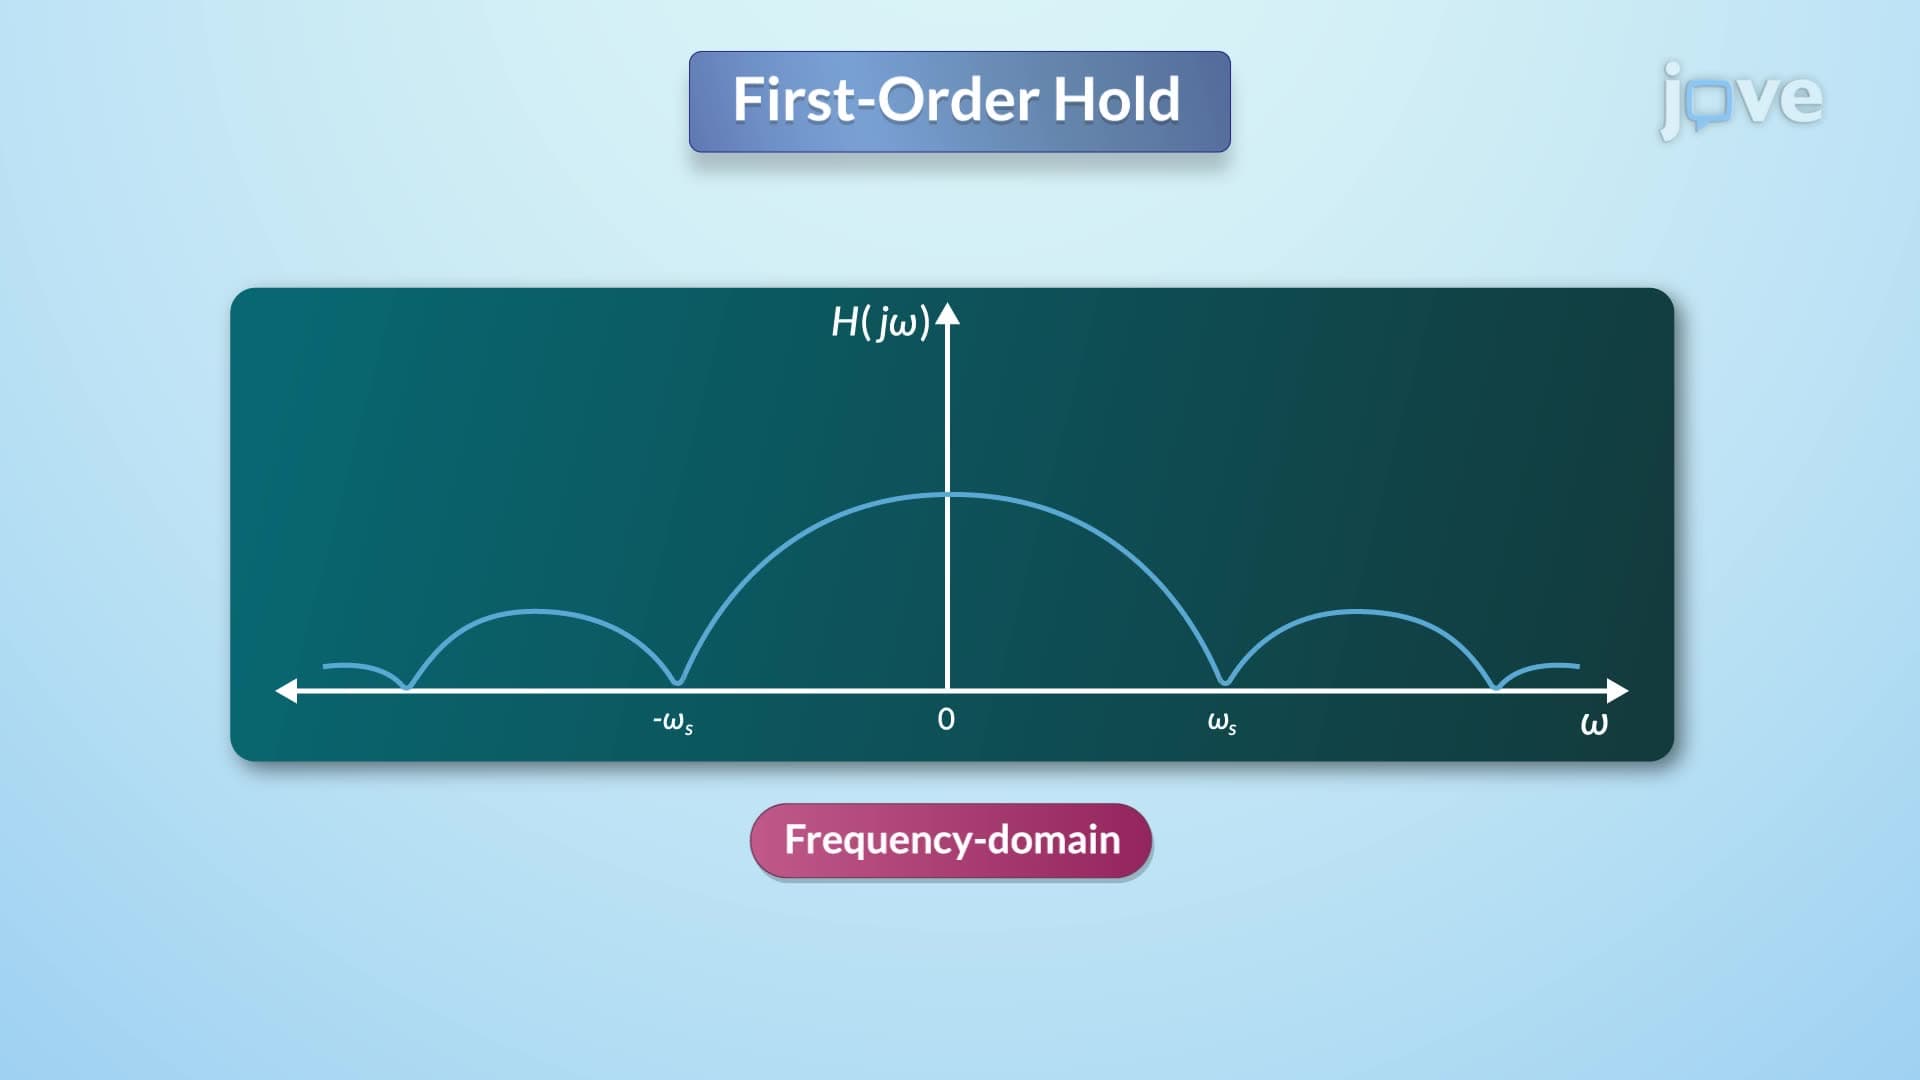
Reconstruction of Signal using Interpolation
 01:15
Distance Corrections