Related Experiment Video
Updated: Jun 9, 2025

Author Spotlight: Impact of Intergenic Interactions on Disease-Identifying Dark Biomarkers
Published on: March 1, 2024
Research on Credit Default Prediction Model Based on TabNet-Stacking
Shijie Wang1,2, Xueyong Zhang1
1School of Finance, Central University of Finance and Economics, Beijing 102206, China.

Abstract:
With the development of financial technology, the traditional experience-based and single-network credit default prediction model can no longer meet the current needs. This manuscript proposes a credit default prediction model based on TabNeT-Stacking. First, use the PyTorch deep learning framework to construct an improved TabNet structure. The multi-population genetic algorithm is used to optimize the Attention Transformer automatic feature selection module. The particle swarm algorithm is used to optimize the hyperparameter selection and achieve automatic parameter search. Finally, Stacking ensemble learning is used, and the improved TabNet is used to extract features. XGBoost (eXtreme Gradient Boosting), LightGBM (Light Gradient Boosting Machine), CatBoost (Category Boosting), KNN (K-NearestNeighbor), and SVM (Support Vector Machine) are selected as the first-layer base learners, and XGBoost is used as the second-layer meta-learner. The experimental results show that compared with original models, the credit default prediction model proposed in this manuscript outperforms the comparison models in terms of accuracy, precision, recall, F1 score, and AUC (Area Under the Curve) of credit default prediction results.
Related Concept Videos
 01:03
Prediction Intervals
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
 01:19
Survival Tree
Building a Survival Tree
Constructing a...
 01:07
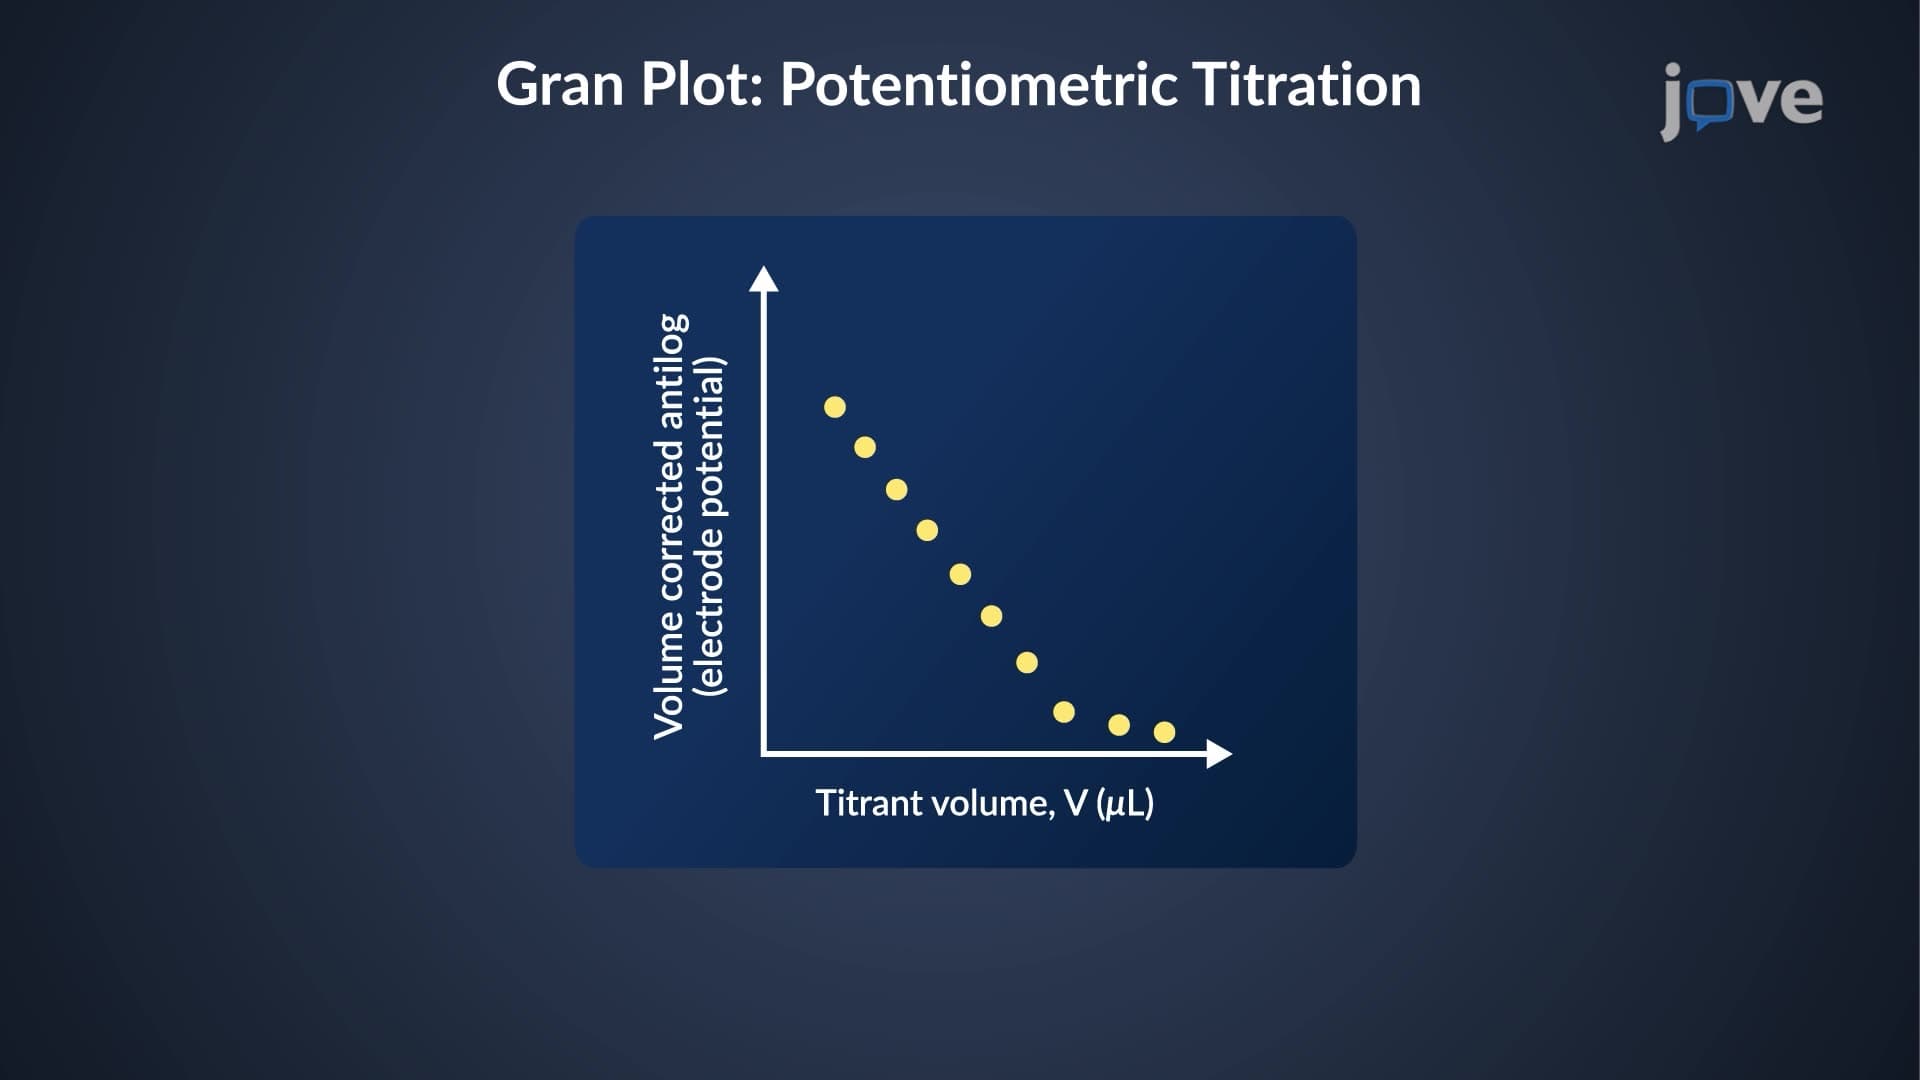
End Point Prediction: Gran Plot
For potentiometric titration, the Gran plot is created by plotting...
 01:29
Aggregates Classification
Petrographic classification groups aggregates based on common mineralogical characteristics. Some of the common mineral groups found in aggregates are...
 01:25
Multiple Regression
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
 01:11
Regression Analysis
In regression analysis, a regression equation is determined based on the line of best fit– a line that best fits the data points plotted in a graph. This line is also called the regression line. The algebraic equation for the regression line is called the regression equation. It is represented as: