Related Experiment Video
Updated: Jun 7, 2025


Author Spotlight: Investigating the Impact of Emotional Prosodies on Voice Recognition and Perception
Published on: August 9, 2024
Spectral network based on lattice convolution and adversarial training for noise-robust speech super-resolution
Junkang Yang1, Hongqing Liu1,2, Lu Gan3
1School of Communications and Information Engineering, Chongqing University of Posts and Telecommunications, Chongqing 400065, China.

Abstract:
Speech super-resolution aims to predict a high-resolution speech signal from its low-resolution counterpart. The previous models usually perform this task at a fixed sampling rate, reconstructing only high-frequency spectrogram components and merging them with low-frequency ones in noise-free cases. These methods achieve high accuracy, but they are less effective in real-world settings, where ambient noise and flexible sampling rates are presented. To develop a robust model that fits practical applications, in this work, we introduce Super Denoise Net (SDNet), a neural network for noise-robust super-resolution with flexible input sampling rates. To this end, SDNet's design includes gated and lattice convolution blocks for enhanced repair and temporal-spectral information capture. The frequency transform blocks are employed to model long frequency dependencies, and a multi-scale discriminator is proposed to facilitate the multi-adversarial loss training. The experiments show that SDNet outperforms current state-of-the-art noise-robust speech super-resolution models on multiple test sets, indicating its robustness and effectiveness in real-world scenarios.


Related Concept Videos
 01:26
Linear Approximation in Frequency Domain
In contrast, nonlinear systems do not inherently possess these properties. However, for small deviations around an operating point, a nonlinear system can often be approximated as linear....
 01:20
Deconvolution
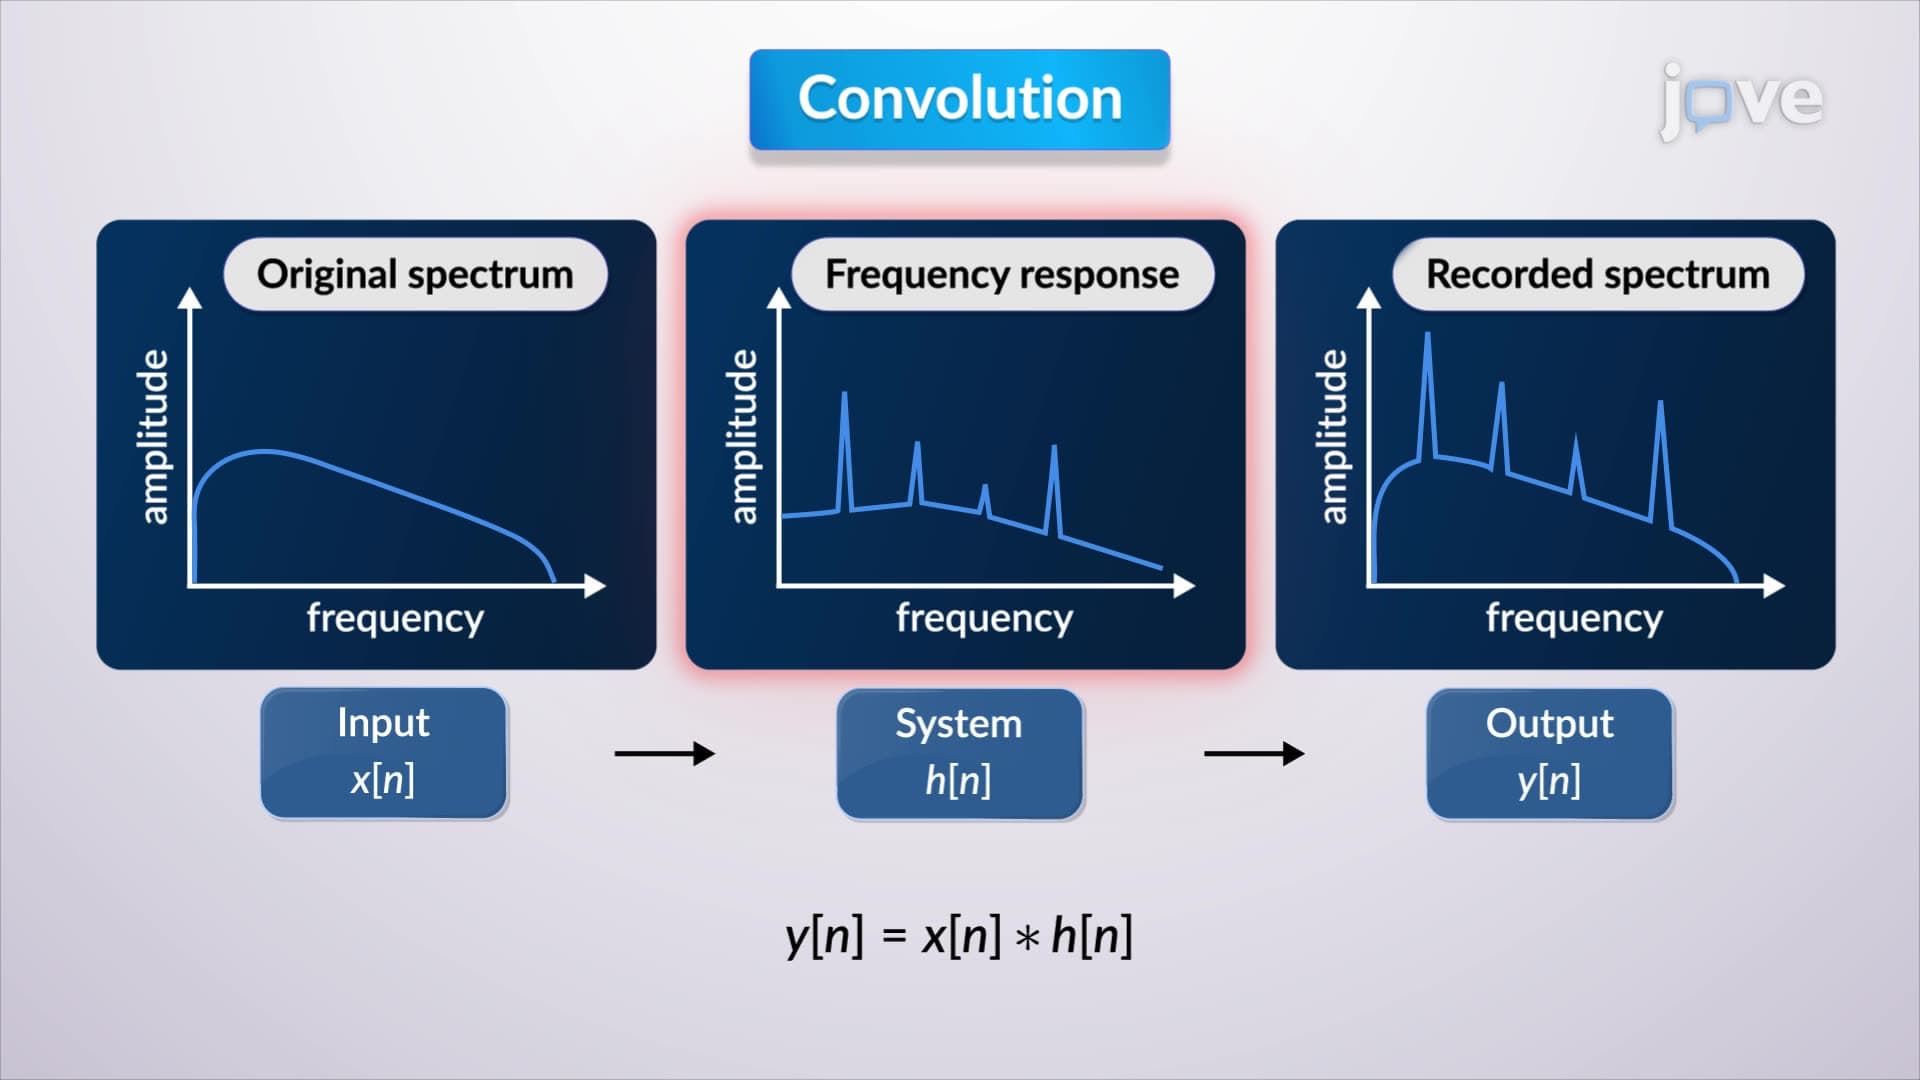
Deconvolution involves several mathematical techniques to derive the impulse response. One common approach is polynomial division. In this method, the input and output sequences are treated as coefficients of...
 01:18
Reducing Line Loss
With a step-up transformer at the source, the voltage is increased, thereby reducing the current in the transmission lines since power loss...
 01:21
Perceiving Loudness, Pitch, and Location
Place theory, or place coding, suggests that different pitches are heard because various sound waves activate specific locations along the cochlea's basilar membrane. The brain determines the pitch of a sound by...
 01:11
Residuals and Least-Squares Property
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
 01:20
Downsampling
The Fourier transform of the decimated sequence reveals a combination of scaled and shifted versions of the original spectrum. This...