Related Experiment Video
Updated: May 7, 2025
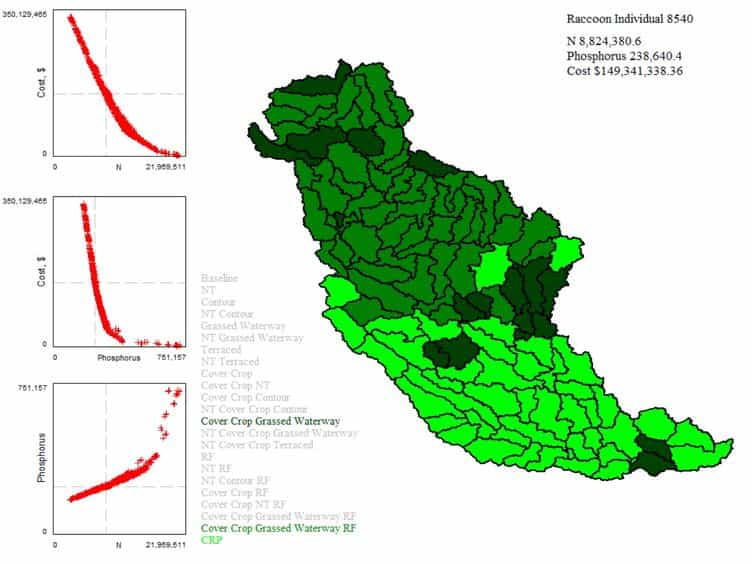
Spatial Multiobjective Optimization of Agricultural Conservation Practices using a SWAT Model and an Evolutionary Algorithm
Published on: December 9, 2012
MACRPO: Multi-agent cooperative recurrent policy optimization
1Intelligent Robotics Group, Electrical Engineering and Automation Department, Aalto University, Helsinki, Finland.

Abstract:
This work considers the problem of learning cooperative policies in multi-agent settings with partially observable and non-stationary environments without a communication channel. We focus on improving information sharing between agents and propose a new multi-agent actor-critic method called Multi-Agent Cooperative Recurrent Proximal Policy Optimization (MACRPO). We propose two novel ways of integrating information across agents and time in MACRPO: First, we use a recurrent layer in the critic's network architecture and propose a new framework to use the proposed meta-trajectory to train the recurrent layer. This allows the network to learn the cooperation and dynamics of interactions between agents, and also handle partial observability. Second, we propose a new advantage function that incorporates other agents' rewards and value functions by controlling the level of cooperation between agents using a parameter. The use of this control parameter is suitable for environments in which the agents are unable to fully cooperate with each other. We evaluate our algorithm on three challenging multi-agent environments with continuous and discrete action spaces, Deepdrive-Zero, Multi-Walker, and Particle environment. We compare the results with several ablations and state-of-the-art multi-agent algorithms such as MAGIC, IC3Net, CommNet, GA-Comm, QMIX, MADDPG, and RMAPPO, and also single-agent methods with shared parameters between agents such as IMPALA and APEX. The results show superior performance against other algorithms. The code is available online at https://github.com/kargarisaac/macrpo.

Related Concept Videos
 01:22
Multi-input and Multi-variable systems
In the absence...
 01:29
Mechanistic Models: Compartment Models in Algorithms for Numerical Problem Solving
In individual population analyses, different algorithms are employed, such as Cauchy's method, which uses a...
 01:12
Observational Learning
 01:19
Masking and Demasking Agents
There are many masking agents, such as cyanide, fluoride, triethanolamine, thiourea, and 2,3-bis(sulfanyl)propan-1-ol (formerly 2,3-dimercapto-1-propanol), with the masking agent chosen based on...
 01:06
Collisions in Multiple Dimensions: Problem Solving
A small car of mass 1,200 kg traveling east at 60 km/h collides at an intersection with a truck of mass 3,000 kg traveling due north at 40 km/h. The two vehicles are locked together. What is the...
 01:27
Associative Learning
Classical conditioning, also known...