Video DataFlywheel: Resolving the Impossible Data Trinity in Video-Language Understanding
Related Experiment Video
Updated: May 3, 2026

Eye Tracking During Visually Situated Language Comprehension: Flexibility and Limitations in Uncovering Visual Context Effects
Published on: November 30, 2018

Abstract:
Recently, video-language understanding has achieved great success through large-scale pre-training. However, data scarcity remains a prevailing challenge. This study quantitatively reveals an "impossible trinity" among data quantity, diversity, and quality in pre-training datasets. Recent efforts seek to refine large-scale, diverse ASR datasets compromised by low quality through synthetic annotations. These methods successfully refine the original annotations by leveraging useful information in multimodal video content (frames, tags, ASR transcripts, etc.). Nevertheless, they struggle to mitigate noise within synthetic annotations and lack scalability as the dataset size expands. To address these issues, we introduce the Video DataFlywheel framework, which iteratively refines video annotations with improved noise control methods. For iterative refinement, we first leverage a video-language model to generate synthetic annotations, resulting in a refined dataset. Then, we pre-train on it and fine-tune on human refinement examples for a stronger model. These processes are repeated for continuous improvement. For noise control, we present AdaTaiLr, a novel method that requires weaker assumptions on noise distribution. This method proves more effective in large datasets and offers theoretical guarantees. The combination of iterative refinement and AdaTaiLr can achieve better scalability in video-language understanding. Extensive experiments show that our framework outperforms existing data refinement baselines, delivering a 3% performance boost and improving dataset quality with minimal diversity loss. Furthermore, our refined dataset facilitates significant improvements in various video-language understanding tasks, including video question answering and text-video retrieval.
More Related Videos
 09:27
Using Eye Movements Recorded in the Visual World Paradigm to Explore the Online Processing of Spoken Language
Published on: October 13, 2018
 08:25
Combining Eye-tracking Data with an Analysis of Video Content from Free-viewing a Video of a Walk in an Urban Park Environment
Published on: May 7, 2019
Related Concept Videos
 00:59
How Data are Classified: Numerical Data
Quantitative data may be either discrete or continuous. All quantitative data that take on only specific numerical...
 01:06
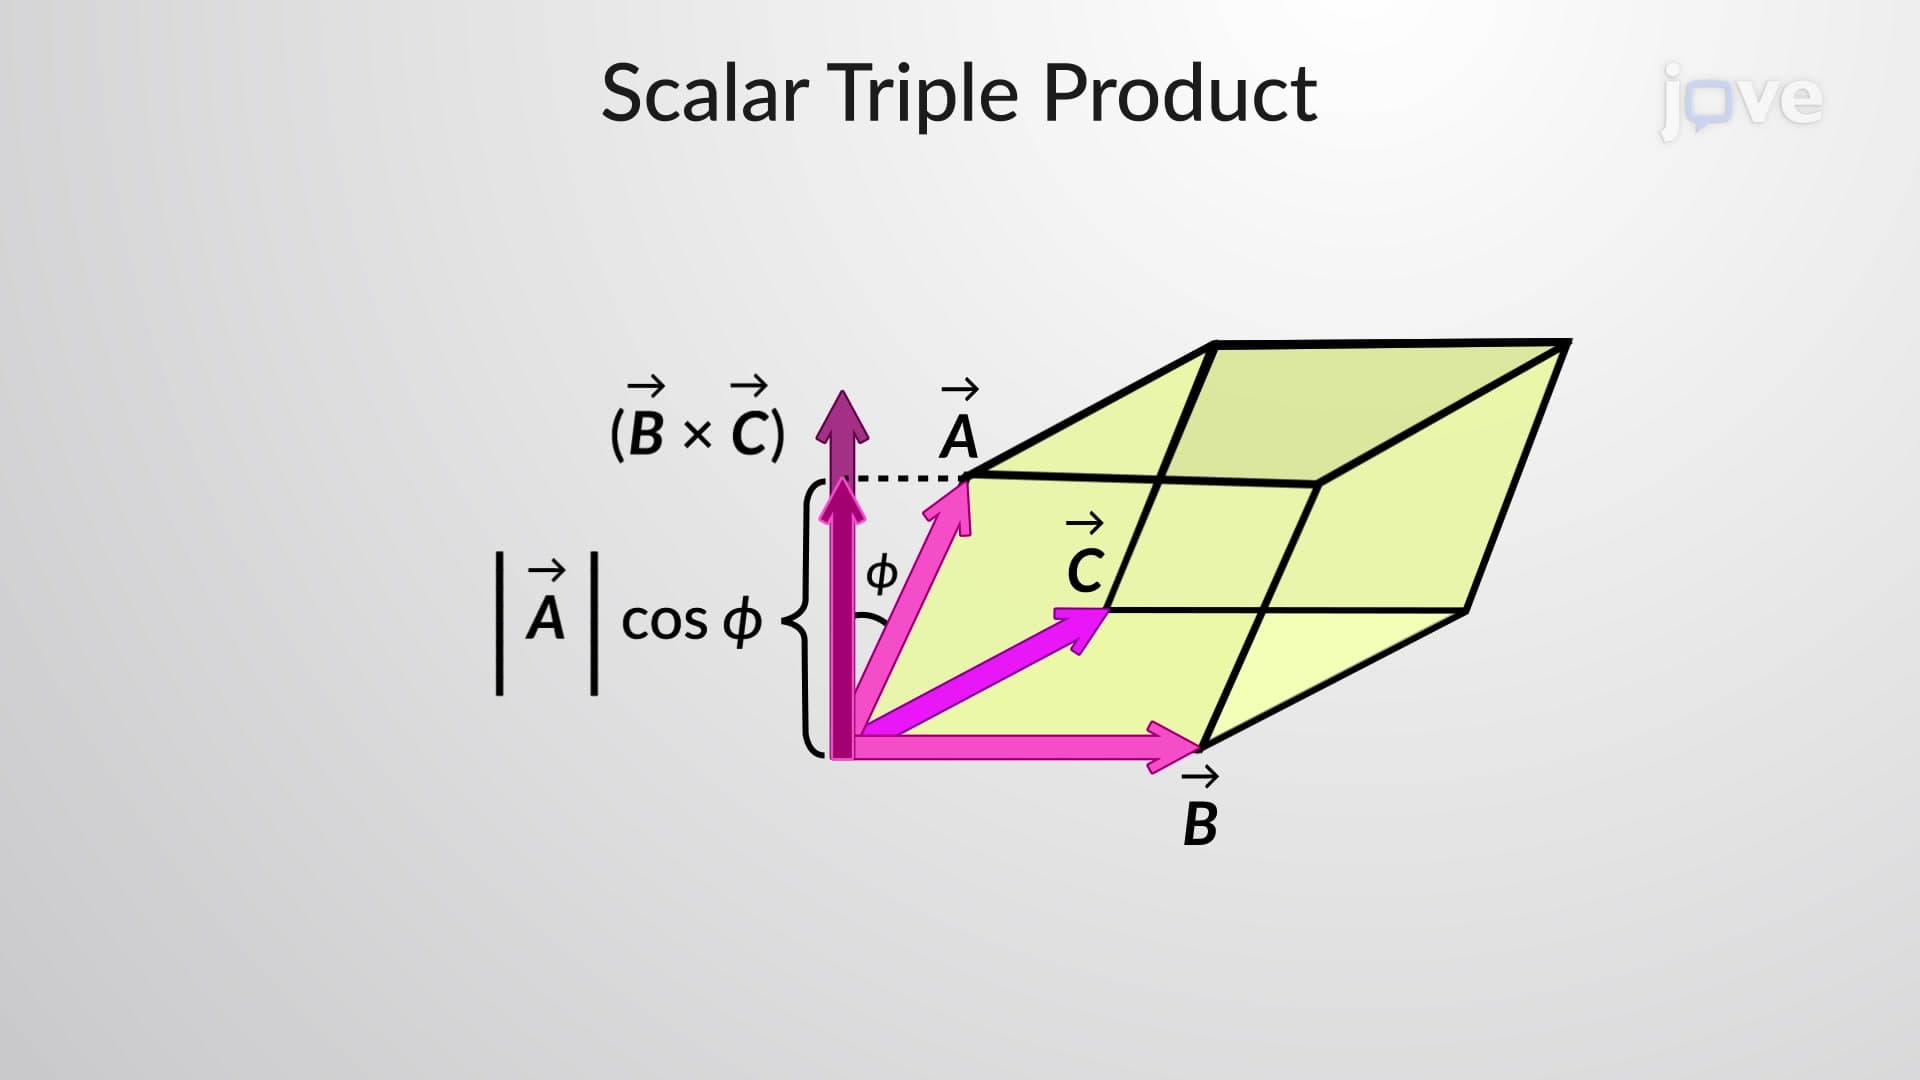
Scalar and Vector Triple Products
The scalar triple product is the dot product of a vector with the cross product of two vectors....
 01:29
Relative Motion Analysis using Rotating Axes-Problem Solving
Here, in order to determine the magnitude of velocity and acceleration for point...
 01:17
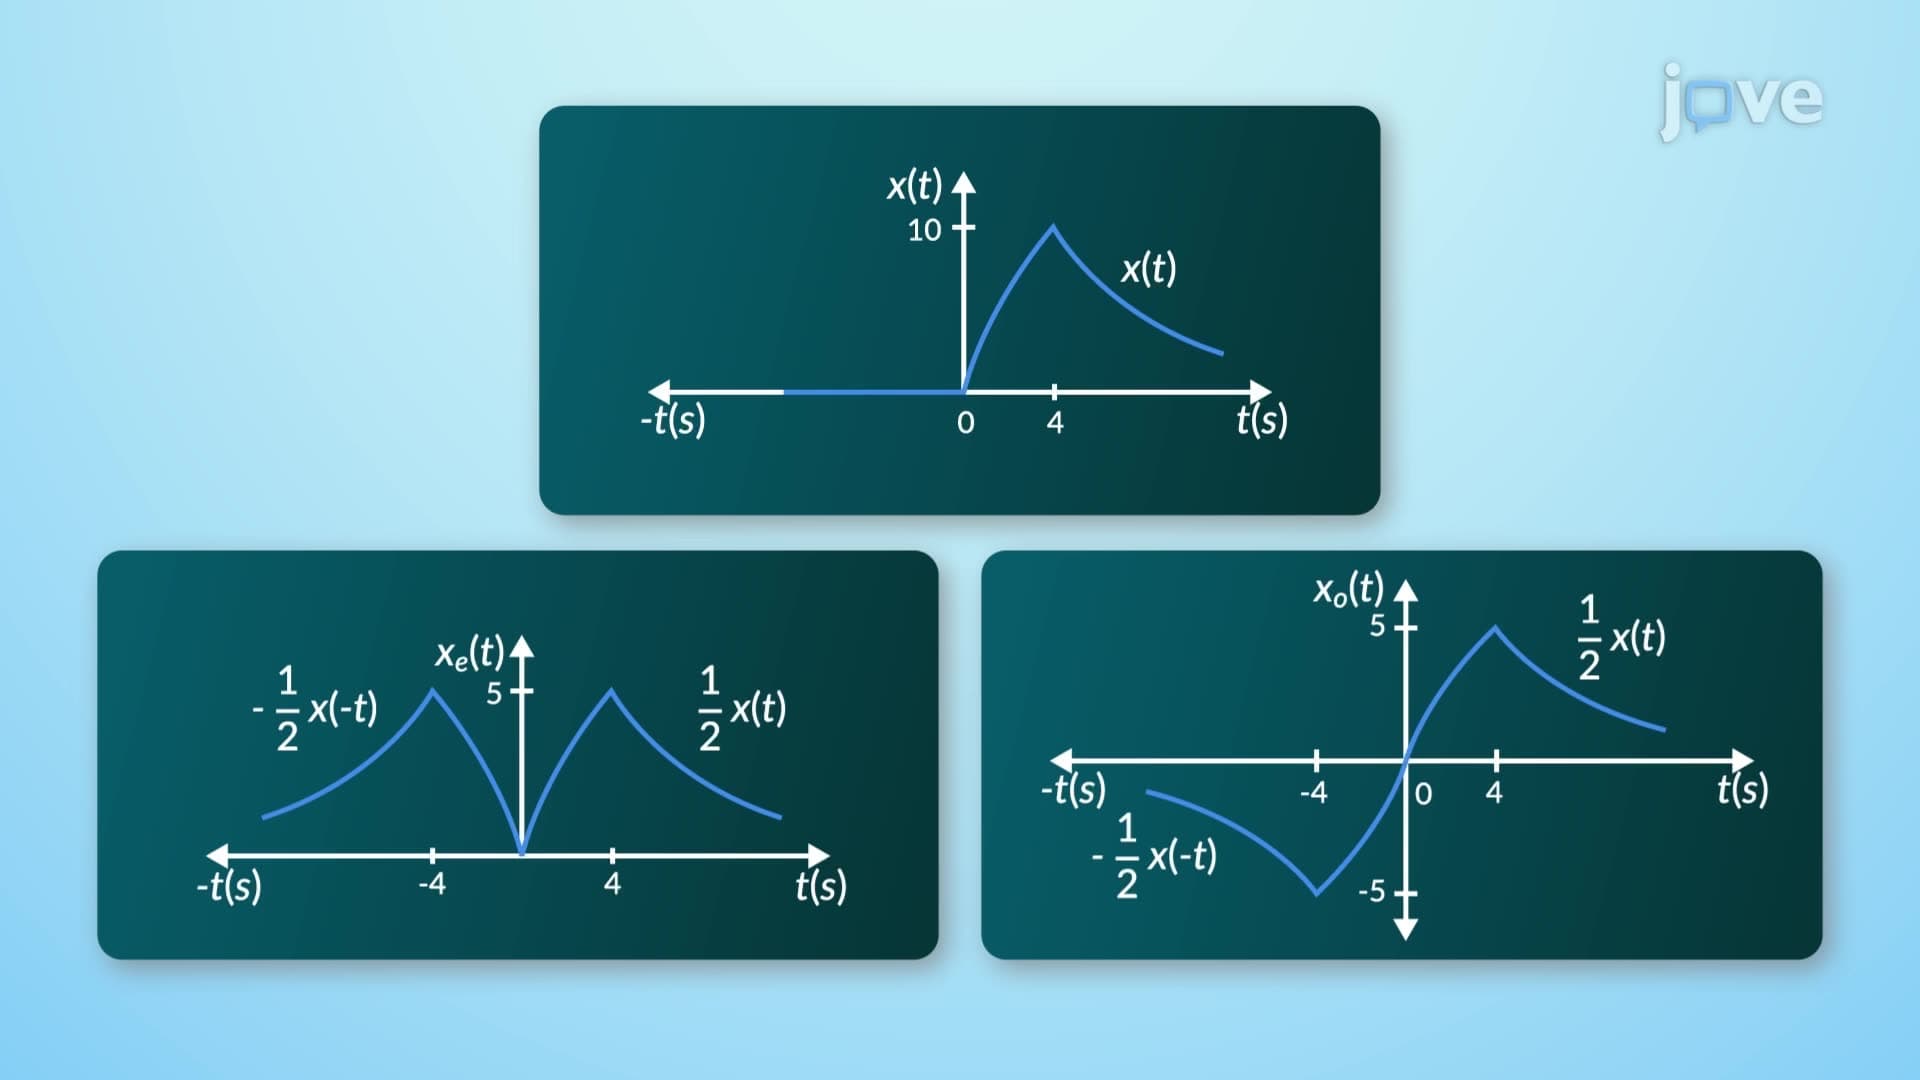
Even and Odd Signals
 01:16
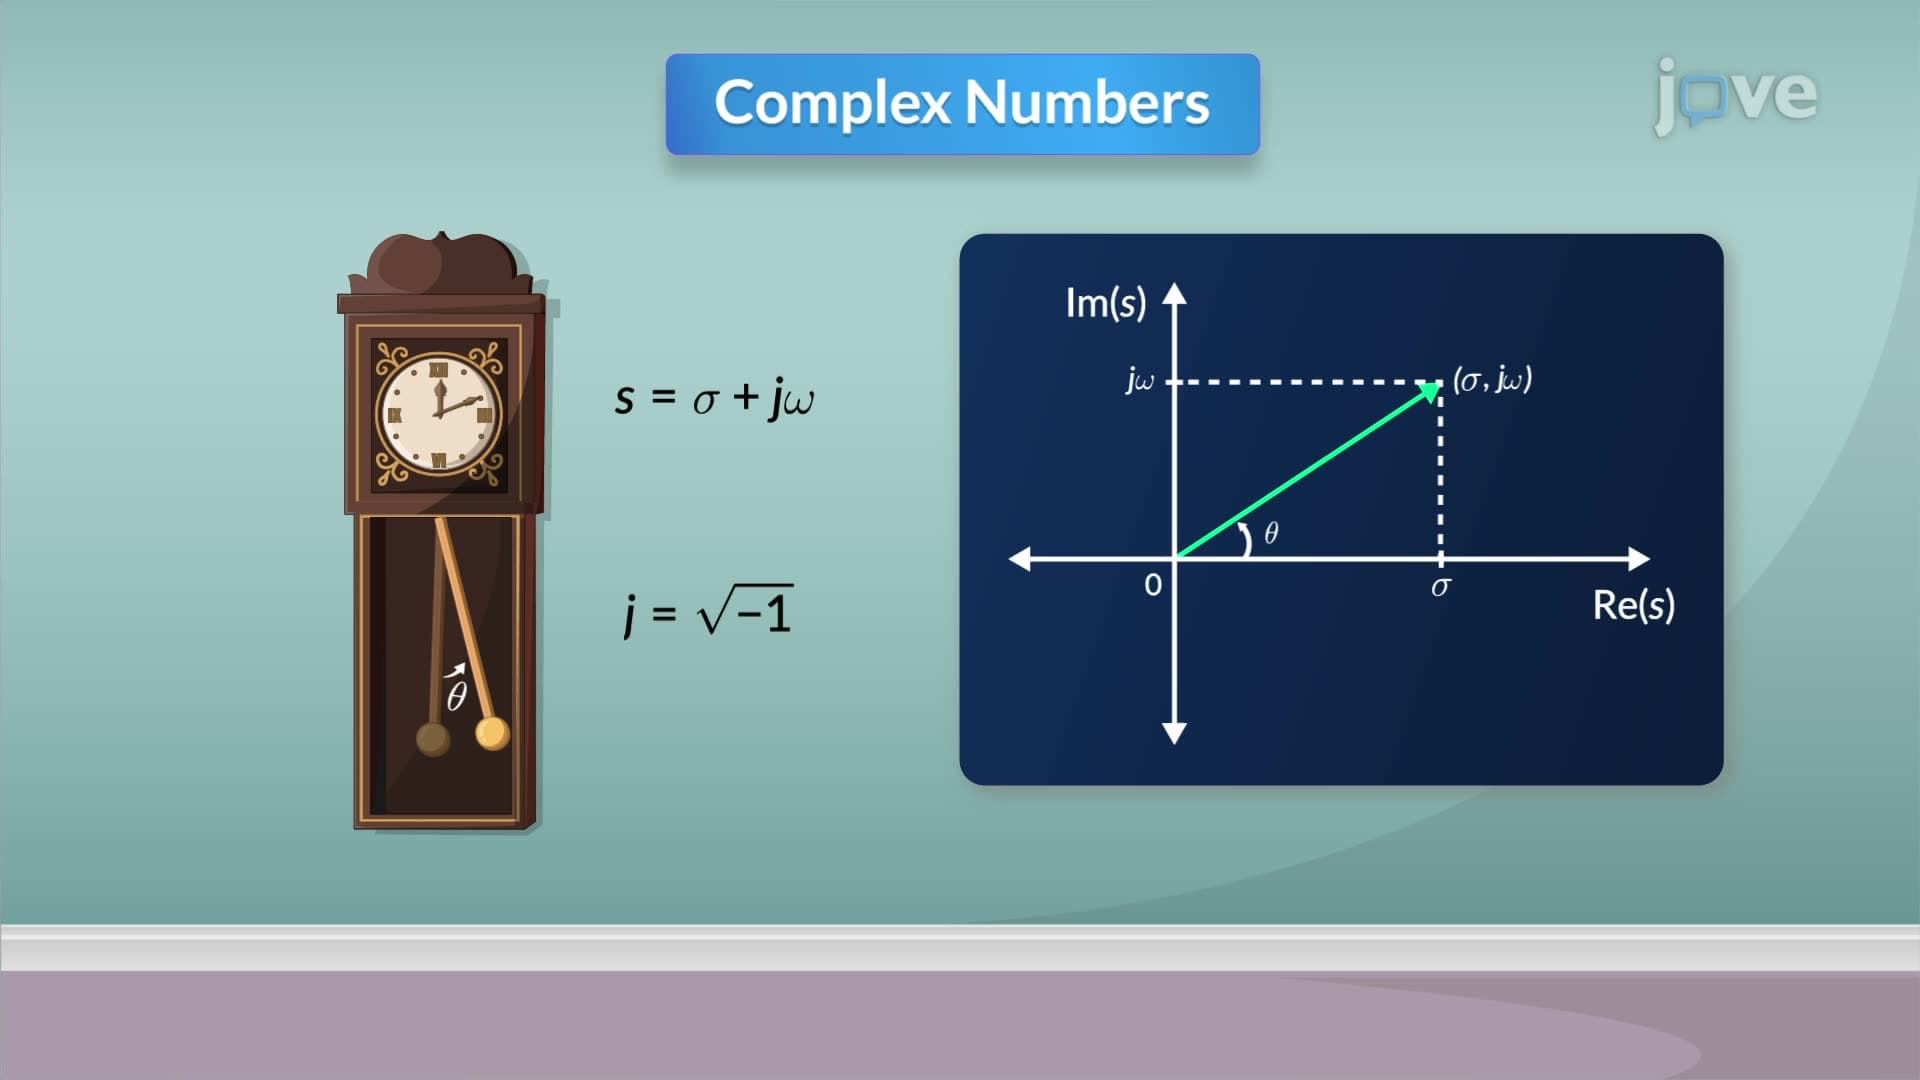
Vector Representation of Complex Numbers
Consider a function defined as the product of the complex factors in the numerator divided by the product of the complex factors in the...
 01:30
Gaussian Elimination: Problem Solving