Related Experiment Video
Updated: May 24, 2025


Author Spotlight: Enhancement of Salient Object Detection for Smart Grid Applications
Published on: December 15, 2023
A dual-stream feature decomposition network with weight transformation for multi-modality image fusion
Tianqing Hu1, Xiaofei Nan1, Xiabing Zhou2
1School of Computer Science and Artificial Intelligence, Zhengzhou University, Zhengzhou, 450001, China.

Abstract:
As an image enhancement technology, multi-modal image fusion primarily aims to retain salient information from multi-source image pairs in a single image, generating imaging information that contains complementary features and can facilitate downstream visual tasks. However, dual-stream methods with convolutional neural networks (CNNs) as backbone networks predominantly have limited receptive fields, whereas methods with Transformers are time-consuming, and both lack the exploration of cross-domain information. This study proposes an innovative image fusion model designed for multi-modal images, encompassing pairs of infrared and visible images and multi-source medical images. Our model leverages the strengths of both Transformers and CNNs to model various feature types effectively, addressing both short- and long-range learning as well as the extraction of low- and high-frequency features. First, our shared encoder is constructed based on Transformers for long-range learning, including an intra-modal feature extraction block, an inter-modal feature extraction block, and a novel feature alignment block that handles slight misalignments. Our private encoder for extracting low- and high-frequency features employs a dual-stream architecture based on CNNs, which includes a dual-domain selection mechanism and an invertible neural network. Second, we develop a cross-attention-based Swin Transformer block to explore cross-domain information. In particular, we introduce a weight transformation that is embedded into the Transformer block to enhance the efficiency. Third, a unified loss function incorporating a dynamic weighting factor is formulated to capture the inherent commonalities of multi-modal images. A comprehensive qualitative and quantitative analysis of image fusion and object detection experimental results demonstrates that the proposed method effectively preserves thermal targets and background texture details, surpassing state-of-the-art alternatives in terms of achieving high-quality image fusion and improving the performance in subsequent visual tasks.
Related Concept Videos
 01:20
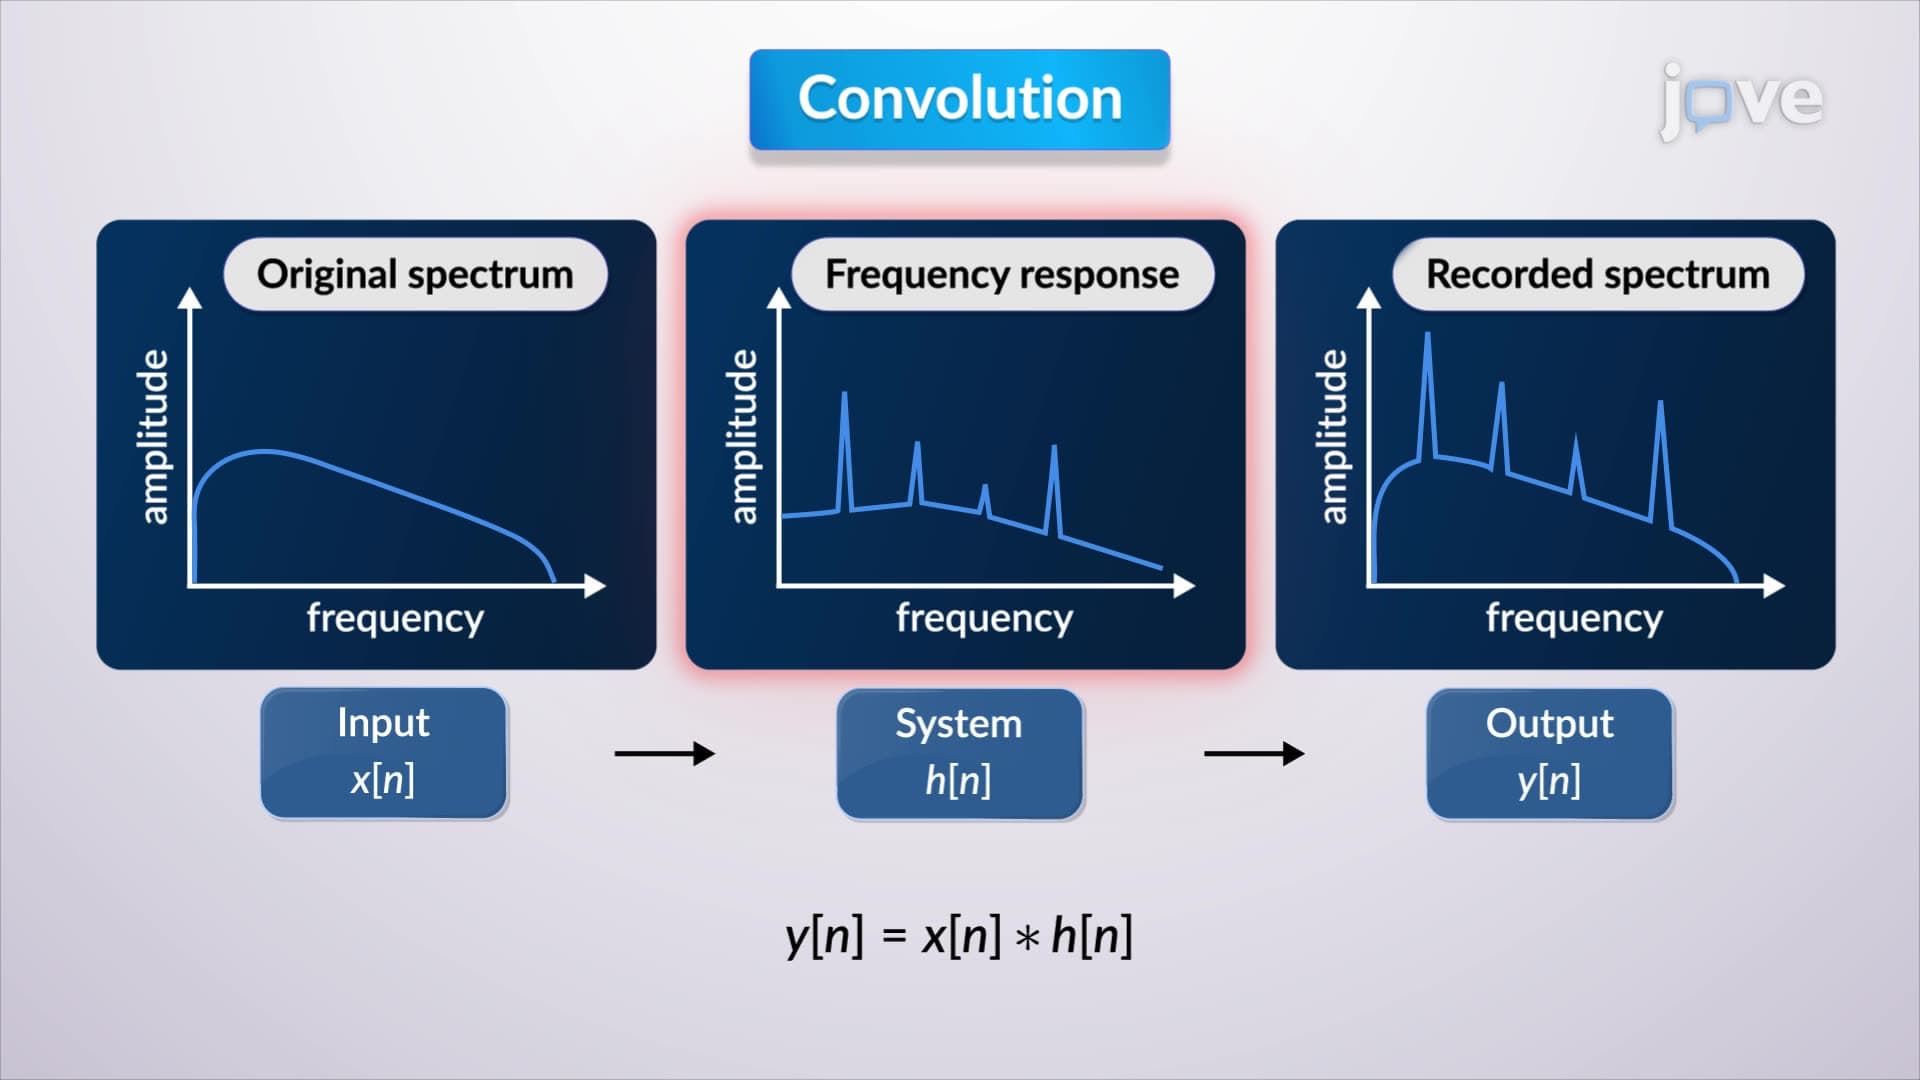
Deconvolution
Deconvolution involves several mathematical techniques to derive the impulse response. One common approach is polynomial division. In this method, the input and output sequences are treated as coefficients of...
 01:22
Multi-input and Multi-variable systems
In the absence...
 00:57
Weighted Mean
For example, consider the number of goals scored in the matches of a tournament. While computing the average number of goals scored in the tournament, it may be more important to...
 01:17
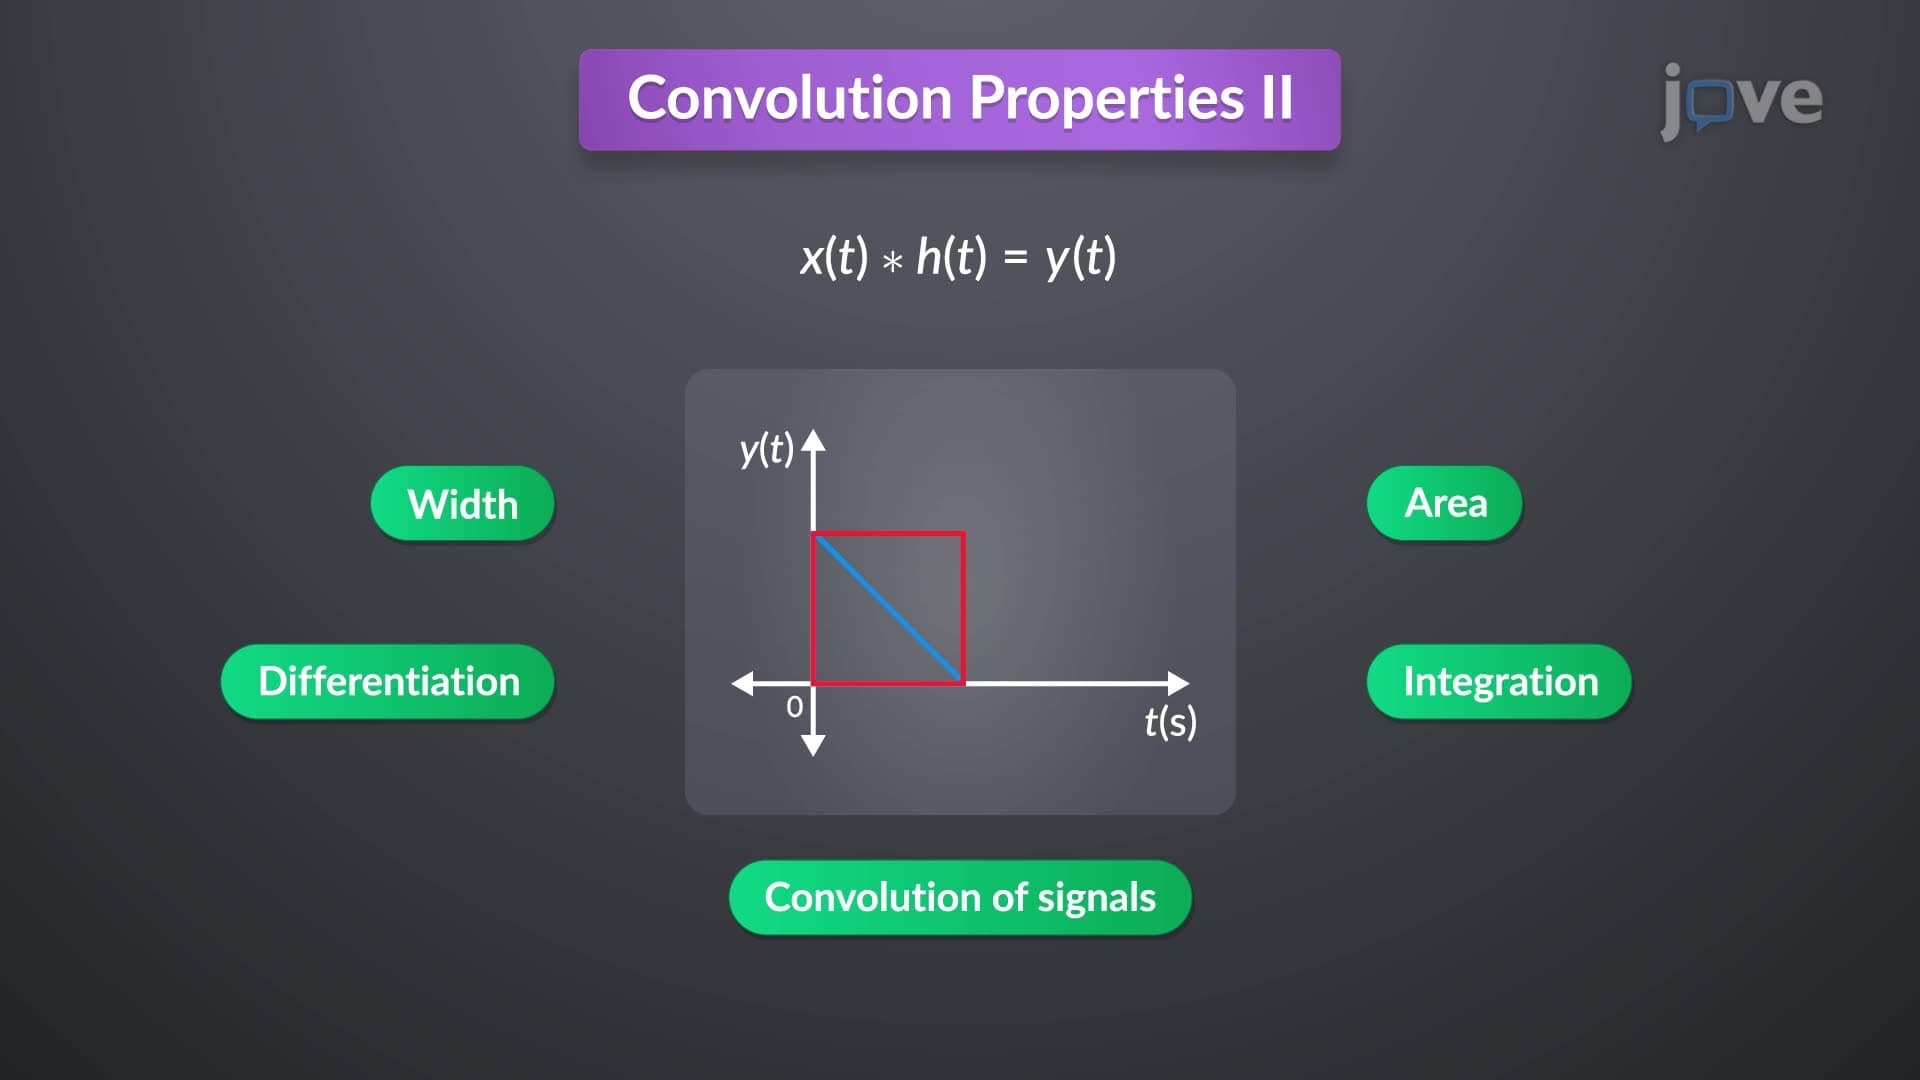
Convolution Properties II
The width property indicates that if the durations of input signals are T1 and T2, then the width of the output response equals the sum of both durations, irrespective of the shapes of the two functions. For instance, convolving two rectangular pulses with durations of 2 seconds and 1 second results in a function with a width of 3 seconds.
The area property asserts that the area under the...
 01:20
Convolution Properties I
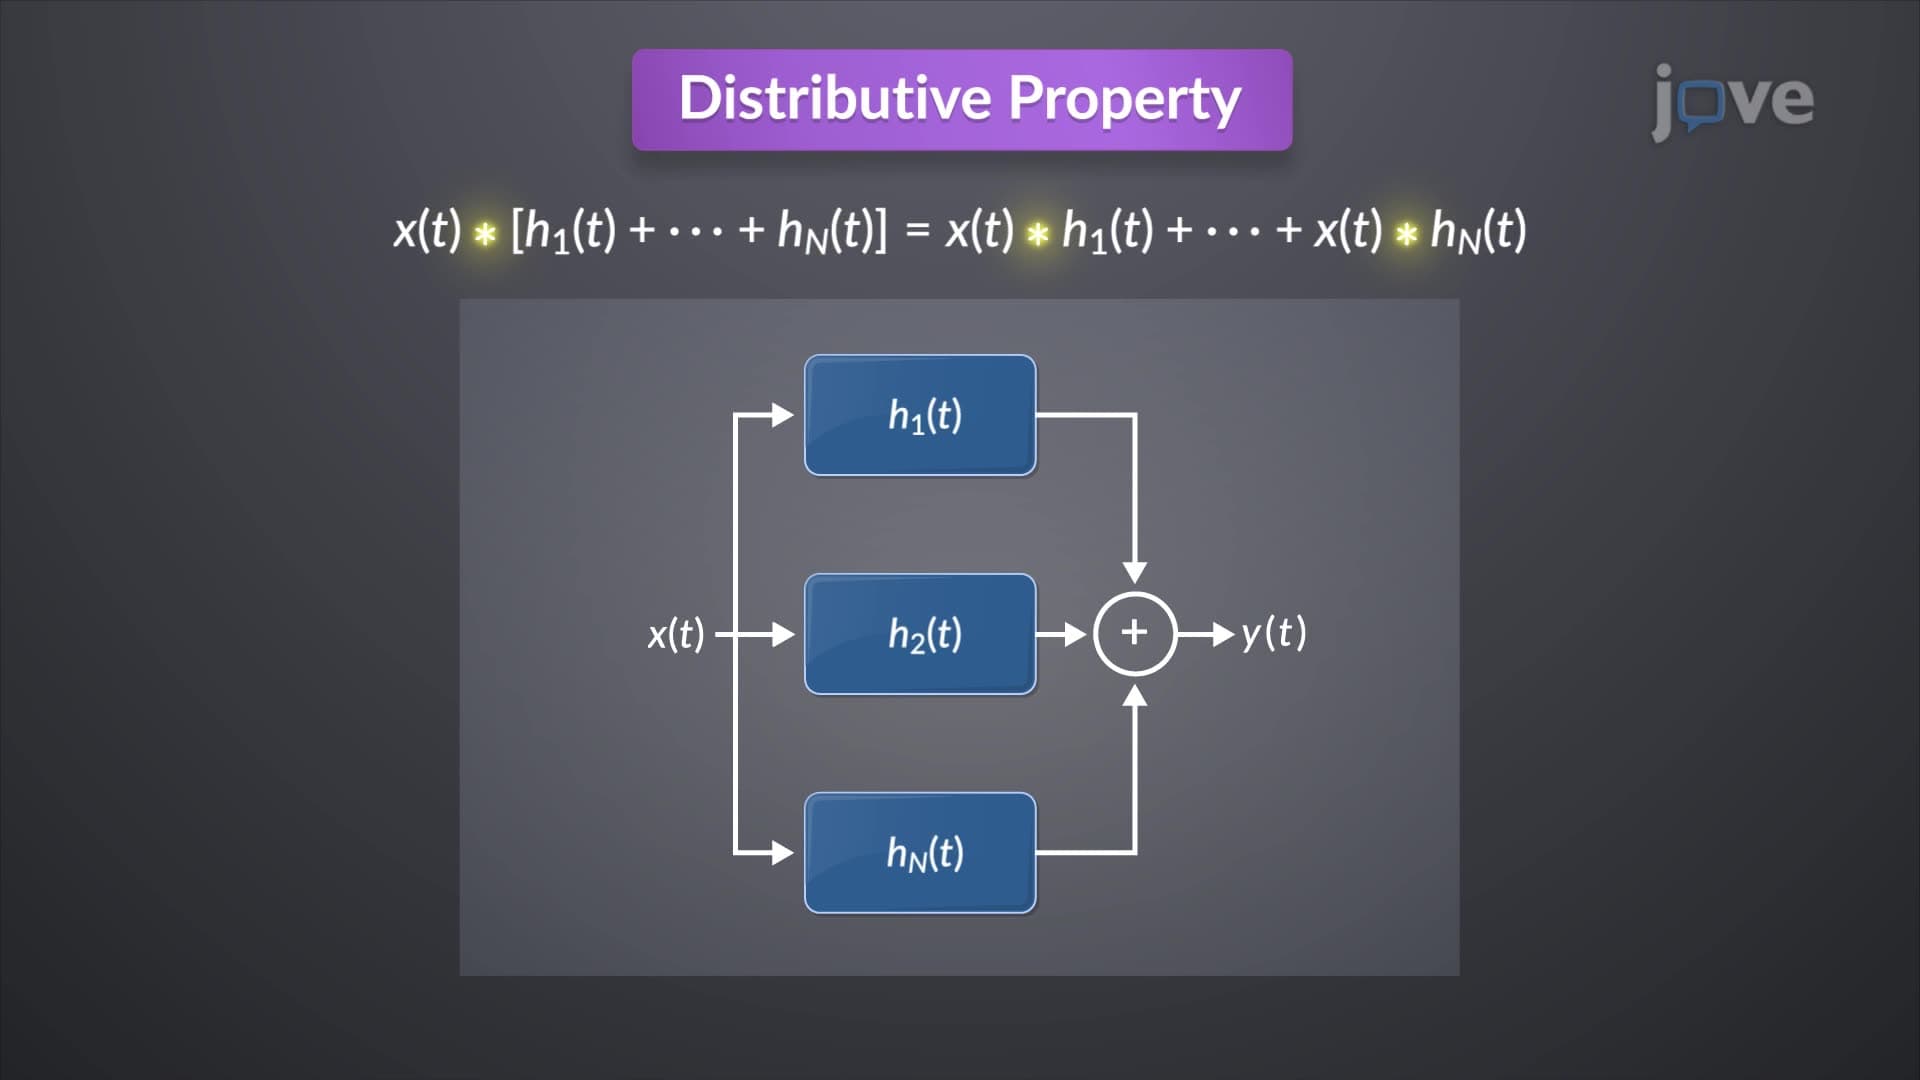
The commutative property reveals that the input and the impulse response of an LTI (Linear Time-Invariant) system can be interchanged without affecting the output:
 01:18
Reducing Line Loss
With a step-up transformer at the source, the voltage is increased, thereby reducing the current in the transmission lines since power loss...