Related Experiment Video
Updated: May 11, 2026

Deep Neural Networks for Image-Based Dietary Assessment
Published on: March 13, 2021
Improving fine-grained food classification using deep residual learning and selective state space models
Chi-Sheng Chen1, Guan-Ying Chen2, Dong Zhou3
1Neuro Industry, Inc., San Francisco, California, United States of America.

Background:
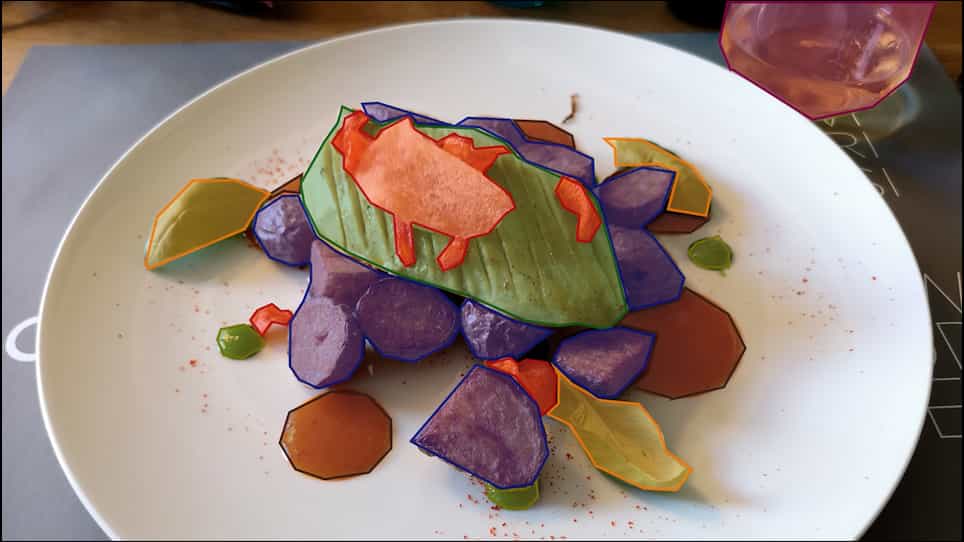
Food classification is the foundation for developing food vision tasks and plays a key role in the burgeoning field of computational nutrition. Due to the complexity of food requiring fine-grained classification, the Convolutional Neural Networks (CNNs) backbone needs additional structural design, whereas Vision Transformers (ViTs), containing the self-attention module, has increased computational complexity.
Methods:
We propose a ResVMamba model and validate its performance on processing complex food dataset. Unlike previous fine-grained classification models that heavily rely on attention mechanisms or hierarchical feature extraction, our method leverages a novel residual learning strategy within a state-space framework to improve representation learning. This approach enables the model to efficiently capture both global and local dependencies, surpassing the computational efficiency of Vision Transformers (ViTs) while maintaining high accuracy. We introduce an academically underestimated food dataset CNFOOD-241, and compare the CNFOOD-241 with other food databases.
Results:
The proposed ResVMamba surpasses current state-of-the-art (SOTA) models, achieving a Top-1 classification accuracy of 81.70% and a Top-5 accuracy of 96.83%. Our findings elucidate that our proposed methodology establishes a new benchmark for SOTA performance in food recognition on the CNFOOD-241 dataset.
Conclusions:
We pioneer the integration of a residual learning framework within the VMamba model to concurrently harness both global and local state features. The code can be obtained on GitHub: https://github.com/ChiShengChen/ResVMamba.