Related Experiment Video
Updated: Jun 13, 2025
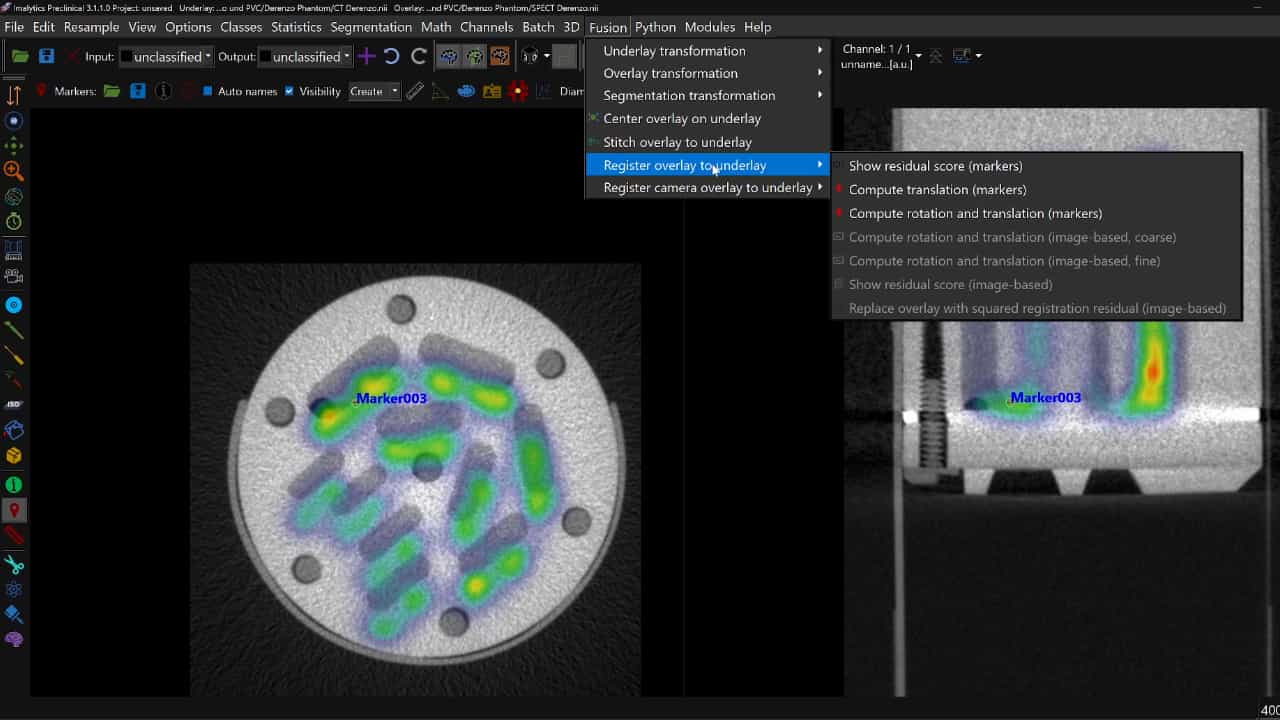

Author Spotlight: An Efficient and Robust Software for Automated Fusion of Multiple Preclinical Imaging Modalities
Published on: October 27, 2023
Evaluating an information theoretic approach for selecting multimodal data fusion methods
Tengyue Zhang1, Ruiwen Ding1, Kha-Dinh Luong2
1Department of Bioengineering, Medical & Imaging Informatics, Department of Radiological Sciences, David Geffen School of Medicine at University of California, Los Angeles (UCLA), Los Angeles, 90024, CA, USA.

Objective:
Interest has grown in combining radiology, pathology, genomic, and clinical data to improve the accuracy of diagnostic and prognostic predictions toward precision health. However, most existing works choose their datasets and modeling approaches empirically and in an ad hoc manner. A prior study proposed four partial information decomposition (PID)-based metrics to provide a theoretical understanding of multimodal data interactions: redundancy, uniqueness of each modality, and synergy. However, these metrics have only been evaluated in a limited collection of biomedical data, and the existing work does not elucidate the effect of parameter selection when calculating the PID metrics. In this work, we evaluate PID metrics on a wider range of biomedical data, including clinical, radiology, pathology, and genomic data, and propose potential improvements to the PID metrics.
Methods:
We apply the PID metrics to seven different modality pairs across four distinct cohorts (datasets). We compare and interpret trends in the resulting PID metrics and downstream model performance in these multimodal cohorts. The downstream tasks being evaluated include predicting the prognosis (either overall survival or recurrence) of patients with non-small cell lung cancer, prostate cancer, and glioblastoma.
Results:
We found that, while PID metrics are informative, solely relying on these metrics to decide on a fusion approach does not always yield a machine learning model with optimal performance. Of the seven different modality pairs, three had poor (0%), three had moderate (66%-89%), and only one had perfect (100%) consistency between the PID values and model performance. We propose two improvements to the PID metrics (determining the optimal parameters and uncertainty estimation) and identified areas where PID metrics could be further improved.
Conclusion:
The current PID metrics are not accurate enough for estimating the multimodal data interactions and need to be improved before they can serve as a reliable tool. We propose improvements and provide suggestions for future work. Code: https://github.com/zhtyolivia/pid-multimodal.

Related Concept Videos
 01:07
What is a Mode?
There can be more than one mode in a data set if multiple values have the same highest frequency. For instance, suppose that the Statistics exam scores of 20 students are: 50; 53; 59; 59; 63; 63; 72; 72; 72; 72; 72; 76; 78; 81; 83; 84; 84; 84; 90; 93. Here, the mode is 72, as it occurs most frequently, five times.
A data set with two modes is called bimodal. For example,...
 01:22
Multi-input and Multi-variable systems
In the absence...
 01:06
Collisions in Multiple Dimensions: Problem Solving
A small car of mass 1,200 kg traveling east at 60 km/h collides at an intersection with a truck of mass 3,000 kg traveling due north at 40 km/h. The two vehicles are locked together. What is the...
 01:05
Collisions in Multiple Dimensions: Introduction
 01:06
Model Approaches for Pharmacokinetic Data: Distributed Parameter Models
The distributed parameter models are specifically designed to account for variations and differences in some drug classes. This model is particularly useful for assessing regional concentrations of anticancer or...
 01:16
Statistical Inference Techniques in Hypothesis Testing: Parametric Versus Nonparametric Data
Parametric statistics, as the name suggests, assumes that data follow a specific distribution, often a normal distribution. This assumption enables robust hypothesis testing and estimation. Parametric methods, like the Student's t-test or Goodness-of-fit test, are frequently employed in biostatistics due to their robustness. For instance,...