Related Experiment Video
Updated: Aug 9, 2026
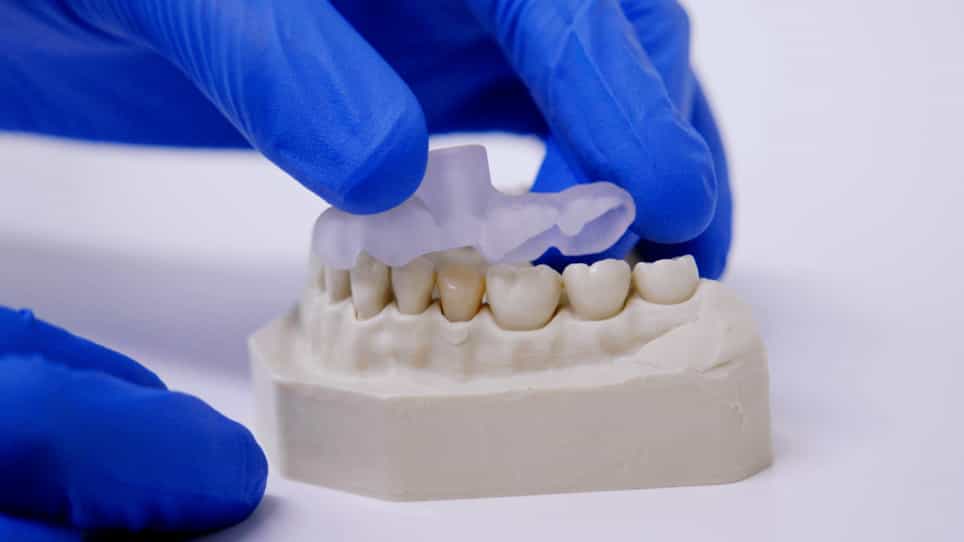
Guided Endodontics: Three-Dimensional Planning and Template-Aided Preparation of Endodontic Access Cavities
Published on: May 24, 2022
Comparing the performance of ChatGPT 4o, DeepSeek R1, and Gemini 2 Pro in answering fixed prosthodontics questions
1Assistant Professor, Department of Restorative Dentistry, Maurice H. Kornberg School of Dentistry, Temple University, Philadelphia, Pa.

Statement Of Problem:
The accuracy of DeepSeek and the latest versions of ChatGPT and Gemini in responding to prosthodontics questions needs to be evaluated. Additionally, the extent to which the performance of these chatbots changes through user interactions remains unexplored.
Purpose:
The purpose of this longitudinal repeated-measures experimental study was to compare the performance of ChatGPT (4o), DeepSeek (R1), and Gemini (2 Pro) in answering multiple-choice (MC) and short-answer (SA) fixed prosthodontics questions over 4 consecutive weeks after exposure to correct responses.
Material And Methods:
A total of 40 questions (20 MC and 20 SA) were developed based on the sixth edition of Contemporary Fixed Prosthodontics. Following a standardized protocol, these questions were posed to ChatGPT, DeepSeek, and Gemini on 4 consecutive Saturdays using 10 independent accounts per chatbot. After each session, correct answers were provided to the chatbots, and, before the next session, their memory and history were cleared. Responses were scored as correct (1) or incorrect (0) for MC questions and correct (2), partially correct (1), or incorrect (0) for SA questions. Weighted accuracy was calculated accordingly. The Kendall W coefficient was used to assess agreement among the 10 accounts per chatbot. The effects of chatbot type, time (week), and their interaction on performance were analyzed using generalized estimating equations (GEEs), followed by pairwise comparisons using the Mann-Whitney U test and Wilcoxon signed-rank test with Bonferroni adjustments for multiple comparisons (α=.05).
Results:
All chatbots showed significant reproducibility, with Gemini exhibiting the highest repeatability for SA questions, followed by ChatGPT for MC questions. Accuracy ranged between 43% and 71%. ChatGPT and DeepSeek demonstrated significantly better performance in MC questions compared with Gemini (P<.017). However, in the third week, Gemini outperformed DeepSeek in SA questions (P=.007). Over time, Gemini showed continuous improvement in SA questions, whereas DeepSeek exhibited a performance surge in the fourth week. ChatGPT's performance remained stable throughout the study period.
Conclusions:
The overall accuracy of the studied chatbots in answering MC and SA prosthodontics questions was not satisfactory. Among them, ChatGPT was the most reliable for MC questions, while ChatGPT and Gemini performed best for SA questions. Gemini (for SA questions) and DeepSeek (for MC and SA questions) demonstrated improvement after exposure to correct responses.