Related Experiment Video
Updated: Jun 14, 2025
Author Spotlight: Impact of Intergenic Interactions on Disease-Identifying Dark Biomarkers
Published on: March 1, 2024
Development of time to event prediction models using federated learning
Rasmus Rask Kragh Jørgensen1,2,3, Jonas Faartoft Jensen4, Tarec El-Galaly4,5,6,7
1Department of Hematology, Clinical Cancer Research Center, Aalborg University Hospital, Aalborg, Denmark. Rasmus.rask@rn.dk.

Background:
In a wide range of diseases, it is necessary to utilize multiple data sources to obtain enough data for model training. However, performing centralized pooling of multiple data sources, while protecting each patients' sensitive data, can require a cumbersome process involving many institutional bodies. Alternatively, federated learning (FL) can be utilized to train models based on data located at multiple sites.
Method:
We propose two methods for training time-to-event prediction models based on distributed data, relying on FL algorithms, for time-to-event prediction models. Both approach incorporates steps to allow prediction of individual-level survival curves, without exposing individual-level event times. For Cox proportional hazards models, the latter is accomplished by using a kernel smoother for the baseline hazard function. The other proposed methodology is based on general parametric likelihood theory for right-censored data. We compared these two methods in four simulation and with one real-world dataset predicting the survival probability in patients with Hodgkin lymphoma (HL).
Results:
The simulations demonstrated that the FL models performed similarly to the non-distributed case in all four experiments, with only slight deviations in predicted survival probabilities compared to the true model. Our findings were similar in the real-world advanced-stage HL example where the FL models were compared to their non-distributed versions, revealing only small deviations in performance.
Conclusion:
The proposed procedures enable training of time-to-event models using data distributed across sites, without direct sharing of individual-level data and event times, while retaining a predictive performance on par with undistributed approaches.

Related Concept Videos
 01:03
Prediction Intervals
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
 01:07
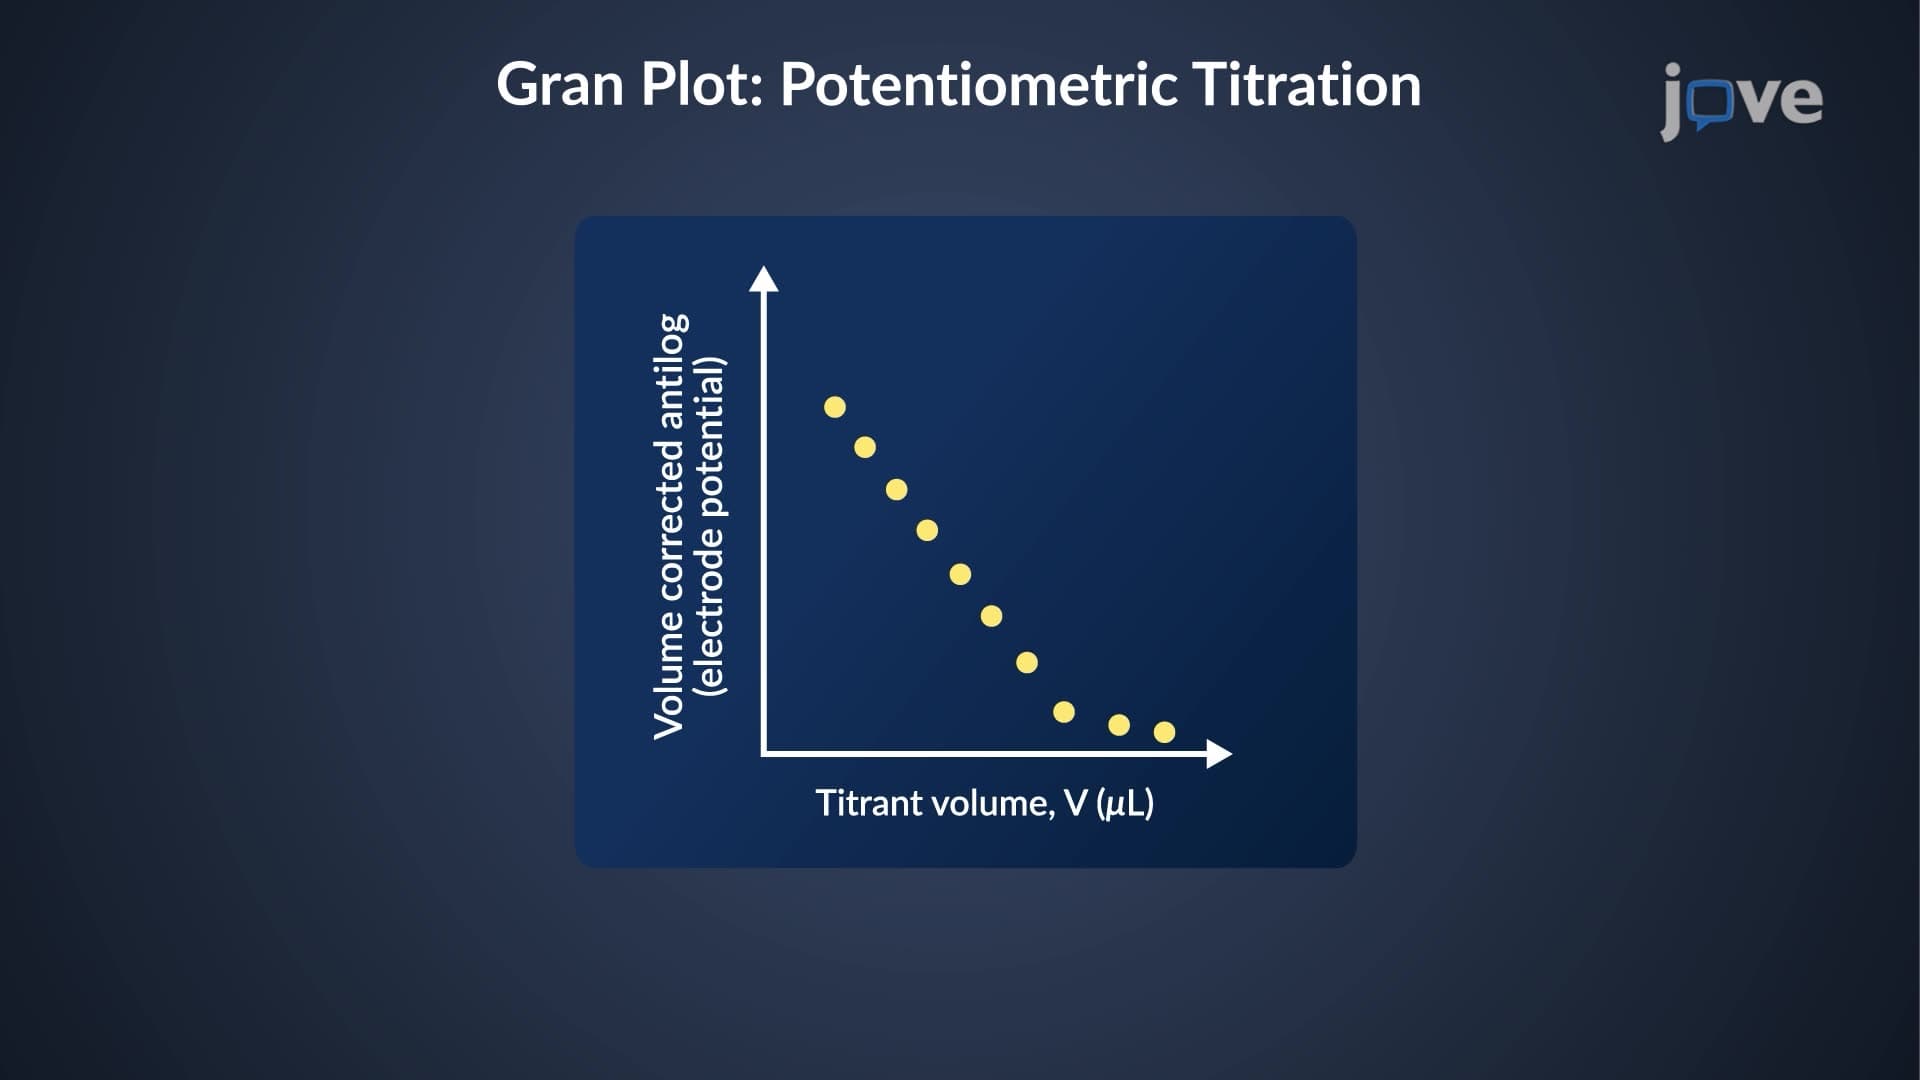
End Point Prediction: Gran Plot
For potentiometric titration, the Gran plot is created by plotting...
 01:06
Model Approaches for Pharmacokinetic Data: Distributed Parameter Models
The distributed parameter models are specifically designed to account for variations and differences in some drug classes. This model is particularly useful for assessing regional concentrations of anticancer or...
 01:27
Associative Learning
Classical conditioning, also known...
 01:29
Aggregates Classification
Petrographic classification groups aggregates based on common mineralogical characteristics. Some of the common mineral groups found in aggregates are...
 02:07
Improving Translational Accuracy