Learning contrastive semantic decomposition for visual grounding
Related Experiment Video
Updated: Sep 19, 2025
Eye Tracking During Visually Situated Language Comprehension: Flexibility and Limitations in Uncovering Visual Context Effects
Published on: November 30, 2018
Jie Wu1, Chunlei Wu1, Yiwei Wei2
1Qingdao Institute of Software, College of Computer Science and Technology, China University of Petroleum (East China), Qingdao, China.

Abstract:
Visual grounding requires accurately locating and identifying image objects or regions that are described in natural language expressions. Current research predominantly utilizes independent encoders to extract visual and textual features separately, and applies fusion encoders for integrating multimodal information. However, the independent encoders ignore the shared attributes of different modalities, which may lead to a lack of consistency in multimodal fusion. Moreover, the fusion encoders may have difficulty distinguishing overlapping and non-contributing features from different modalities, resulting in redundant fusion information. To tackle these challenges, we propose a novel Contrastive Semantic Decomposition network for Visual Grounding (CSDVG) to effectively decompose shared-specific semantic features and model cross-modality features. Our CSDVG comprises two key components: an associated semantic branch for identifying shared relevant features and an independent semantic branch for isolating specific unrelated information. To further facilitate the learning of the contrasting features mentioned above, a relevance-driven loss function is proposed to optimize the balance between shared and specific features in relation to the query. In comprehensive experiments, our CSDVG demonstrates superior performance over current approaches across all datasets.
More Related Videos
 06:33
Decomposing the Variance in Reading Comprehension to Reveal the Unique and Common Effects of Language and Decoding
Published on: October 11, 2018
 09:27
Using Eye Movements Recorded in the Visual World Paradigm to Explore the Online Processing of Spoken Language
Published on: October 13, 2018
Related Concept Videos
 01:21
Gestalt Principles of Perception
 01:26
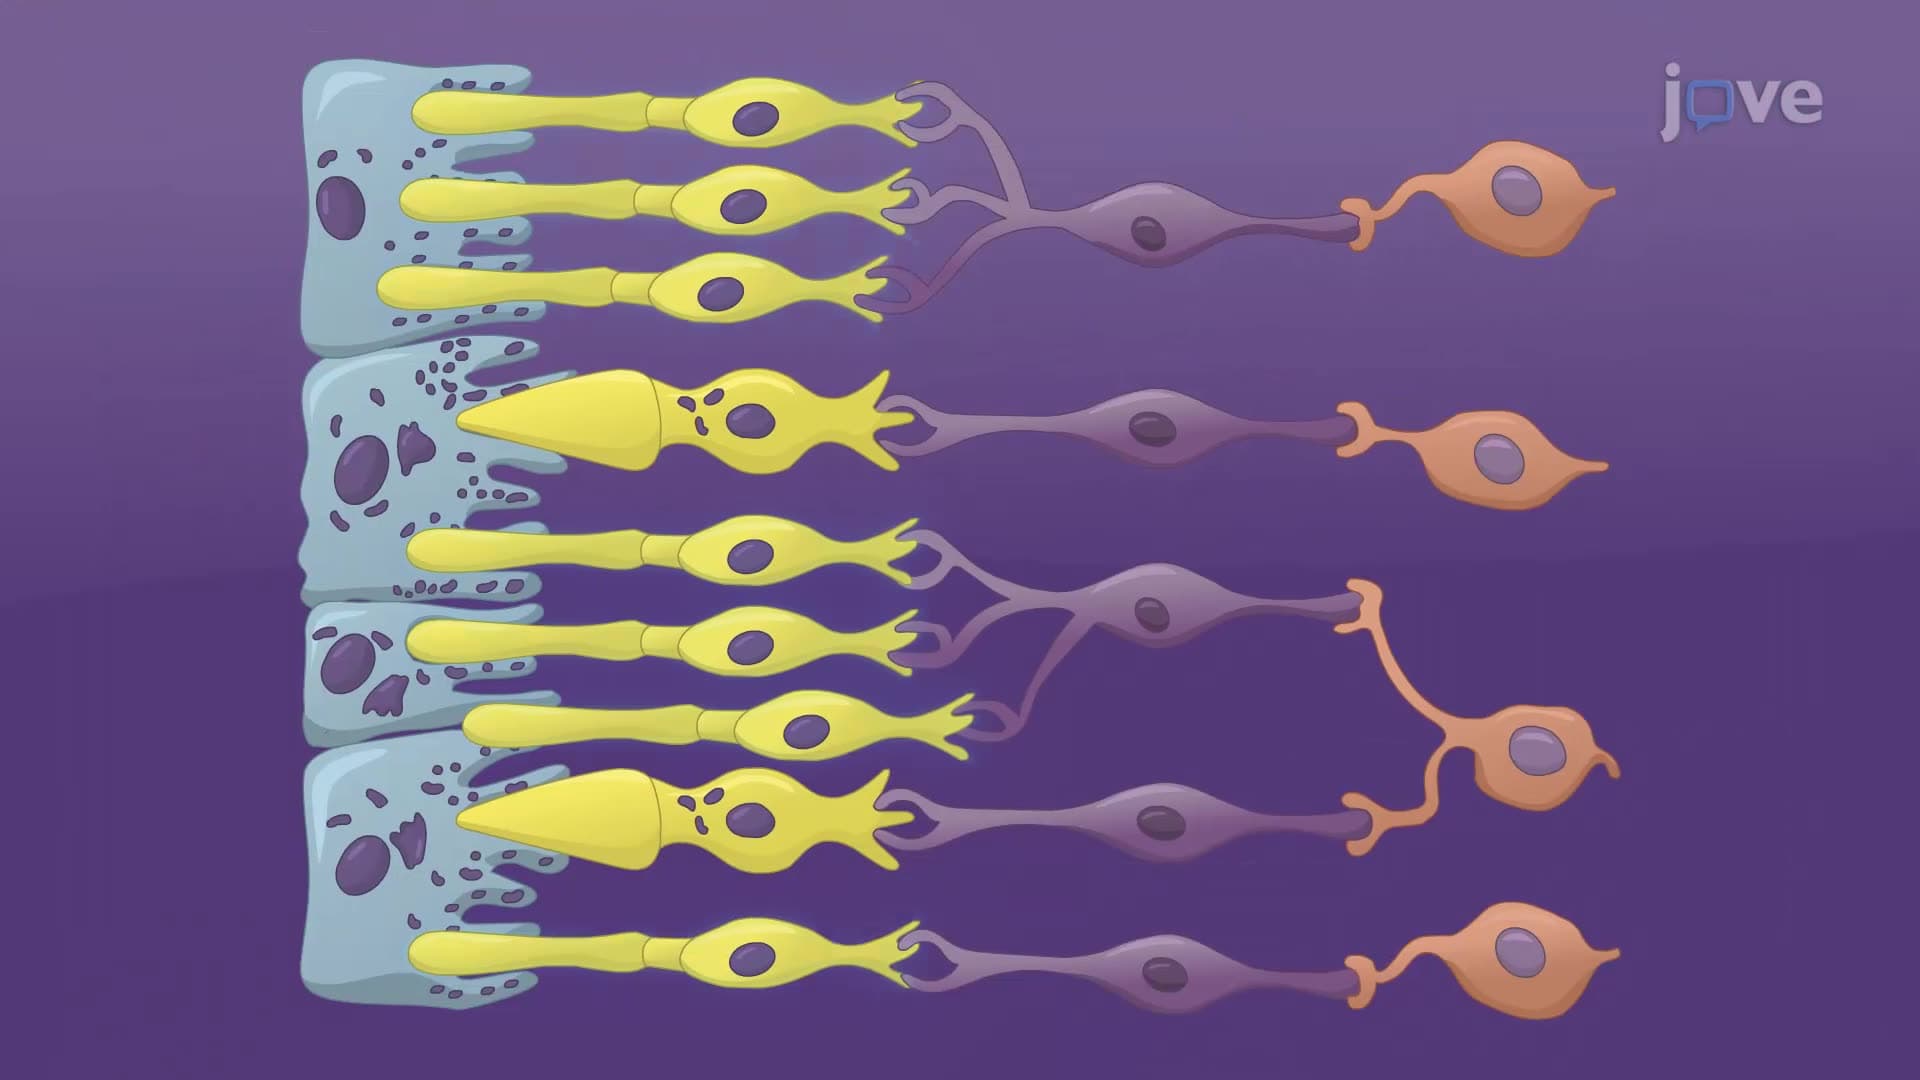
Visual System
Once through the pupil, the light passes through the lens, a...
 01:15
Depth Perception and Spatial Vision
 01:05
Difference from Background: Limit of Detection
The LOD indicates the presence or absence...
 01:20
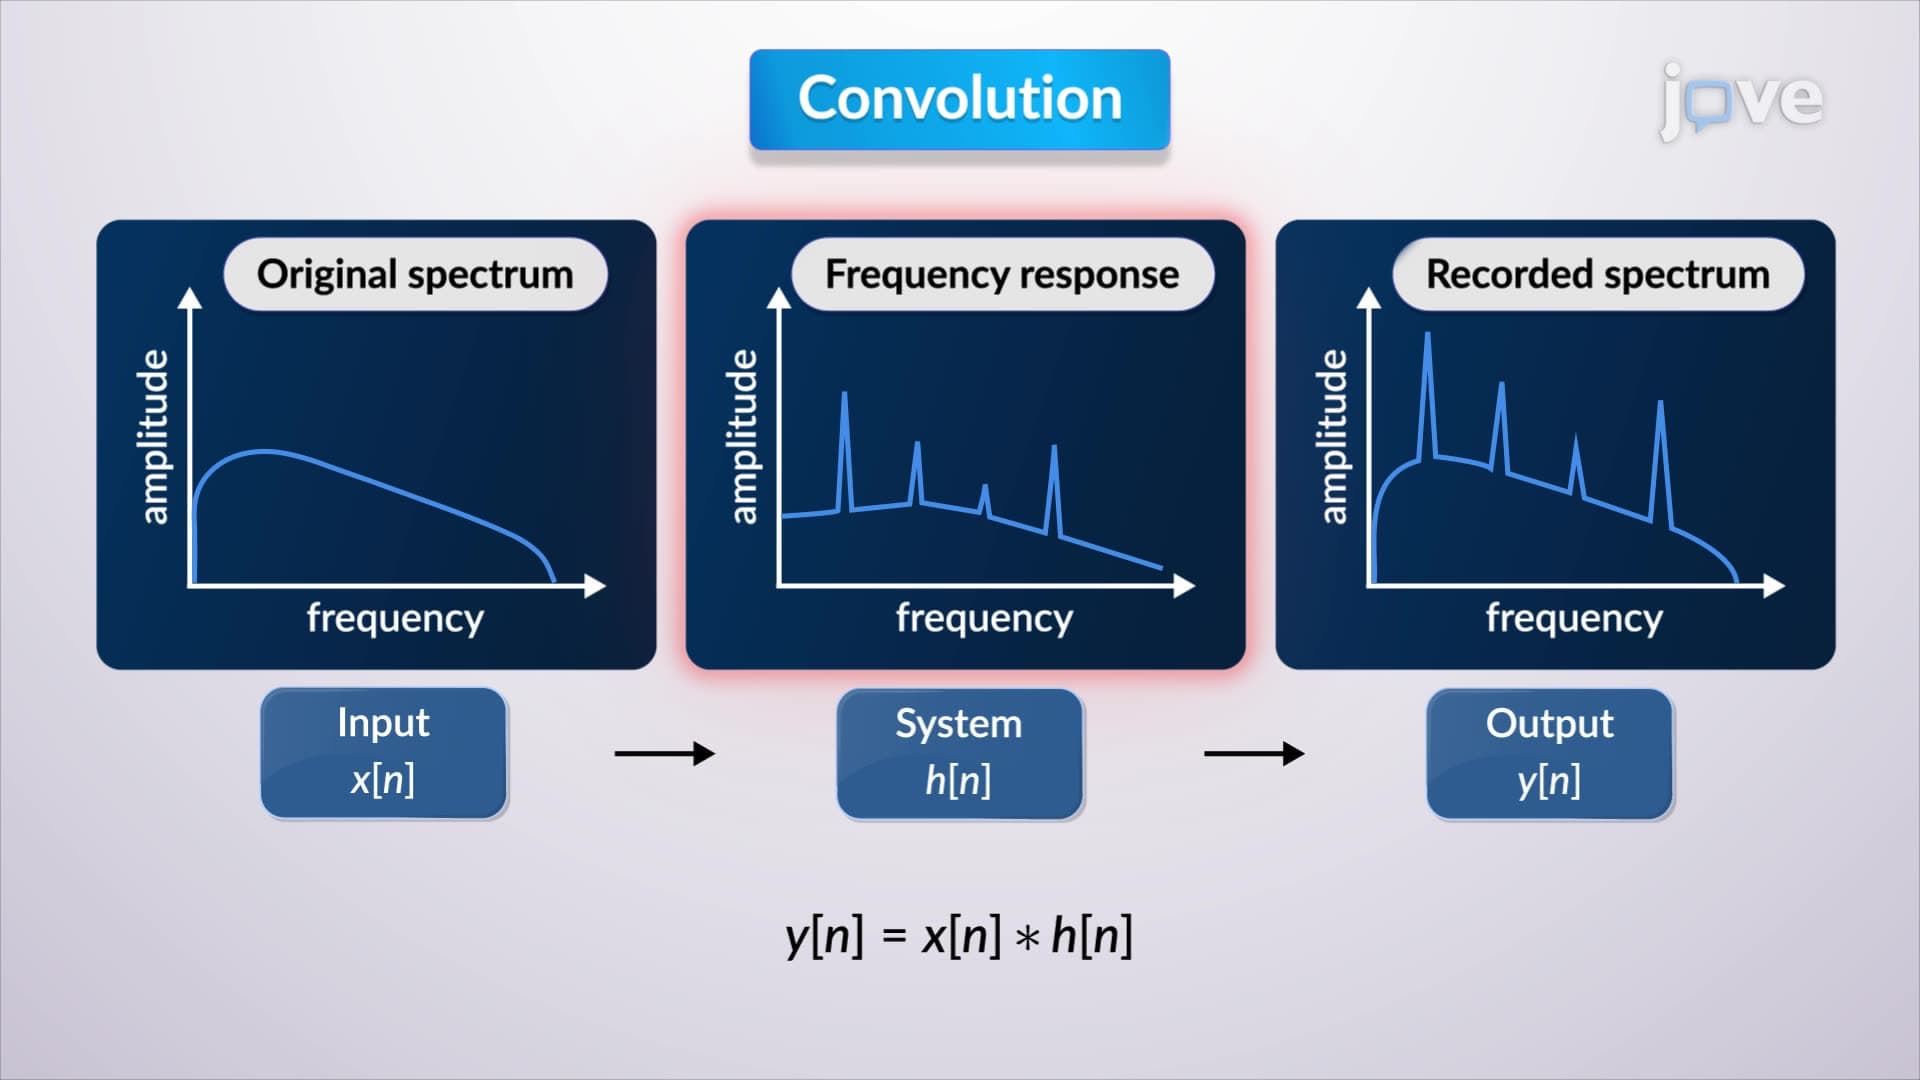
Deconvolution
Deconvolution involves several mathematical techniques to derive the impulse response. One common approach is polynomial division. In this method, the input and output sequences are treated as coefficients of...
 01:20
Structural Classification of Joints
A fibrous joint is where the adjacent bones are united by fibrous connective...