Related Experiment Video
Updated: Sep 17, 2025


Author Spotlight: Advancing Alzheimer's Research – Exploring Early Detection and Multi-Omics Approaches
Published on: December 15, 2023
LSTM autoencoder based parallel architecture for deepfake audio detection with dynamic residual encoding and feature
Priyanka Muruganandham1, Govardhana Rajan Thangasamy1, Sangeetha Jayaraman2
1Department of CSE, Srinivasa Ramanujan Centre, SASTRA Deemed to be University, Kumbakonam, 612 001, India.

Abstract:
With the rapid advancement of synthetic speech technologies, detecting deepfake audio has become essential for preventing impersonation and misinformation. This study aims to enhance detection performance by addressing limitations in existing models, such as temporal inconsistencies, weak contextual representation, and reconstruction loss. A novel framework, termed Long Short-Term Memory Auto-Encoder with Dynamic Residual Difference Encoding (LSTM-AE-DRDE), is proposed to overcome these challenges. The framework consists of two parallel modules: one leverages attention-enhanced LSTM with contrastive learning to highlight critical temporal cues, while the other amplifies real-vs-fake separability by computing residual differences across transformed audio variants. By integrating diverse speech features-including MFCC, temporal, prosodic, wavelet packet, and glottal parameters the model captures both low- and high-level audio characteristics. Experimental evaluation was carried out on five benchmark datasets (CVoice Fake, FoR, Deepfake Voice Recognition, ODSS, and CMFD), where the proposed model achieved classification accuracies of 97%, 90%, 96%, 97%, and 95%, respectively. Furthermore, when compared to eleven state-of-the-art methods, the proposed model demonstrates superior performance with an overall ROC-AUC of approximately 98%. In addition, a comprehensive feature-wise ablation study was conducted to assess the contribution of each feature set, confirming the robustness and reliability of the proposed framework.

Related Concept Videos
 01:23
Parallel Resonance
 01:21
Perceiving Loudness, Pitch, and Location
Place theory, or place coding, suggests that different pitches are heard because various sound waves activate specific locations along the cochlea's basilar membrane. The brain determines the pitch of a sound by...
 01:12
Double Resonance Techniques: Overview
Spin decoupling is usually achieved by...
 01:20
Deconvolution
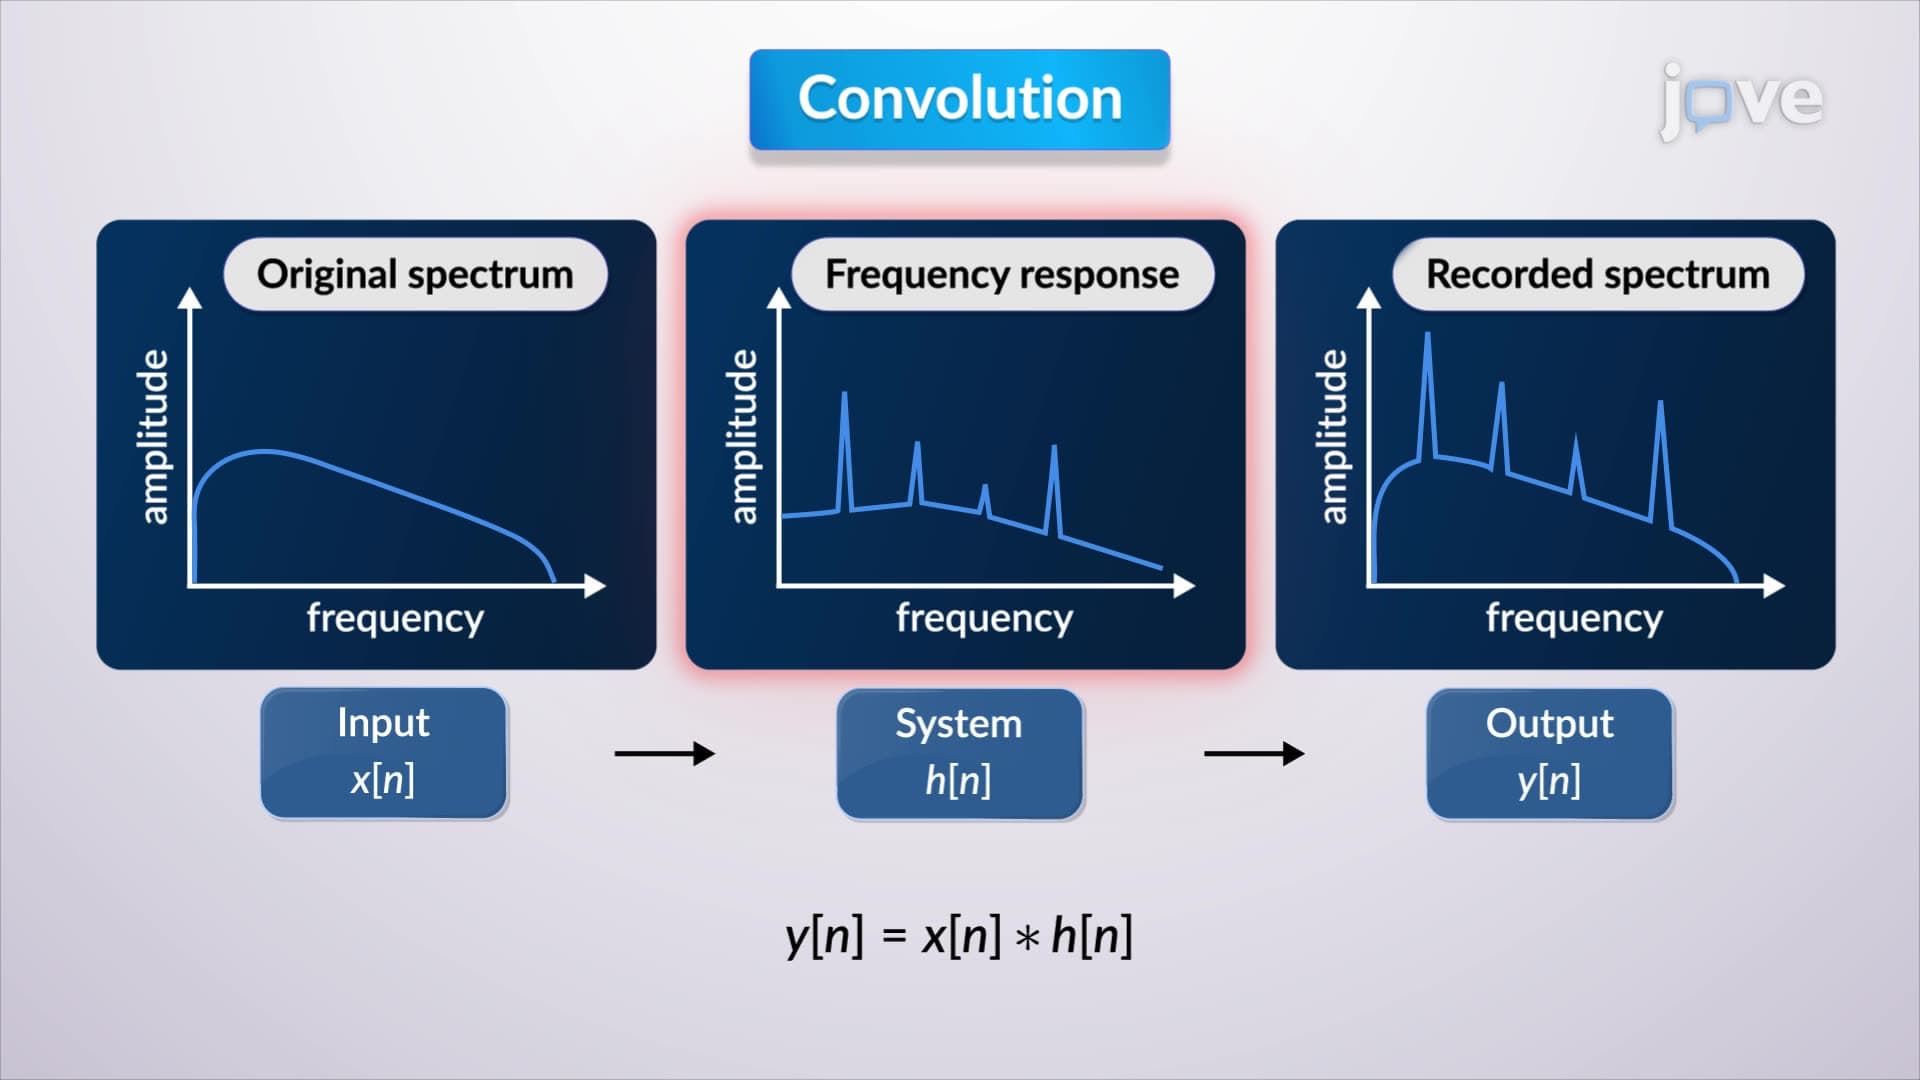
Deconvolution involves several mathematical techniques to derive the impulse response. One common approach is polynomial division. In this method, the input and output sequences are treated as coefficients of...
 01:07
Elaborative Rehearsals
The effectiveness of...
 01:26
Linear Approximation in Frequency Domain
In contrast, nonlinear systems do not inherently possess these properties. However, for small deviations around an operating point, a nonlinear system can often be approximated as linear....