Related Experiment Video
Updated: Sep 12, 2025

Lexical Decision Task for Studying Written Word Recognition in Adults with and without Dementia or Mild Cognitive Impairment
Published on: June 25, 2019
The practice of aggregating lower level predictors in clustered data: A reflection on reflective variables
Timothy R Konold1, Elizabeth A Sanders2
1School of Education and Human Development, University of Virginia.

Abstract:
The manifest aggregation of scores from both persons and items in multilevel modeling has been previously shown to result in biased estimates of predictor-outcome regression coefficients when used in the context of formative variables-variables in which the level two (L2) aggregate is formed from level one scores but where individuals are still expected to vary within clusters. Solutions to this problem have been offered in the form of partially and fully latent variable modeling specifications. The current study revisits this issue in the context of reflective variables, situations in which level one scores are obtained for the sole purpose of measuring an L2 variable. Under design specifications consistent with an L2 reflective variable, the current study uses population formula-based computations as well as Monte Carlo simulations to show conditions under which researchers may use a manifest aggregation of scores from persons and items for evaluating L2 relationships, thereby overcoming model convergence and identification challenges related to using latent variable modeling. We also highlight instances in which latent aggregations should be preferred. (PsycInfo Database Record (c) 2025 APA, all rights reserved).
More Related Videos
 06:52
Using Cholesky Decomposition to Explore Individual Differences in Longitudinal Relations between Reading Skills
Published on: September 17, 2019
 10:43
Eye-tracking Technology and Data-mining Techniques used for a Behavioral Analysis of Adults engaged in Learning Processes
Published on: June 10, 2021
Related Concept Videos
 01:25
Multiple Regression
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
 01:12
Hindsight Biases
 01:19
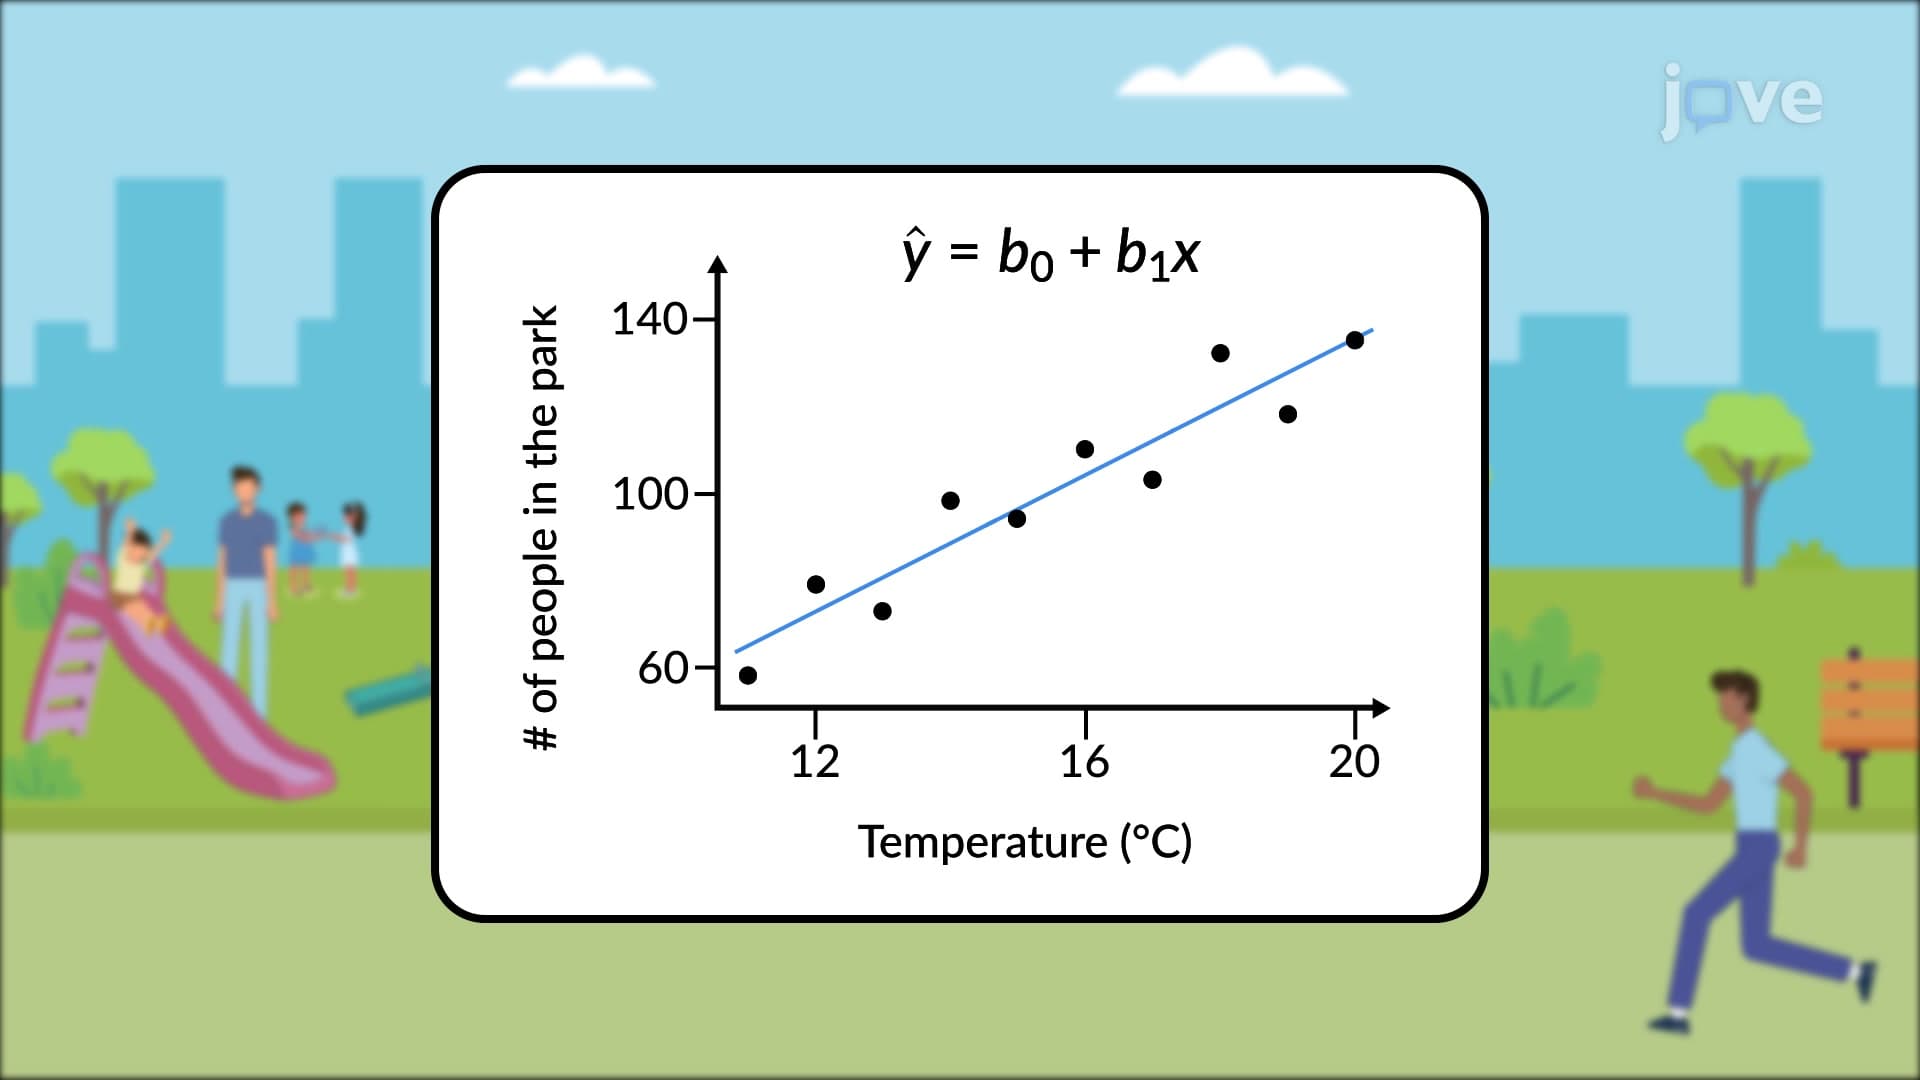
Variation
When independent and dependent variables are plotted on a scatter plot, the slope of a line is a value that describes the rate of change between the two...
 01:52
Regression Toward the Mean
 01:19
Survival Tree
Building a Survival Tree
Constructing a...
 01:23
Sampling Plans
Random sampling is a method where each member of the population has an equal chance of being selected for the sample. It involves selecting individuals randomly, often using random number generators or lottery-type methods. For example, when analyzing the properties of a...