Related Experiment Video
Updated: Sep 12, 2025

Using the Race Model Inequality to Quantify Behavioral Multisensory Integration Effects
Published on: May 10, 2019
Feature-splitting Algorithms for Ultrahigh Dimensional Quantile Regression
Jiawei Wen1, Songshan Yang2, Christina Dan Wang3
1Meta Platforms Inc., 1 Hacker Way, Menlo Park, CA 94025, USA.

Abstract:
This paper is concerned with computational issues related to penalized quantile regression (PQR) with ultrahigh dimensional predictors. Various algorithms have been developed for PQR, but they become ineffective and/or infeasible in the presence of ultrahigh dimensional predictors due to the storage and scalability limitations. The variable updating schema of the feature-splitting algorithm that directly applies the ordinary alternating direction method of multiplier (ADMM) to ultrahigh dimensional PQR may make the algorithm fail to converge. To tackle this hurdle, we propose an efficient and parallelizable algorithm for ultrahigh dimensional PQR based on the three-block ADMM. The compatibility of the proposed algorithm with parallel computing alleviates the storage and scalability limitations of a single machine in the large-scale data processing. We establish the rate of convergence of the newly proposed algorithm. In addition, Monte Carlo simulations are conducted to compare the finite sample performance of the proposed algorithm with that of other existing algorithms. The numerical comparison implies that the proposed algorithm significantly outperforms the existing ones. We further illustrate the proposed algorithm via an empirical analysis of a real-world data set.


Related Concept Videos
 01:02
Quantifying and Rejecting Outliers: The Grubbs Test
 01:14
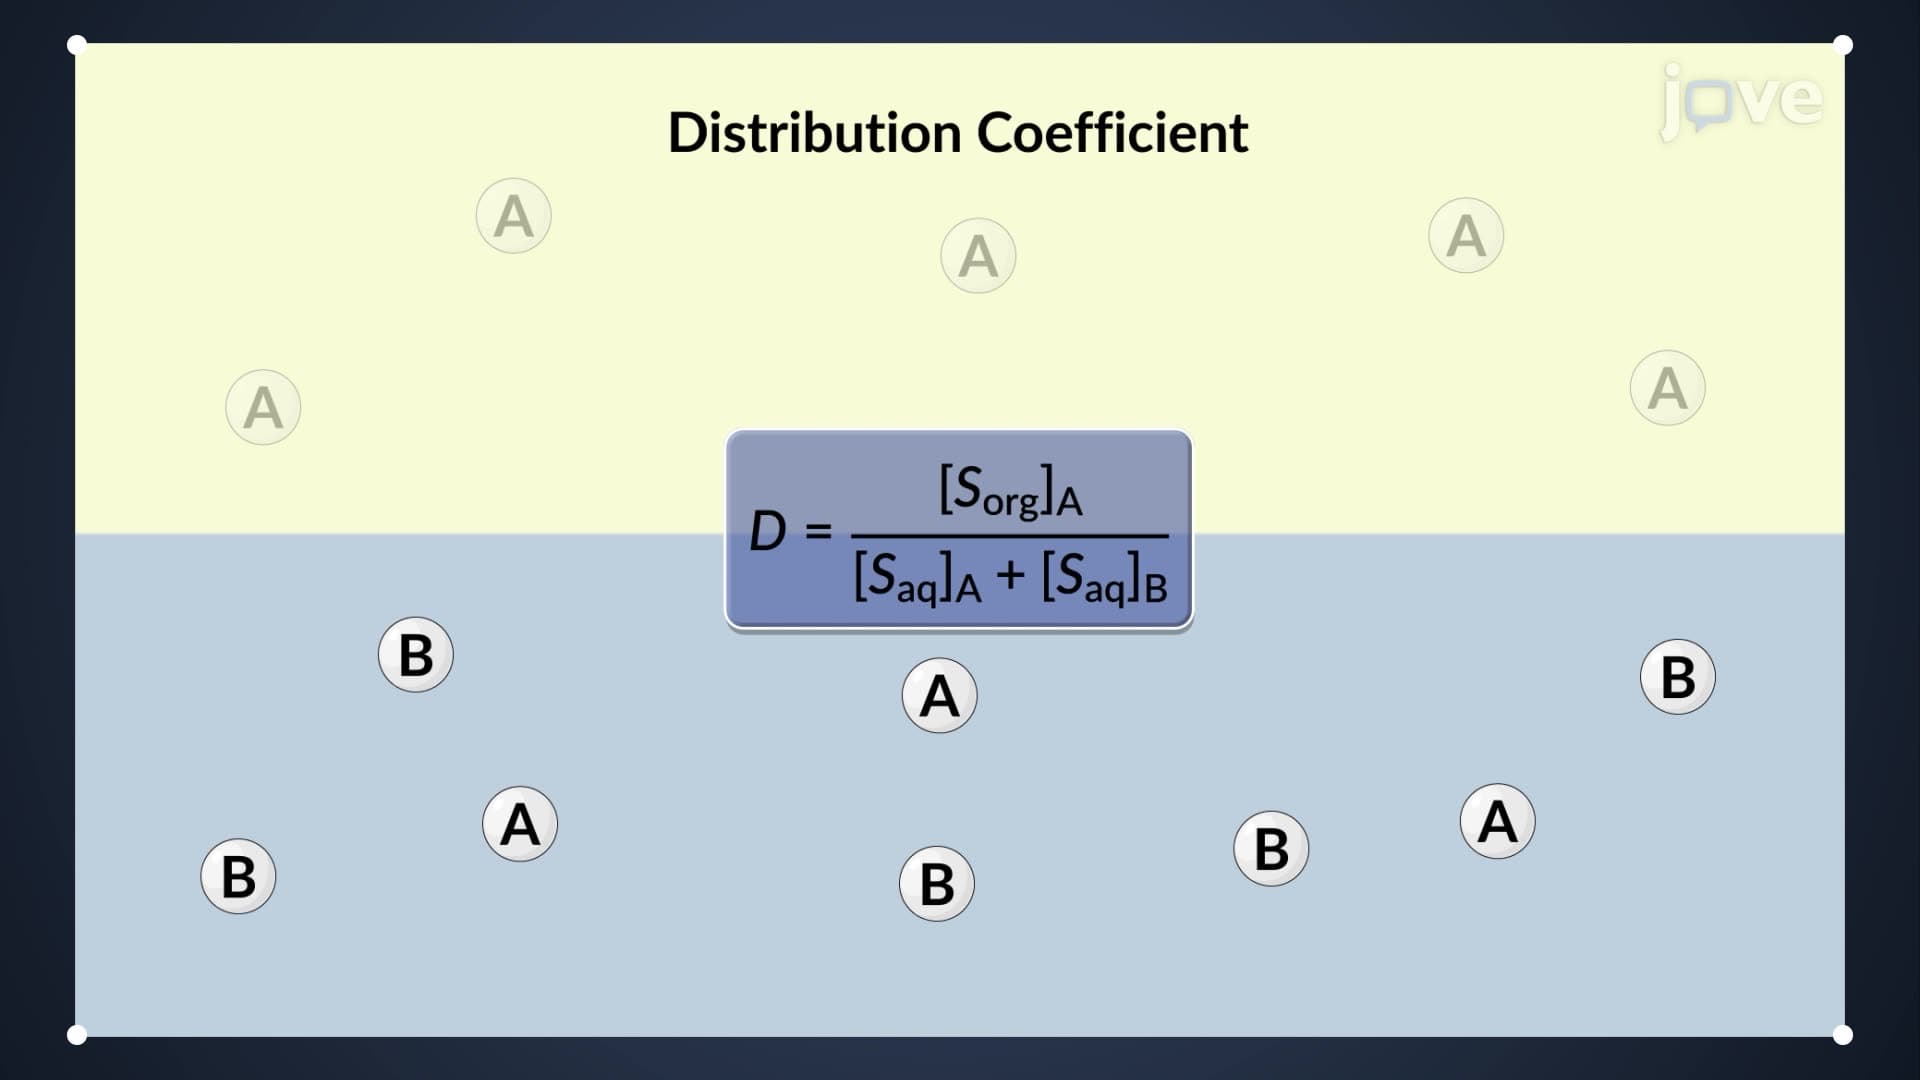
Extraction: Partition and Distribution Coefficients
For extracting a solute from an aqueous phase into an...
 01:15
Quartile
1; 1; 2; 2; 4; 6; 6.8; 7.2; 8; 8.3; 9; 10; 10; 11.5
The median or second quartile is seven. The lower half of the...
 00:57
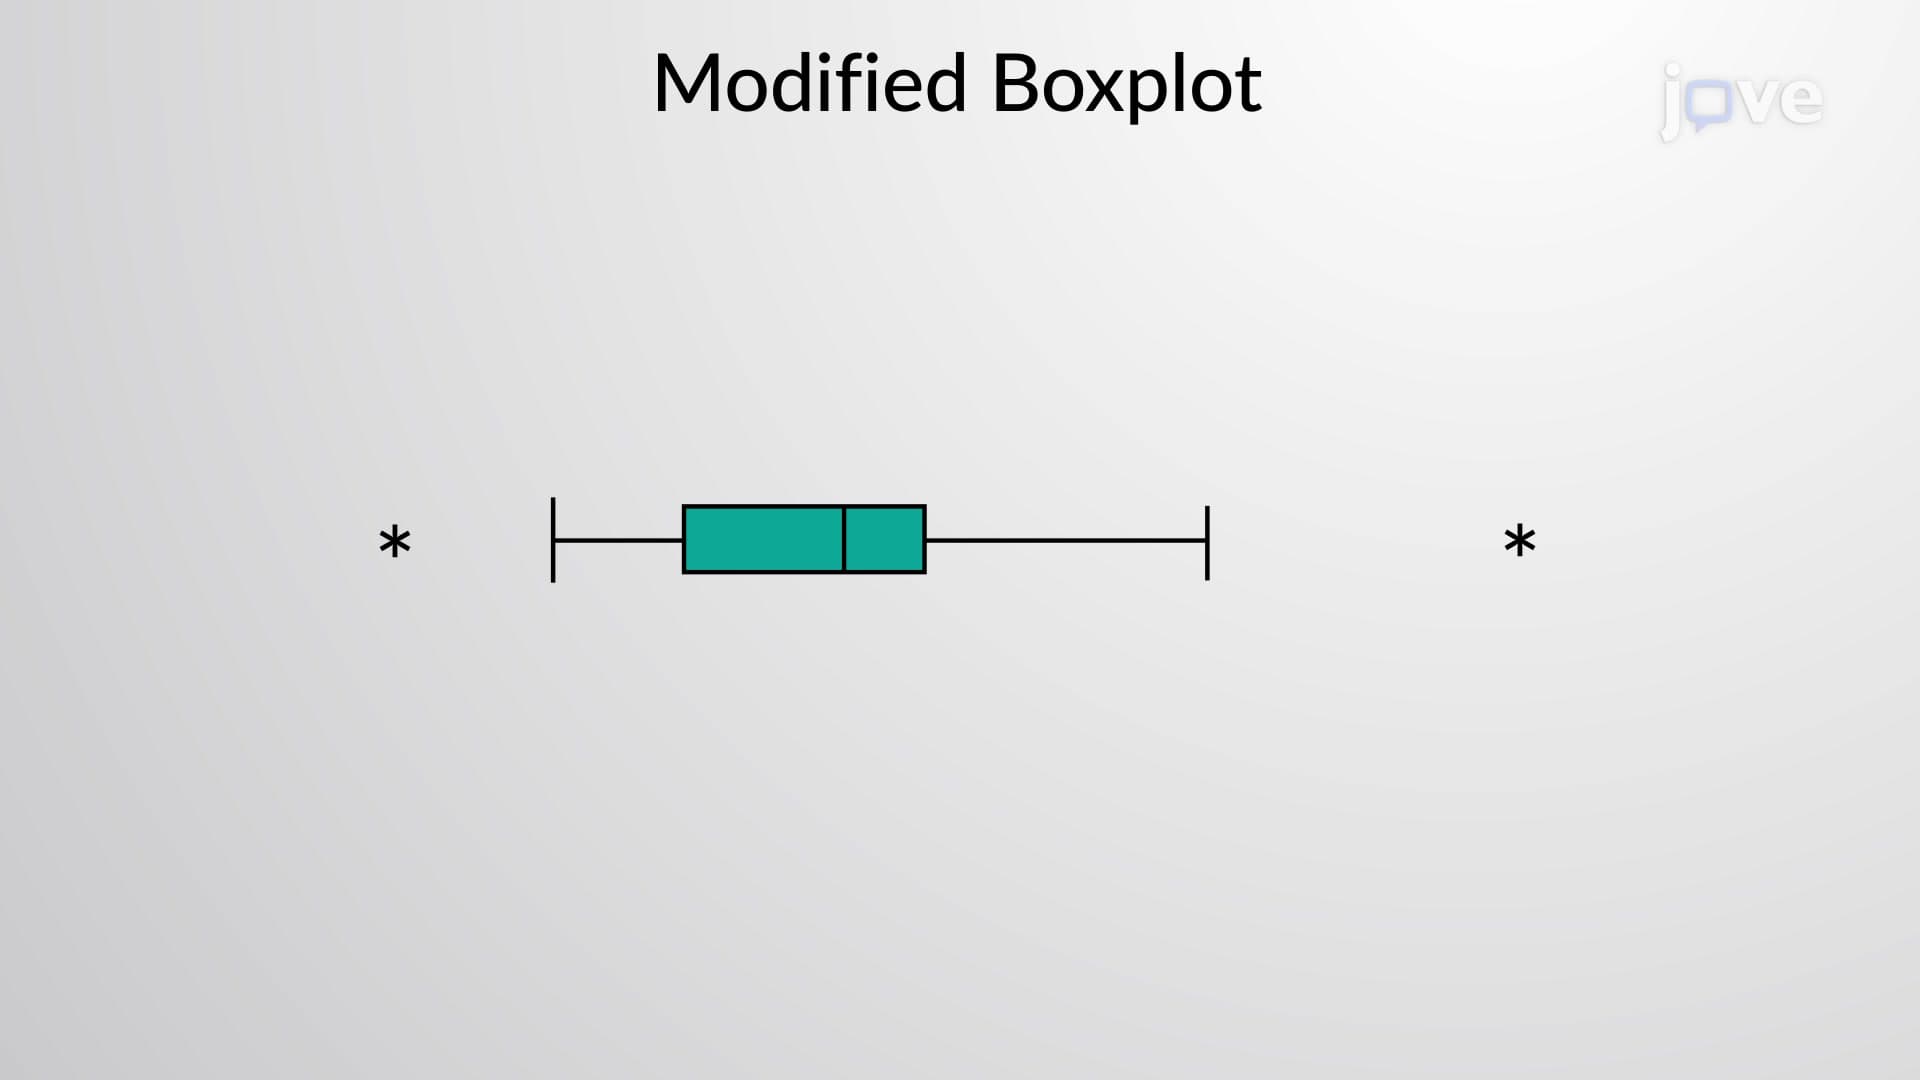
Modified Boxplots
However, the box plot does not tell the reader about outliers - values that lie far from the center of the data. We can modify the standard box and whisker plot to identify the outliers and visualize the actual spread of the data in a sample.
Initially, we calculate the adjusted...
 01:08
Outliers and Influential Points
 01:21
Friedman Two-way Analysis of Variance by Ranks