Related Experiment Video
Updated: Sep 10, 2025

Development of a Gaze-Contingent Display Framework Designed for Perceptual and Oculomotor Research with Simulated Central Vision Loss
Published on: April 11, 2025
Specialized curricula for training vision language models in retinal image analysis
Robbie Holland1, Thomas R P Taylor2, Christopher Holmes3
1Biomedical Image Analysis, Department of Computing, Imperial College London, London, United Kingdom. robbie.holland@stanford.edu.

Abstract:
Clinicians spend significant time reviewing medical images and transcribing findings. By integrating visual and textual data, foundation models have the potential to reduce workloads and boost efficiency, yet their practical clinical value remains uncertain. In this study, we find that OpenAI's ChatGPT-4o and two medical vision-language models (VLMs) significantly underperform ophthalmologists in key tasks for age-related macular degeneration (AMD). To address this, we developed a dedicated training curriculum, designed by domain specialists, to optimize VLMs for tasks related to clinical decision making. The resulting model, RetinaVLM-Specialist, significantly outperforms foundation medical VLMs and ChatGPT-4o in AMD disease staging (F1: 0.63 vs. 0.33) and referral (0.67 vs. 0.50), achieving performance comparable to junior ophthalmologists. In a reader study, two senior ophthalmologists confirmed that RetinaVLM's reports were substantially more accurate than those written by ChatGPT-4o (64.3% vs. 14.3%). Overall, our curriculum-based approach offers a blueprint for adapting foundation models to real-world medical applications.
Related Concept Videos
 01:24
Vision
 01:26
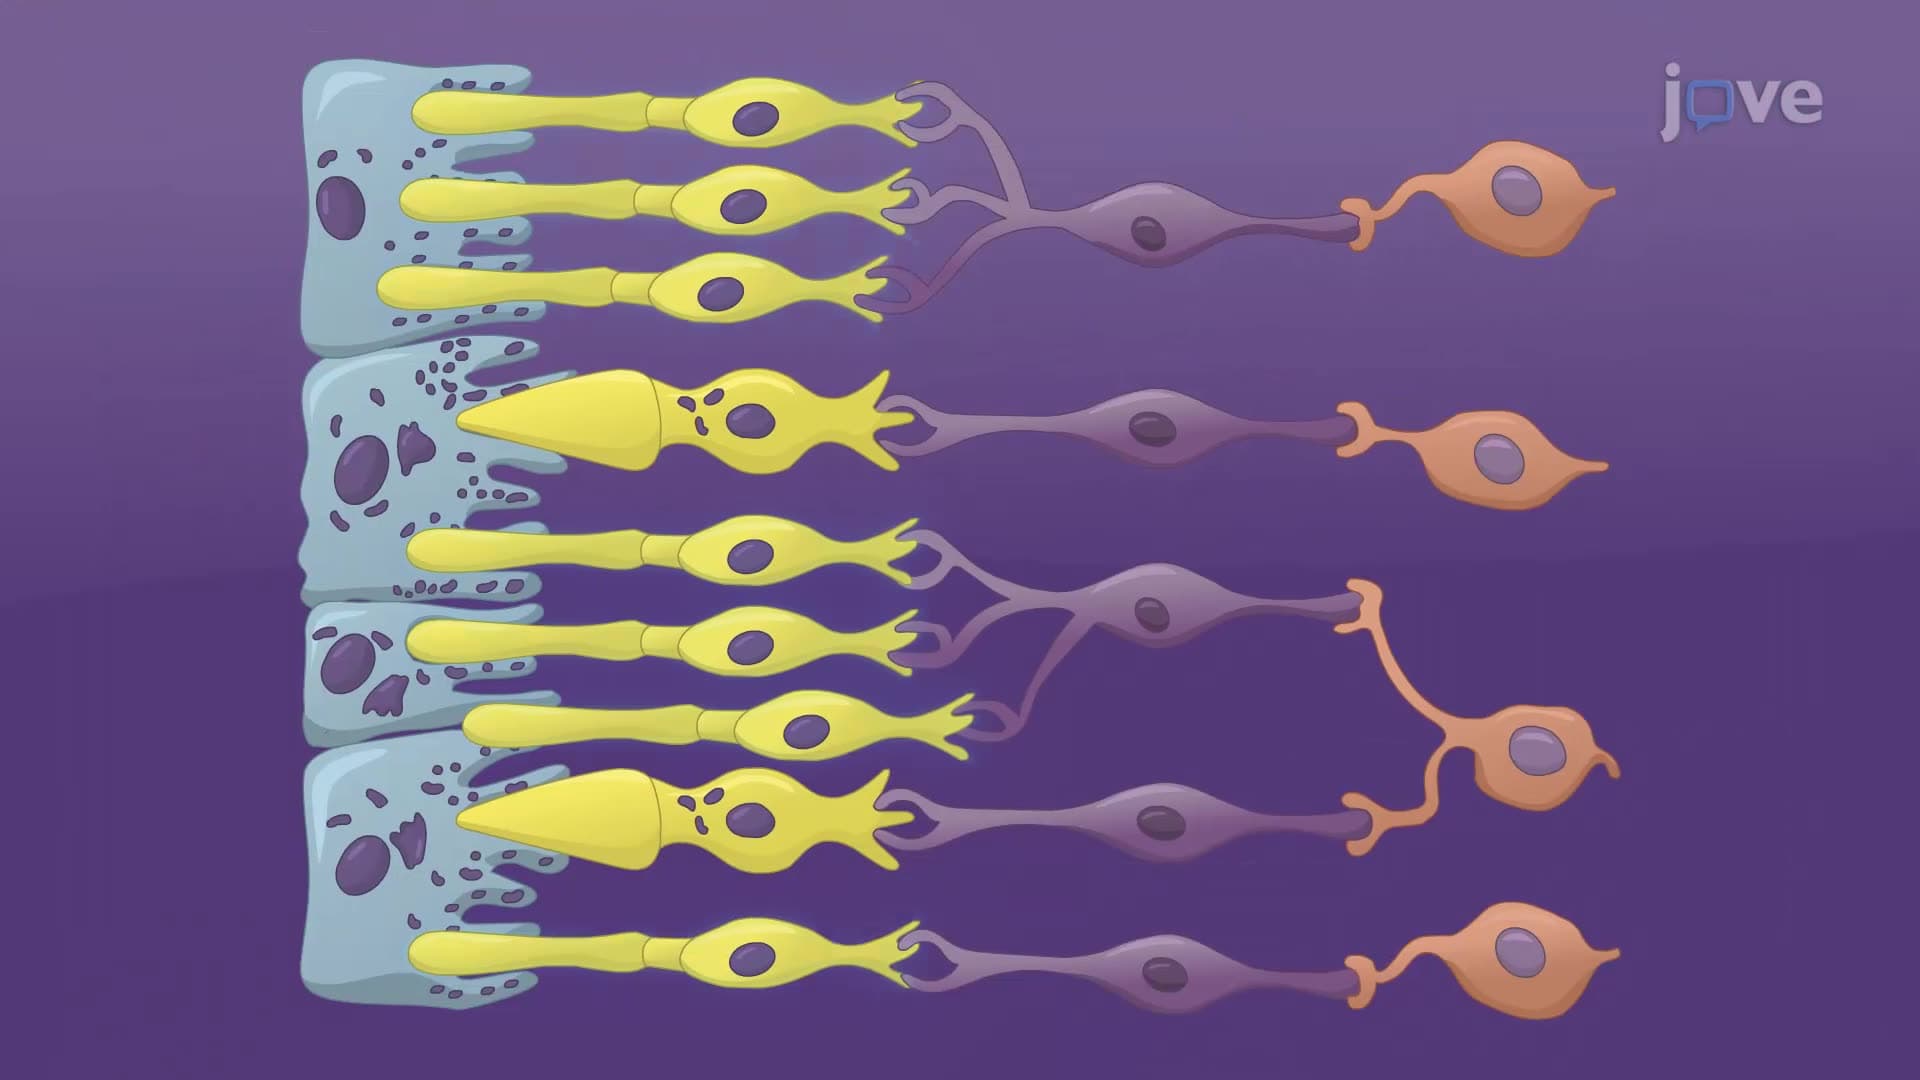
Visual System
Once through the pupil, the light passes through the lens, a...