Learning Compact Discriminant Representation via Low-Rank Bilinear Pooling
Related Experiment Video
Updated: Sep 10, 2025

Author Spotlight: Enhancement of Salient Object Detection for Smart Grid Applications
Published on: December 15, 2023

Abstract:
In this paper, we explain the mechanism of bilinear pooling as a module of hard sample generation, and find that bilinear pooling significantly expands variances of the first-order vectors when it produces discriminative bilinear features. In conjunction with the extremely high dimensionality of the obtained bilinear features, those variances lead to overfitting in subsequent learning models. To solve this issue, we construct a bi-level optimization problem, where the high-level problem is the supervised classification loss, and the low-level problem is the principal component analysis (PCA). Then, we find that PCA on bilinear features is equivalent to spectral clustering, which allows us to mathematically prove that the first $\log _{2}(C)$log2(C) principal components can support the discriminant information of $C$C classes. By removing the rest principal components, the dimensionality and variances are simultaneously reduced. To the best of our knowledge, this is the first work providing a lower bound for dimension reduction for bilinear pooling. However, the PCA projection matrix $\mathbf{L}$L is prone to overfitting due to having many parameters. To address this issue, we propose a rank-$k$k general bilinear projection (RK-GBP) that decomposes $\mathbf{L}$L into two small matrices $\mathbf{U}$U and $\mathbf{V}$V, whose learnable parameters are smaller. Different from traditional bilinear projections used in factorized bilinear pooling (FBiP), our RK-GBP can preserve the orthogonality of columns in $\mathbf{L}$L by constraining the orthogonality of columns in $\mathbf{U}$U and $\mathbf{V}$V. For computational efficiency, we relax the PCA in the low-level task into a dictionary learning problem, obtaining the rank-$k$k orthogonal factorization bilinear pooling (RK-OFBP). The RK-OFBP can be considered as a general form of current factorization bilinear pooling methods (e.g., Hadamard product-based ones). Finally, we evaluate our approach on fine-grained images and large-scale datasets, demonstrating that our proposed method not only produces extremely low-dimensional features but also outperforms other methods in classification tasks. For example, our RK-OFBP can employ 32-dimensional vectors to achieve comparable results to B-CNN (Lin, 2015) (dimension: 512*512) for the 200-class classification task.

Related Concept Videos
 01:20
Downsampling
The Fourier transform of the decimated sequence reveals a combination of scaled and shifted versions of the original spectrum. This...
 01:14
Extraction: Partition and Distribution Coefficients
For extracting a solute from an aqueous phase into an...
 01:11
Residuals and Least-Squares Property
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
 01:26
Linear Approximation in Frequency Domain
In contrast, nonlinear systems do not inherently possess these properties. However, for small deviations around an operating point, a nonlinear system can often be approximated as linear....
 01:19
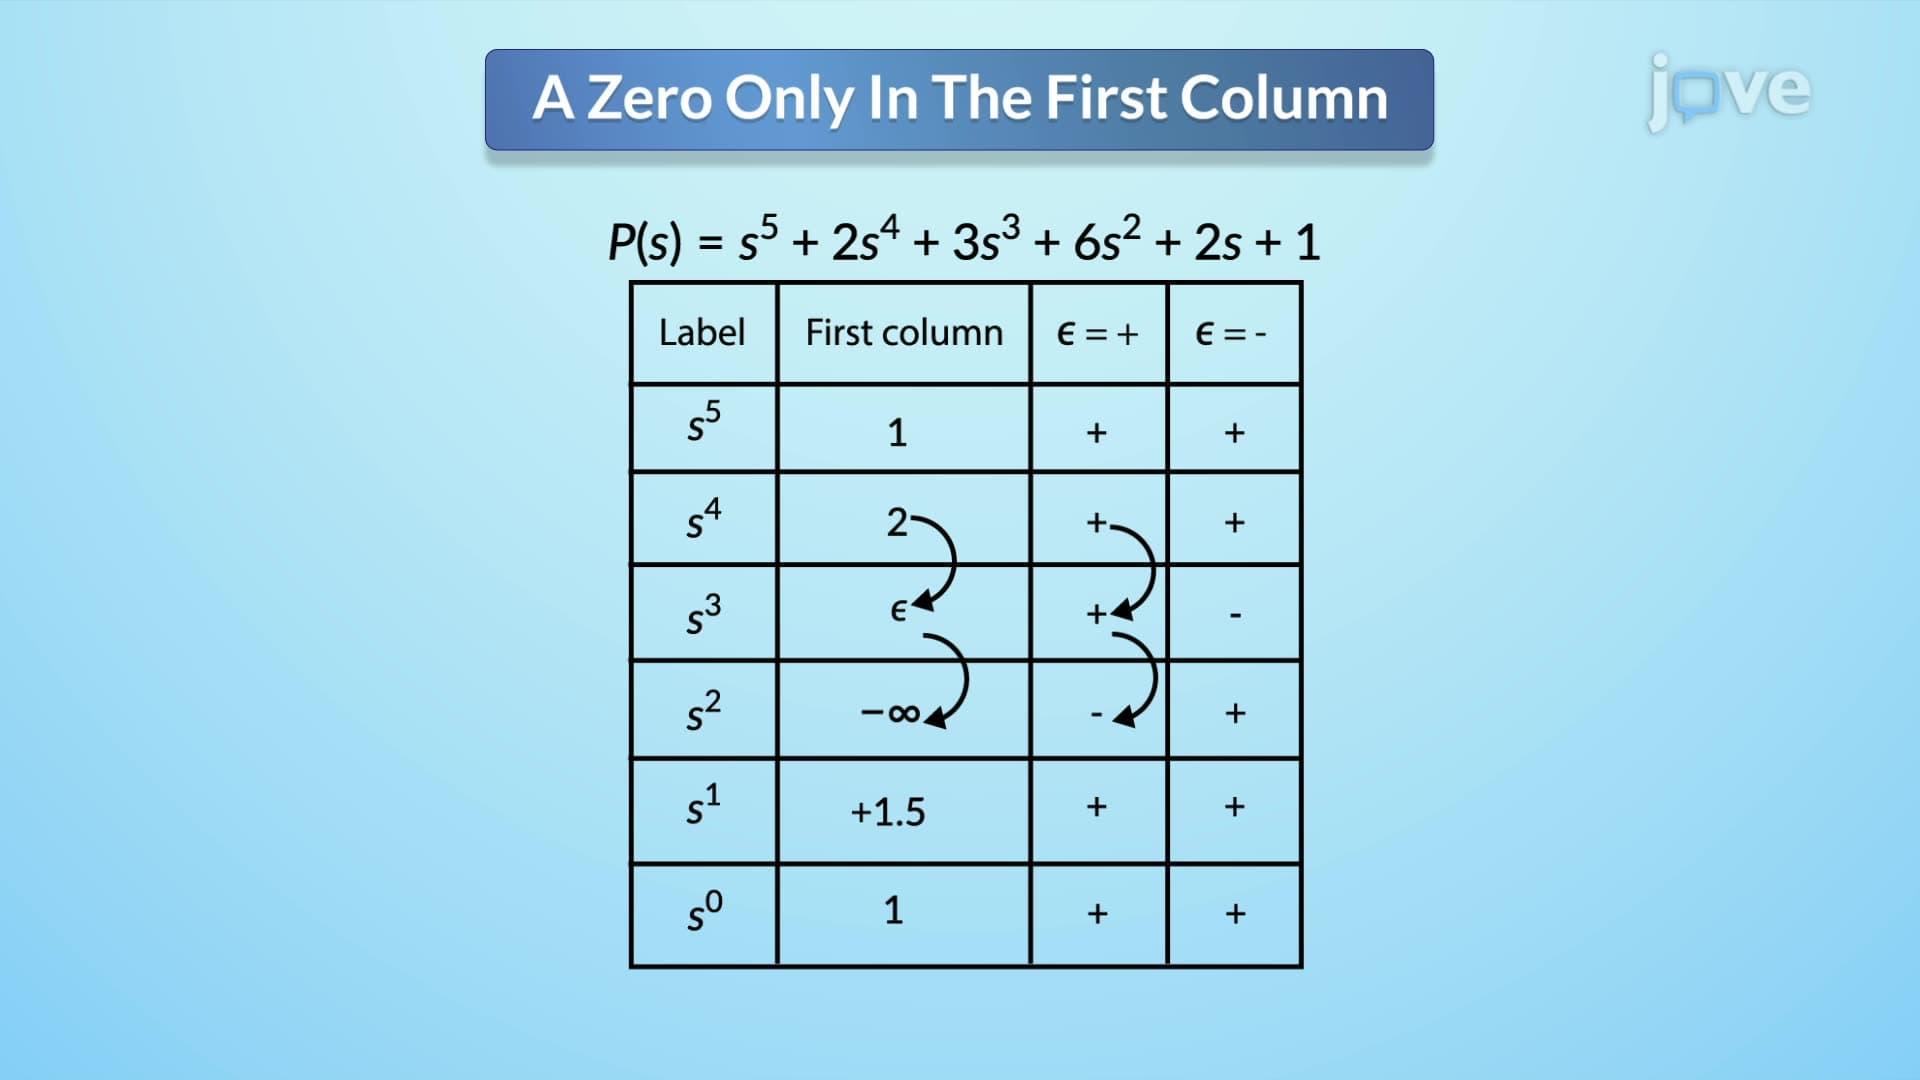
Routh-Hurwitz Criterion II
The first scenario occurs when a singular zero appears in the first column of the Routh table. This situation creates a division by zero issues. To resolve this, a small positive or negative number, denoted as epsilon (∈), is substituted for the zero. The stability analysis proceeds by assuming a sign for ∈. If ∈ is positive, any sign change in the first...
 01:20
Deconvolution
Deconvolution involves several mathematical techniques to derive the impulse response. One common approach is polynomial division. In this method, the input and output sequences are treated as coefficients of...