Related Experiment Video
Updated: Sep 9, 2025
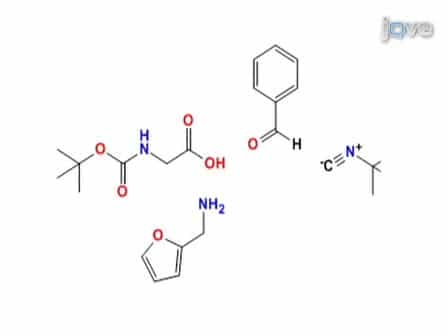

Optimization of the Ugi Reaction Using Parallel Synthesis and Automated Liquid Handling
Published on: November 11, 2008
Optimizing Model Learning Performance on a Challenging Heck Reaction Yield Data Set
Shen Wang1,2, Yining Liu1,3, Weiren Zhao1,3
1State Key Laboratory of Fine Chemicals, Dalian University of Technology, Dalian 116024, China.

Abstract:
The development of machine learning (ML) in organic synthesis is limited due to the lack of available data sets. The ML-compatible literature data set for Heck reaction yields, named HeckLit, has been established. With 10,002 cases, the data set spans multiple reaction subclasses and covers a larger chemical space compared to high-throughput experimentation data sets, including nearly 3.6 × 10¹² accessible cases. HeckLit accelerates the advancement of ML-driven synthesis research; however, it suffers from the same dilemma as other literature-based data sets, sparse distribution and high-yield preference, leading to limited model learning ability on the test set, with R2 = 0.318. Thus, feature distribution smoothing (FDS) and subset splitting training strategy (SSTS) are utilized to tackle this issue. Despite no improvement when using FDS, SSTS boosted the R2 to 0.380. This optimization approach relies on the subset division. Therefore, we suggest a criterion for splitting. The SSTS opens up a new avenue for tackling the challenge of learning from large-scale data sets.
More Related Videos
Related Concept Videos
 02:24
Predicting Reaction Outcomes
 02:22
Reaction Yield
 03:09
Measuring Reaction Rates
 02:35
Reaction Quotient
 03:00
Standard Entropy Change for a Reaction
 02:46
E1 Reaction: Kinetics and Mechanism