Related Experiment Video
Updated: Jan 17, 2026


Selecting Multiple Biomarker Subsets with Similarly Effective Binary Classification Performances
Published on: October 11, 2018
Leveraging external information by guided adaptive shrinkage to improve variable selection in high-dimensional
Mark A van de Wiel1, Wessel N van Wieringen1,2
1Department of Epidemiology and Data Science, Amsterdam Public Health Research Institute, Amsterdam University Medical Centers, Amsterdam, The Netherlands.

Abstract:
Variable selection is challenging for high-dimensional data, in particular when sample size is low. It is widely recognized that external information in the form of complementary data on the variables, 'co-data', may improve results. Examples are known variable groups or p-values from a related study. Such co-data are ubiquitous in genomics settings due to the availability of public repositories, and is likely equally relevant for other applications. Yet, the uptake of prediction methods that structurally use such co-data is limited. We review guided adaptive shrinkage methods: a class of regression-based learners that use co-data to adapt the shrinkage parameters, crucial for the performance of those learners. We discuss technical aspects, but also the applicability in terms of types of co-data that can be handled. This class of methods is contrasted with several others. In particular, group-adaptive shrinkage is compared with the better-known sparse group-lasso by evaluating variable selection. Moreover, we demonstrate the versatility of the guided shrinkage methodology by showing how to 'do-it-yourself': we integrate implementations of a co-data learner and the spike-and-slab prior for the purpose of improving variable selection in genetics studies. We conclude with a real data example.
Related Concept Videos
 01:52
Regression Toward the Mean
 01:25
Multiple Regression
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
 01:11
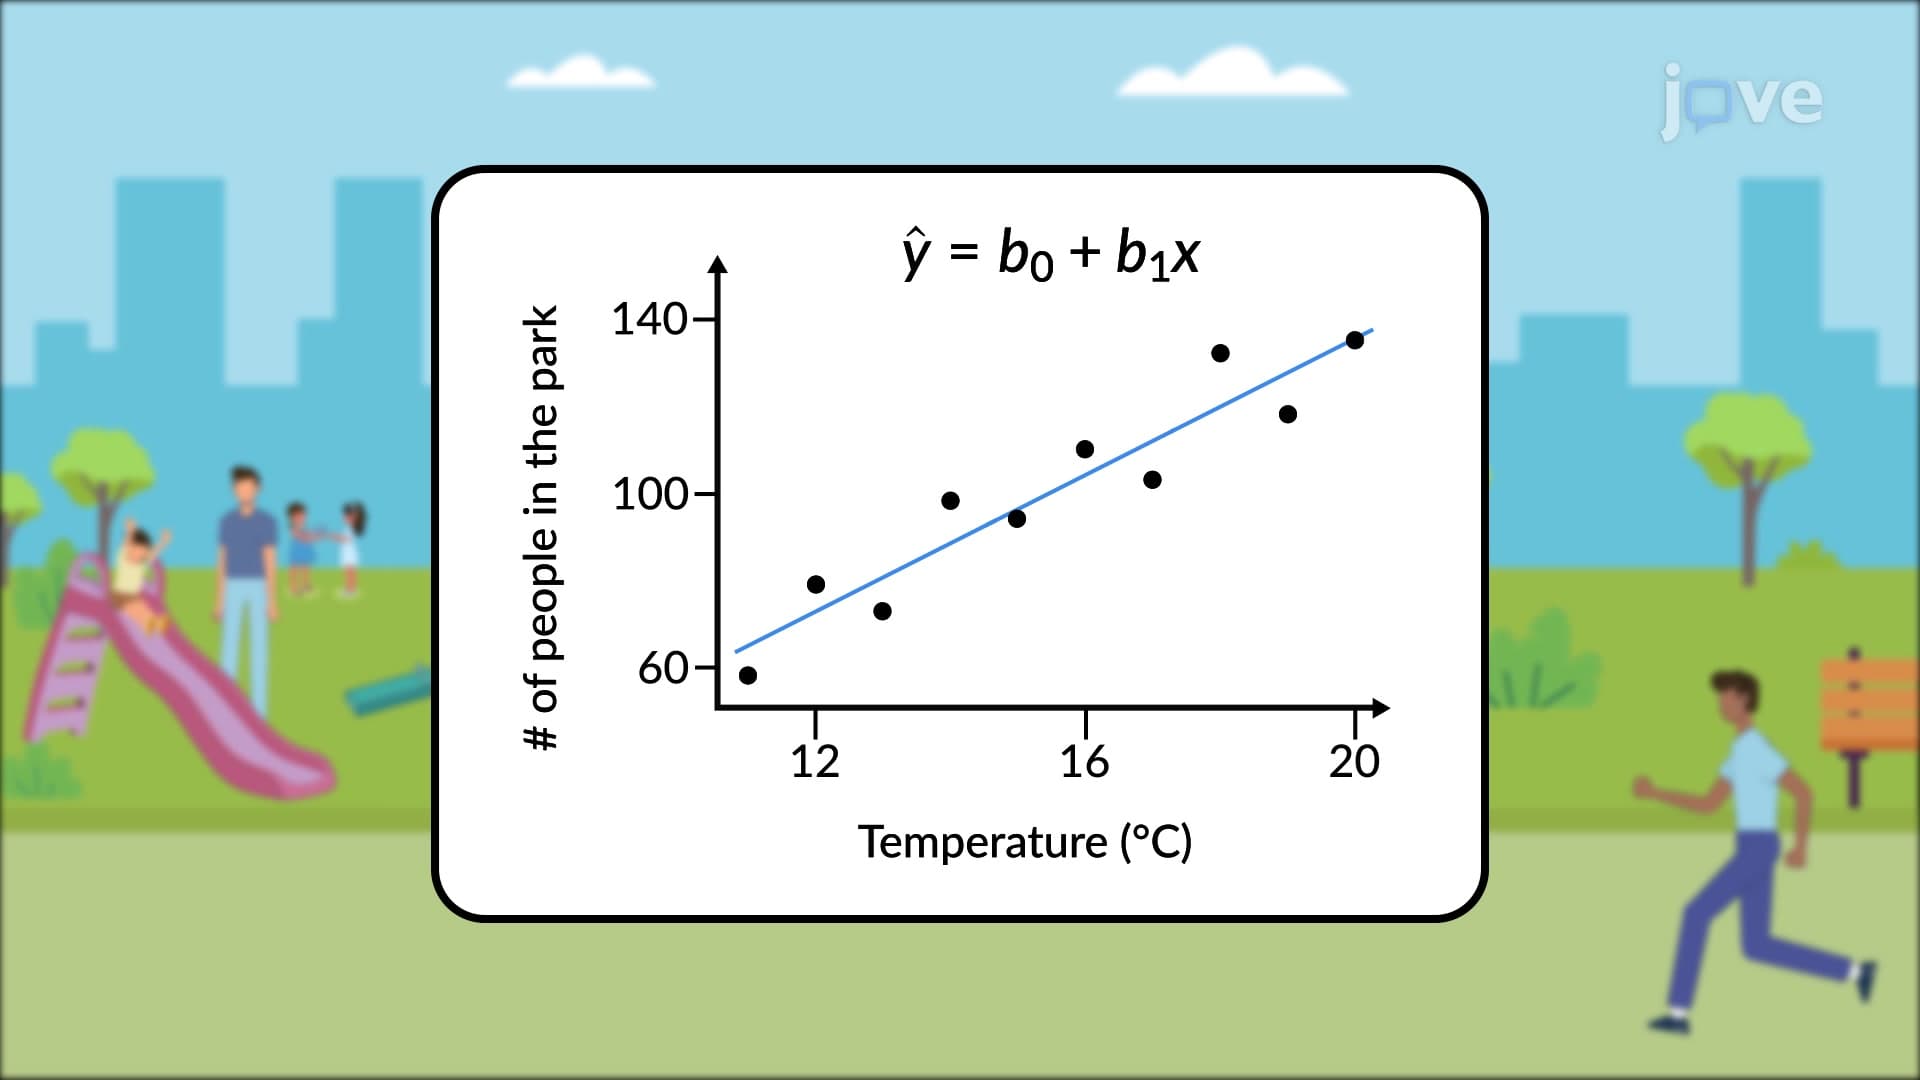
Regression Analysis
In regression analysis, a regression equation is determined based on the line of best fit– a line that best fits the data points plotted in a graph. This line is also called the regression line. The algebraic equation for the regression line is called the regression equation. It is represented as:
 01:19
Survival Tree
Building a Survival Tree
Constructing a...
 01:19
Variation
When independent and dependent variables are plotted on a scatter plot, the slope of a line is a value that describes the rate of change between the two...
 01:08
Outliers and Influential Points