KuSarcasm: Automated annotation of a sarcasm dataset using hybrid NLP techniques
Related Experiment Video
Updated: Jul 22, 2026
Fine-Tuning Large Language Models Using Entity Hallucination Index for Text Summarization
Published on: January 9, 2026
Shakhawan Aghajan1, Rebwar M Nabi1,2
1Information Technology Department, Sulaimani Polytechnic University, Sulaymaniyah, Iraq.

Abstract:
This paper presents KuSarcasm, a Kurdish Sorani dataset developed for the automatic detection of sarcasm expressions. KuSarcasm represents a carefully constructed resource designed to address the challenges of sarcasm identification in Sorani Kurdish, a linguistically rich but low-resource language with limited Natural Language Processing (NLP) resources. The dataset was compiled through a multi-stage process of data collection and annotation, guided by linguistic expertise and methodology. Source material was drawn from culturally significant repositories, including Kurdish proverbs, poetry, idiom collections, literary magazines such as Sekhurma, digital publications, and web archives. Extensive consultations with Kurdish linguists, editors, and researchers ensured robust annotation guidelines and cultural authenticity. Data collection relied primarily on manual efforts, complemented by Optical Character Recognition (OCR) for printed texts, web scraping, structured documentation, and filtering-based extraction, resulting in 16,833 entries. The dataset underwent comprehensive preprocessing, including deduplication, normalization, and noise removal. Automatic labelling was conducted using a locally tuned hybrid approach involving multilingual sentiment classification through Multilingual-Bidirectional Encoder Representations for Transformers (mBERT) and semantic similarity scoring through Sentence-Bidirectional Encoder Representations for Transformers (SBERT). A rule-based framework with over 100 predefined linguistic patterns further distinguished sarcastic from non-sarcastic texts based on emotional polarity and semantic proximity. Every entry is further annotated with metadata like source, matched rule, and sentiment category. Considering its scale, cultural depth, and methodological rigor, KuSarcasm provides a significant benchmark for low-resource language research, sentiment analysis, and computational linguistics while establishing a strong foundation for deep learning model development.
Related Concept Videos
 01:08
Nitriles to Carboxylic Acids: Hydrolysis
 01:30
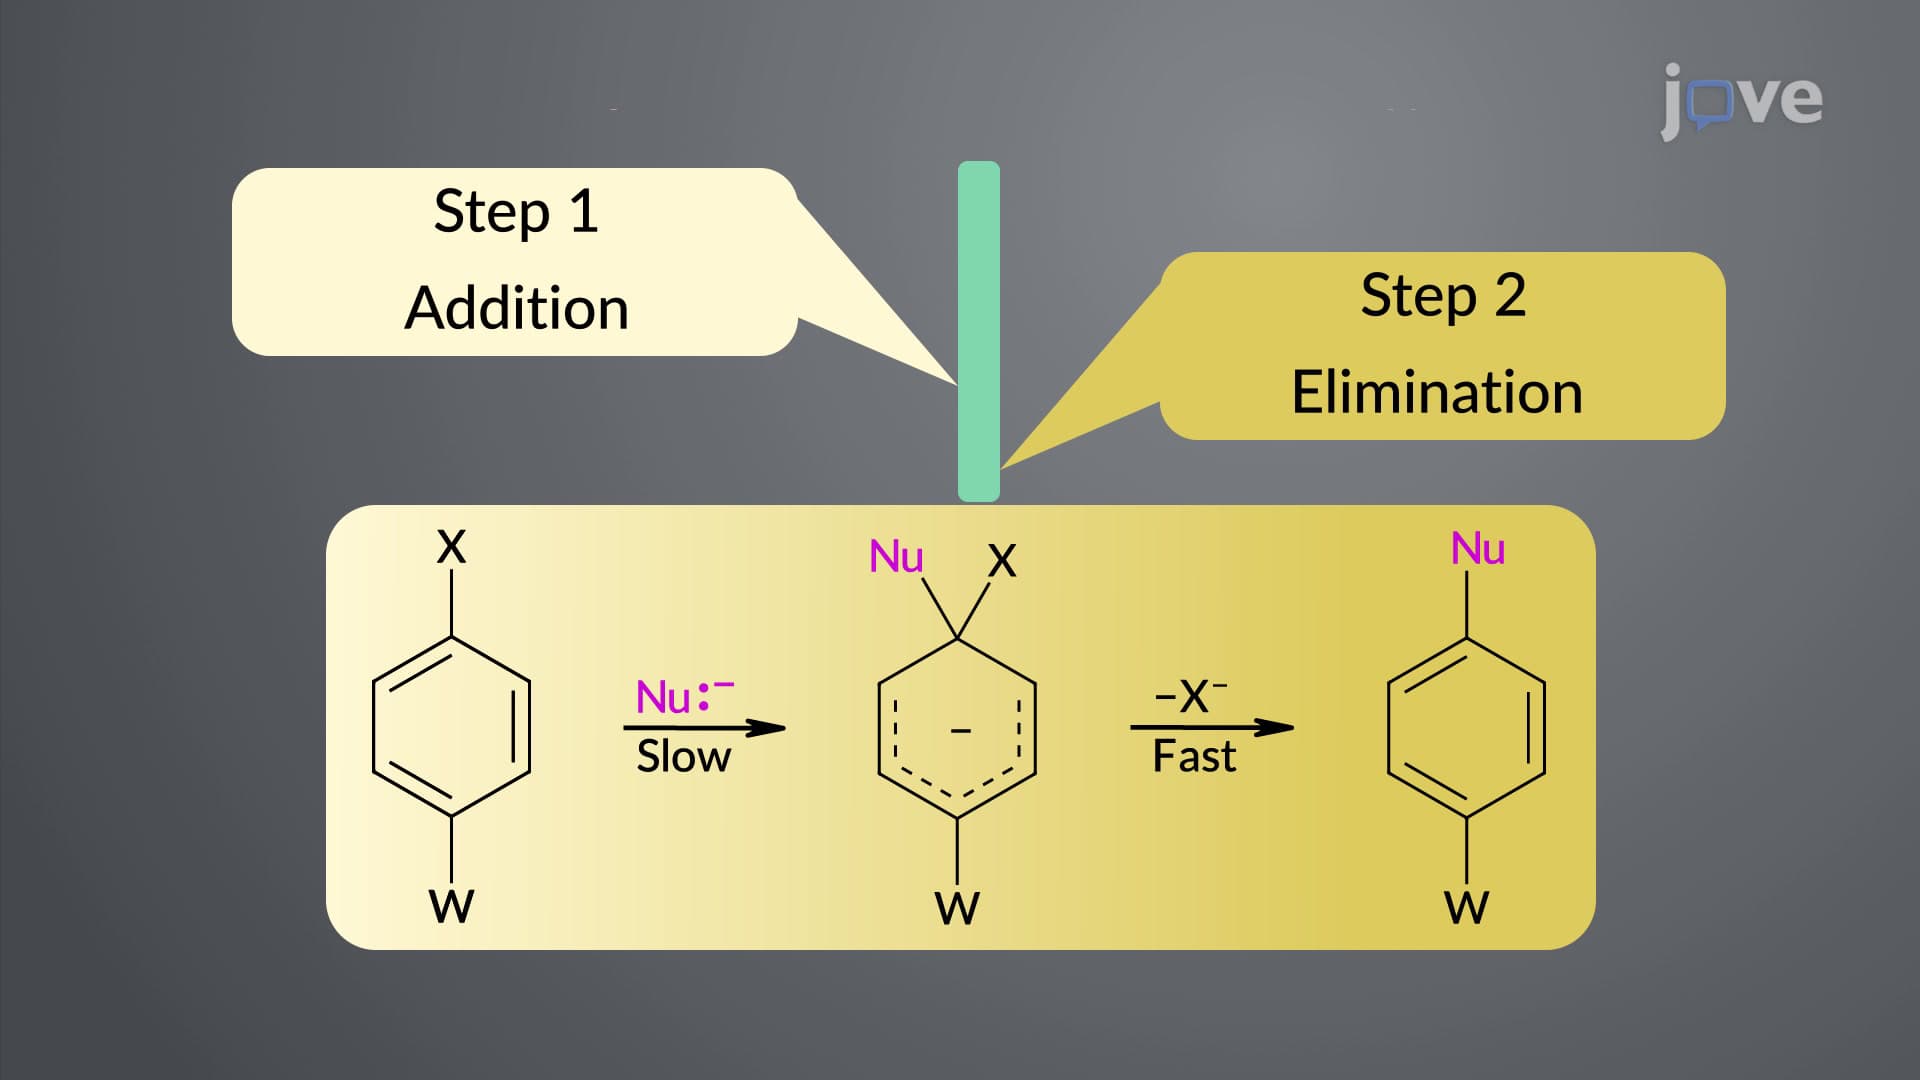
Nucleophilic Aromatic Substitution: Addition–Elimination (SNAr)
The reaction begins with an attack of the nucleophile on the carbon that holds the leaving group. This results in the delocalization of the π electrons over the ring carbons. The resonance interaction between...
 01:31
Hybridoma Technology
Hybridoma Selection
Commonly used fusion techniques — electroporation,...
 01:14
SBAR II: Application of SBAR
SBAR Report from a Nurse to a Health Care Provider
S: "Hello, Dr. Smith. This is Jane, RN, from the Med Surg unit. I am calling to tell you about Ms. White in Room 210, who is experiencing increased pain and redness at her incision site. Her recent...
 01:31
Sympathetic Signaling
Sympathetic preganglionic fibers release the neurotransmitter acetylcholine (ACh) onto the ganglionic neurons in the...
 01:16
Sympathetic Activation