Related Experiment Video
Updated: Jan 9, 2026
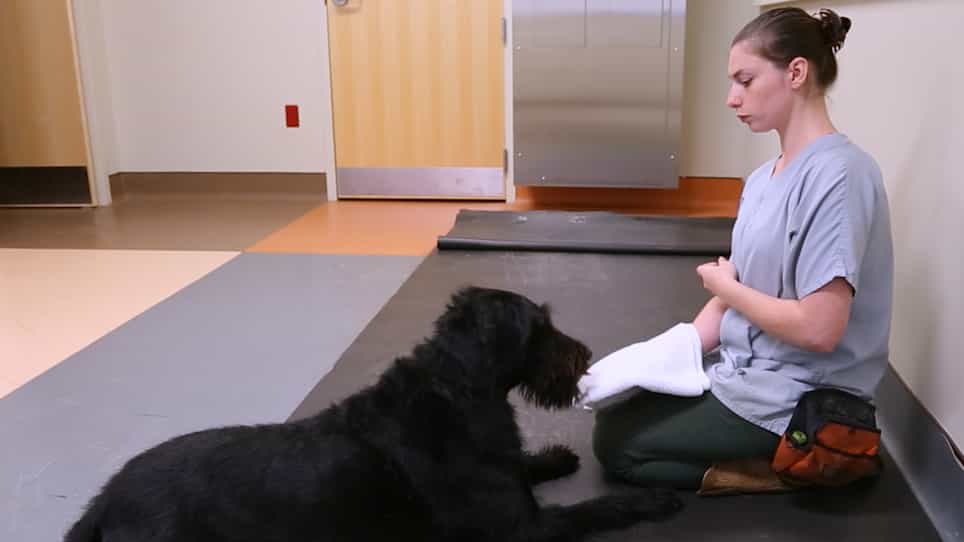

Training Dogs for Awake, Unrestrained Functional Magnetic Resonance Imaging
Published on: October 13, 2019
Sufficient is better than optimal for training neural networks
Irina Babayan1, Hazhir Aliahmadi1, Greg van Anders2
1Department of Physics, Engineering Physics, and Astronomy, Queen's University, Kingston ON, K7L 3N6, Canada.

Abstract:
The array of neural network training techniques that invoke optimization but rely on ad hoc modification for validity suggests that optimization-based training is misguided. Shortcomings of optimization-based training are brought to strong relief by overfitting, where naive optimization produces spurious outcomes. Here, we introduce simmering, a physics-based method that trains neural networks to generate "good enough" weights and biases, paradoxically outperforming leading optimization-based approaches. Instead of optimizing, simmering systematically samples non-optimal weights and biases to generate an ensemble that provides sufficient representations of the underlying phenomenon. Simmering corrects neural networks that are overfit by optimization, and produces more generalizable predictions if deployed from the outset compared to other overfitting mitigation methods. Our results question optimization as a paradigm for training transformers, and feedforward and convolutional neural networks. We leverage information-geometric arguments to point to the existence of classes of sufficient-training algorithms that do not take optimization as their starting point.
Related Concept Videos
 01:19
Survival Tree
Building a Survival Tree
Constructing a...
 01:01
Neuroplasticity
 01:29
Mechanistic Models: Compartment Models in Algorithms for Numerical Problem Solving
In individual population analyses, different algorithms are employed, such as Cauchy's method, which uses a...