Related Experiment Video
Updated: Jan 8, 2026
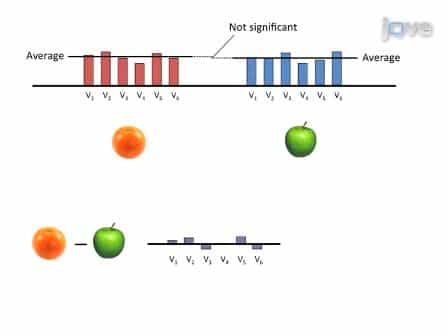

Cross-Modal Multivariate Pattern Analysis
Published on: November 9, 2011
Multimodal machine learning for video based single question mental health assessment
Bradley Grimm1, Pernille Yilmam2, Brett Talbot2
1Videra Health, Orem, UT, USA. brad@viderahealth.com.

Abstract:
This study demonstrates that a single video question can predict self-reported depression (PHQ-9), anxiety (GAD-7), and trauma (PCL-5) through text and voice analysis. As mental health screening needs increase, efficient multi-condition assessment methods could reduce patient burden in clinical settings. Our multimodal model, integrating MPNet for textual analysis and HuBERT for voice prosody, was trained on data from 2420 participants. Our approach achieves 64.6% reduced assessment time (78.4 s vs 221.7 s) while screening all three conditions from one response, with only 1.4% of participants unwilling to use video-based screening. Results demonstrate strong performance and demographic consistency across age, gender, and race/ethnicity supporting the feasibility of efficient multi-condition screening from brief video responses.
More Related Videos
 05:51
Exploring the Use of Isolated Expressions and Film Clips to Evaluate Emotion Recognition by People with Traumatic Brain Injury
Published on: May 15, 2016
 12:55
Multimodal Protocol for Assessing Metacognition and Self-Regulation in Adults with Learning Difficulties
Published on: September 27, 2020
