Related Experiment Video
Updated: Feb 6, 2026

Constructing and Visualizing Models using Mime-based Machine-learning Framework
Published on: July 22, 2025
A model-agnostic framework for dataset-specific selection of missing value imputation methods in pain-related
Jörn Lötsch1,2,3, Alfred Ultsch4
1Institute of Clinical Pharmacology, Goethe - University, Frankfurt am Main, Germany.

Abstract:
Missing value imputation is a routine step in biomedical data analysis, yet techniques are often not tailored to specific datasets. We propose a systematic framework for selecting imputation methods customized for the unique characteristics of cross-sectional numerical data, with a focus on pain-related biomedical research. This approach generates artificial "diagnostic" missing values by randomly removing entries, allowing for direct assessment of reconstruction accuracy across various algorithms. We introduce two novel classes of diagnostic reference methods: pseudo or "poisoned" imputation methods, which intentionally introduce bias into the imputation, and "calibrating" imputations, which inject controlled random noise for objective evaluation. The framework was tested on synthetic datasets and four biomedical datasets, primarily focusing on pain-related data, employing 29 different imputation methods. Quantitative outputs, including root median square deviation (RMSD), median difference (MD), relative bias, and method categorization, facilitate a comprehensive assessment of imputation quality. The framework consistently identifies the most suitable imputation technique for each dataset, revealing that multivariate methods generally outperform univariate approaches. Benchmarking against poisoned and calibrated references establishes quantifiable thresholds for acceptable imputation errors, while also identifying instances where reliable imputations are unattainable. This systematic framework offers practical and reproducible guidelines for imputing missing values in biomedical contexts, particularly in pain research. By empowering researchers to make informed decisions about imputation, the framework enhances data integrity and the robustness of subsequent analyses. Its model-agnostic nature allows for the integration of various imputation methods, with an automated implementation available in the open-source R package "opImputation."
Related Concept Videos
 00:59
How Data are Classified: Numerical Data
Quantitative data may be either discrete or continuous. All quantitative data that take on only specific numerical...
 01:25
Selected Data About Geographic Locations
 01:25
Dose-Response Relationship: Selectivity and Specificity
 01:29
Mechanistic Models: Compartment Models in Algorithms for Numerical Problem Solving
In individual population analyses, different algorithms are employed, such as Cauchy's method, which uses a...
 01:14
Analysis Methods of Pharmacokinetic Data: Model and Model-Independent Approaches
The model approach uses mathematical models to describe changes in drug concentration over time. Pharmacokinetic models help characterize drug behavior in patients, predict drug concentration in the body fluids, calculate optimum dosage regimens, and evaluate the risk of toxicity. However, ensuring that the model fits the experimental data accurately...
 01:24
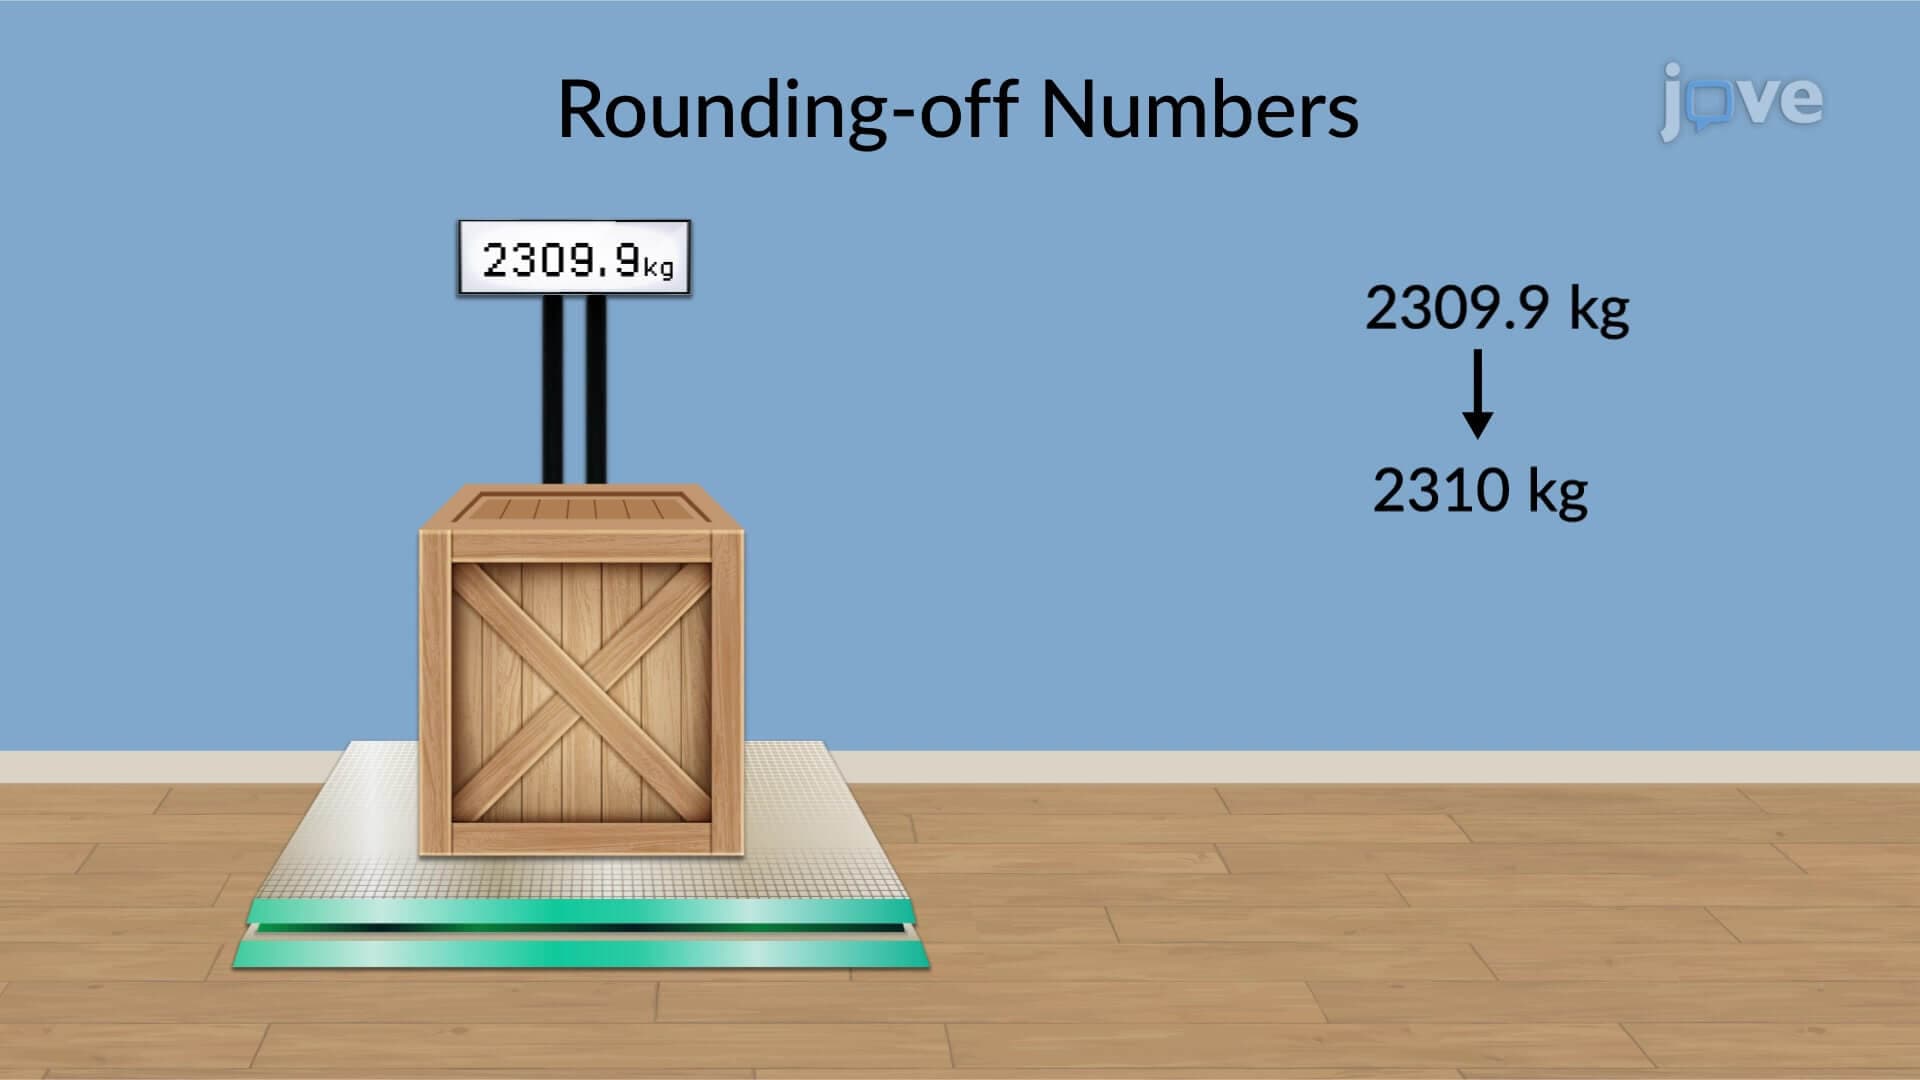
Numerical Calculations
The solution to a problem is obtained using different methods. While manually solving algebraic symbols is one of the most common methods, the graphical method is often preferred. Computers...