Related Experiment Video
Updated: Mar 7, 2026
Inverse Probability of Treatment Weighting Propensity Score using the Military Health System Data Repository and National Death Index
Published on: January 8, 2020
Exploring the validity of using the English index of Multiple Deprivation as a proxy for individual or household
1Centre for Population Health Research, University of Edinburgh, Edinburgh, UK.

Objectives:
To explore the validity of using the English Index of Multiple Deprivation (IMD) as a proxy for individual or household income; for total IMD and subdomains, and for different individual and household types.
Study Design:
Cross-sectional analysis of survey and administrative data.
Methods:
Income and contextual data were obtained from the Understanding Society survey, alongside the Lower Super Output Area (LSOA) of residence to enable linkage to the 2019 English IMD. The relationship between income and IMD (including subdomains) was explored using descriptive analysis and univariable linear regression models. Multivariable regression models were then employed to determine the relationship between income and IMD for different individual and household characteristics.
Results:
Greater levels of income heterogeneity were observed in the least deprived LSOAs. R-squared values from univariable models suggest that around five percent of the variation in household income and around one percent of individual income can be attributed to IMD. Also, IMD was a particularly poor predictor of income for certain groups: young people under 25, females, those not in good health, White British individuals, single person households without children, and households in social rented accommodation.
Conclusions:
IMD is a poor proxy for individual or household level income, particularly for some population subgroups. Using IMD as a proxy potentially introduces large amounts of measurement error. IMD should be treated as an area level measure, both conceptually and statistically. Some IMD subdomains may be more useful for certain studies.
More Related Videos
Related Concept Videos
 01:08
Outliers and Influential Points
 02:16
Measures of Central Tendency
 01:06
Skewness
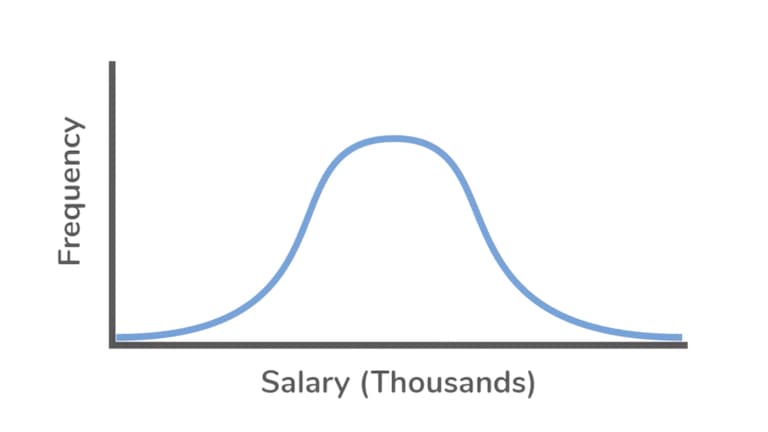
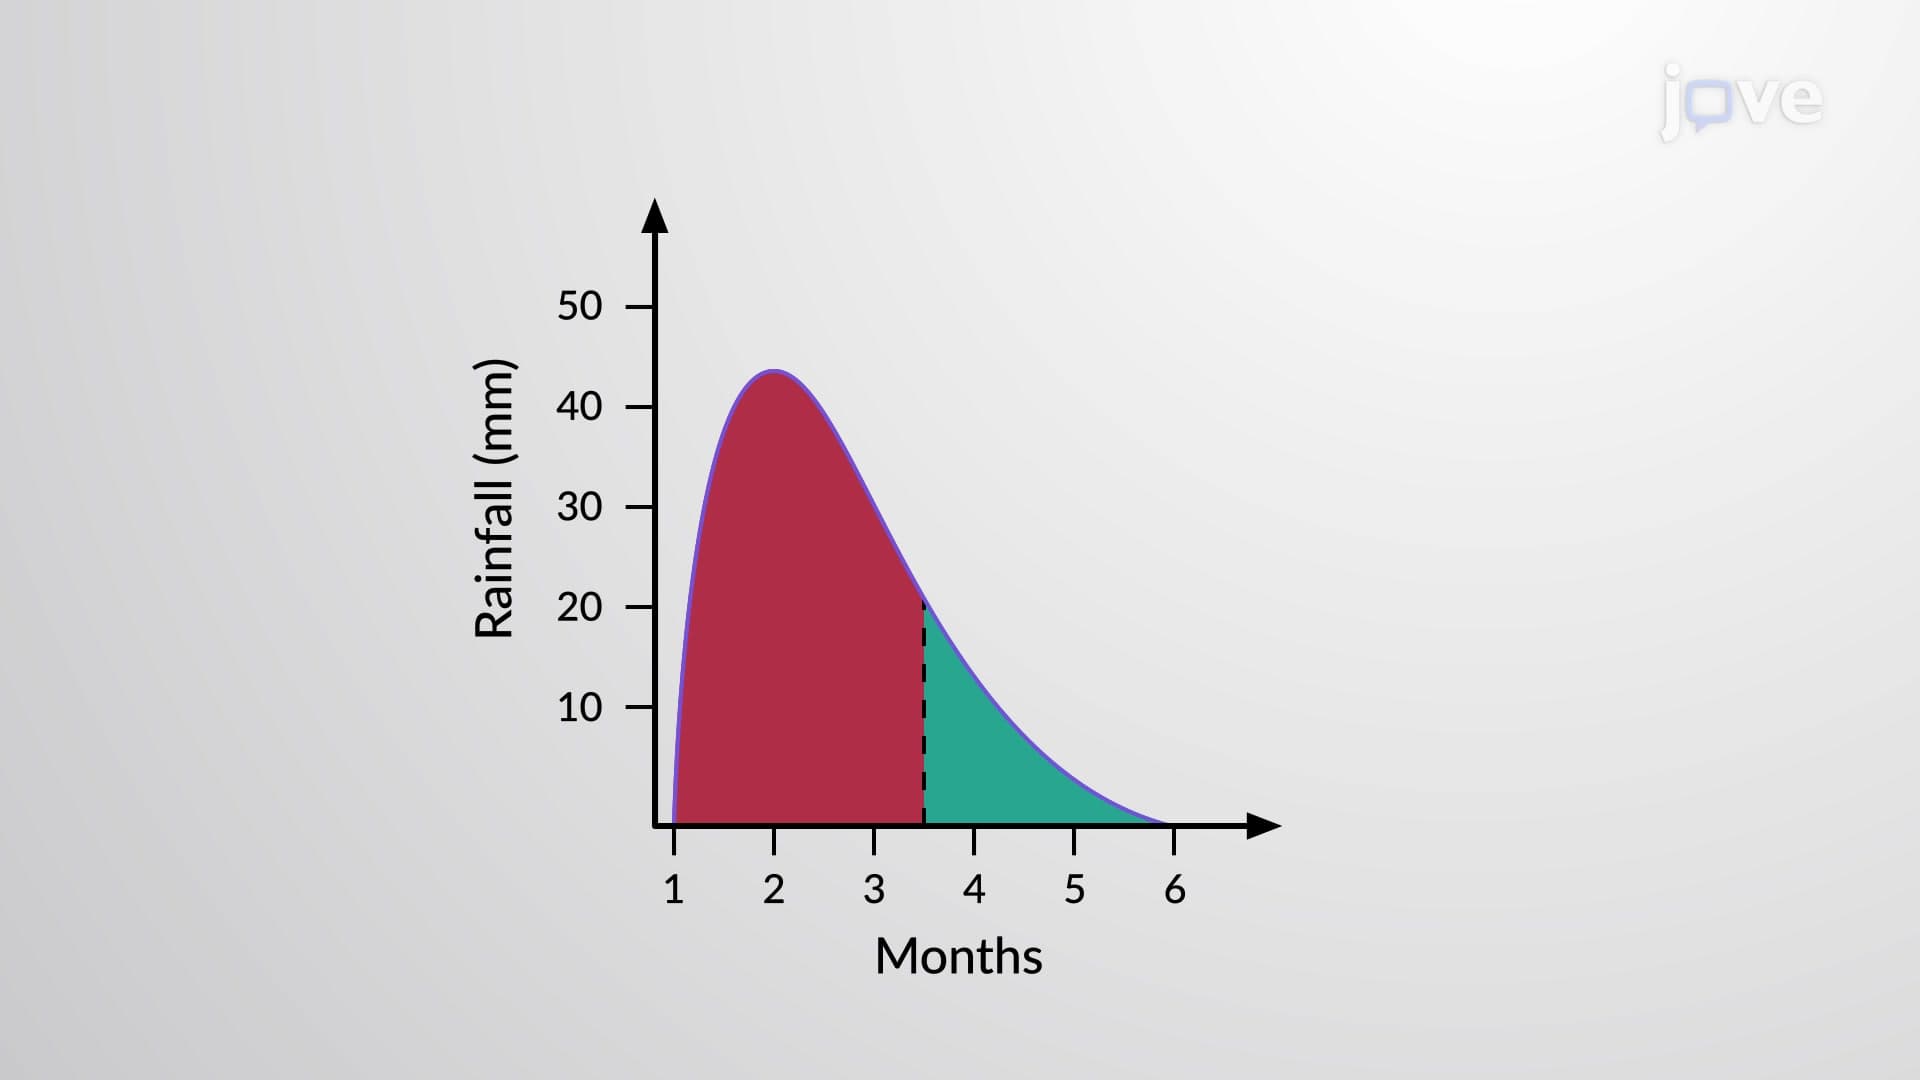
The longer the tail of the plot on one side, the more skewed it is. The skewness of a data set’s values suggests that the measures of central tendency...
 01:14
Wilcoxon Signed-Ranks Test for Median of Single Population
 01:21
Friedman Two-way Analysis of Variance by Ranks
 01:29
Bias in Epidemiological Studies