Related Experiment Video
Updated: Jun 7, 2026


Selecting Multiple Biomarker Subsets with Similarly Effective Binary Classification Performances
Published on: October 11, 2018
Selecting and Distilling Cross-Label Models

Abstract:
The practice of knowledge distillation, wherein pre-trained models - termed "teachers" - serve to enhance the performance of subsequent "student" models, has seen a surge in popularity. With a lot of pre-trained models available, there is a pressing need to investigate effective mechanisms for utilizing these resources optimally. This paper tackles two main challenges inherent in developing such mechanisms. The initial challenge lies in the effective selection of the most advantageous models from a vast pool, given that exhaustively testing each pre-trained model is impractical. The second challenge stems from the diversity of pre-trained models, as it is common for a pre-trained model to have a different label space than that of the current task. This necessitates the development of a universal model reuse approach capable of integrating any pre-trained model, regardless of its unknown label set. To address these issues, we introduce a dual-phase framework named "Selective Cross-Label Distillation." The first phase, termed model assessment, evaluates the semantic similarity between a potential pre-trained model and the target model through optimal transport. By determining the transportation cost, we pinpoint candidate models with lower costs to serve as our source models. The second phase, knowledge reuse, concentrates on minimizing the transportation cost between the chosen source models and the target model. This dual-phase approach enables efficient model selection and bridges the semantic gap between pre-trained models and the target task, leading to enhanced performance. The effectiveness of our framework in model selection and knowledge reuse is validated by experimental results.
Related Concept Videos
 01:26
Pharmacokinetic Models: Comparison and Selection Criterion
Physiological models take a detailed approach by considering specific molecular processes. They can predict drug distribution, metabolism, and elimination changes, providing a comprehensive understanding of how drugs interact with the body.
 01:17
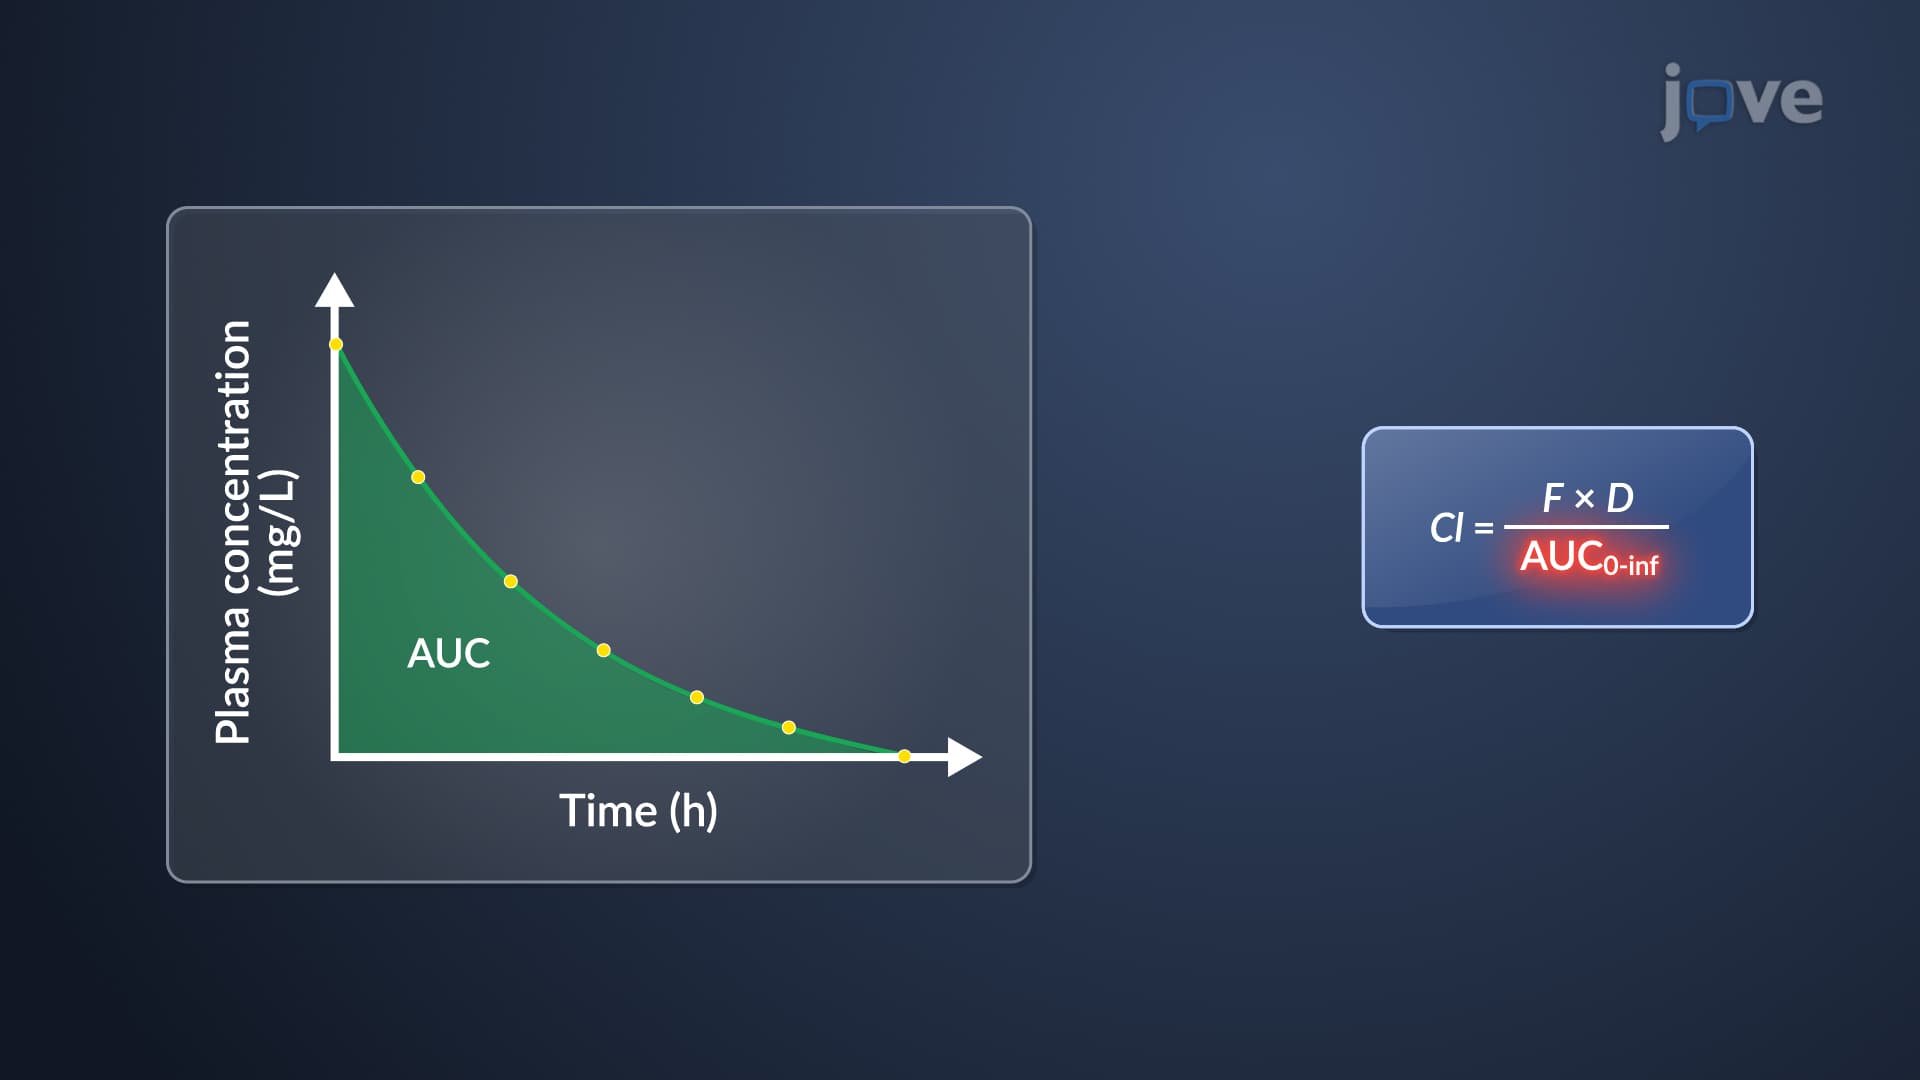
Clearance Models: Noncompartmental Models
The noncompartmental approach capitalizes on extensive sampling data, correlating the volume of distribution to systemic exposure and the administered dosage. This method enables...
 01:28
Methods of Medium Optimization
 01:23
Mechanistic Models: Compartment Models in Individual and Population Analysis
 01:16
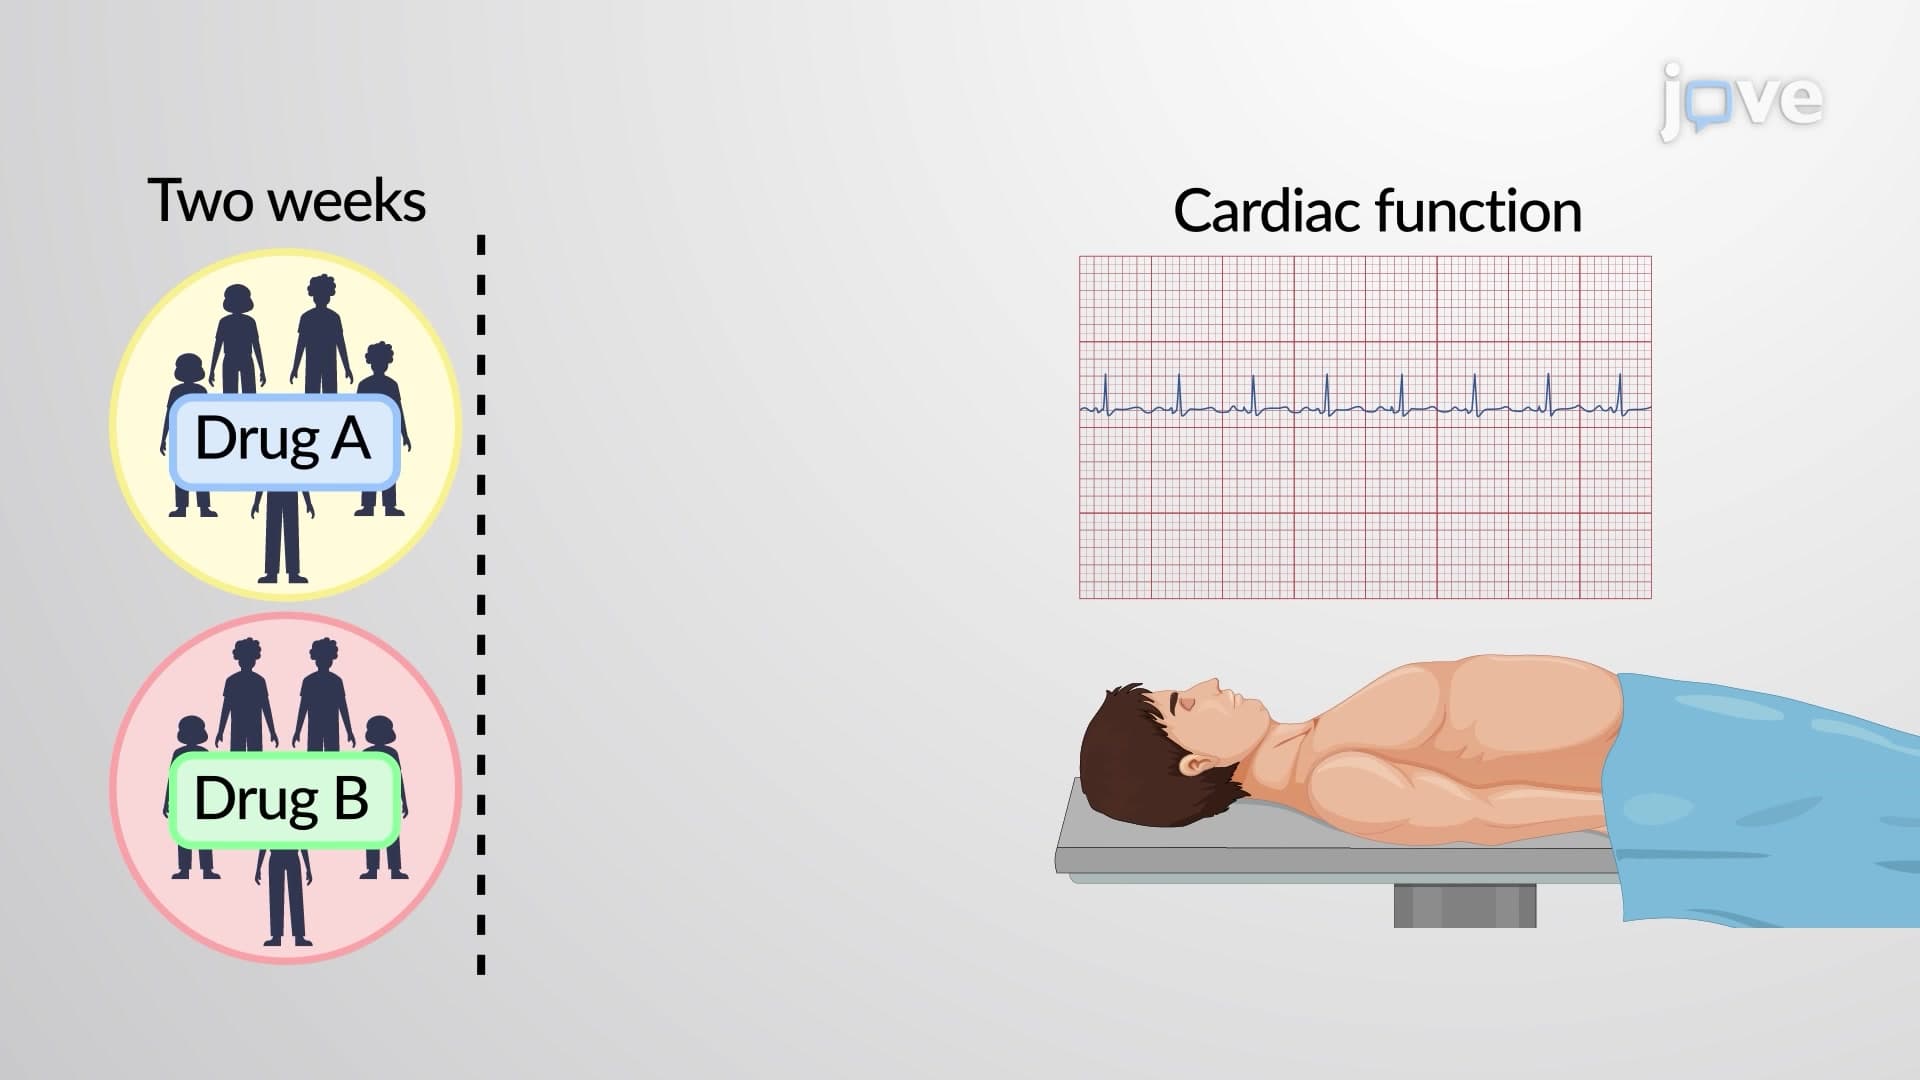
Crossover Experiments
Crossover designs are performed even with smaller sample sizes since the samples can act as their controls. These are better than simple randomized trials since patients are exposed to all the treatments.
 01:15
Bioequivalence Experimental Study Designs: Repeated Measures, Cross-Over, Carry-Over, and Latin Square Designs