Related Experiment Video
Updated: Jun 24, 2026
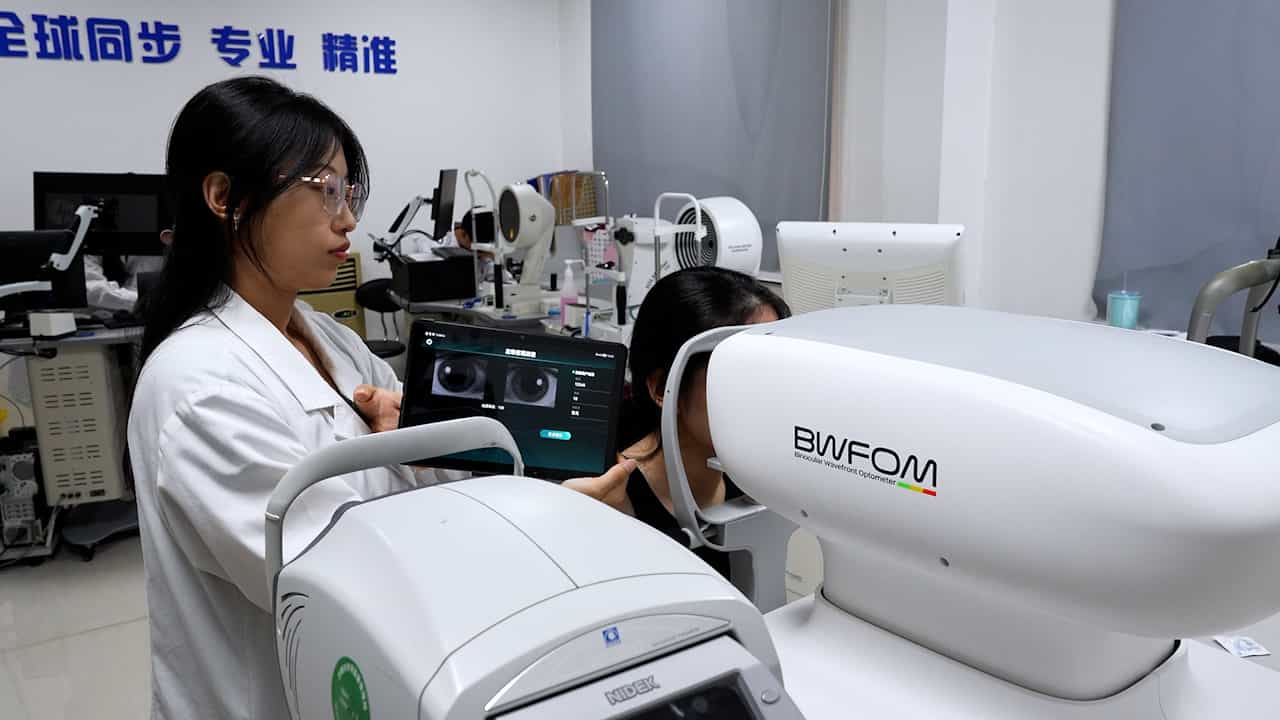

Comparison of Agreement and Accuracy using Binocular Wavefront Optometer with Autorefractor and Phoropter
Published on: September 16, 2025
Comparative analysis of GPT-4o as a representative multimodal large language model and human fitters in
Daohuan Kang1, Lu Yuan1, Jia Feng1
1Department of Ophthalmology, Children's Hospital, Zhejiang University School of Medicine, National Clinical Research Center for Children and Adolescents' Health and Diseases, Hangzhou, Zhejiang, China.

Objective:
To compare the performance of GPT-4o, used here as a representative multimodal large language model (MLLM), against human fitters in orthokeratology (OK) lens fitting, with a focus on retrospective parameter-matching accuracy, efficiency and cost-effectiveness in initial lens parameter selection.
Methods:
A total of 70 OK lens fittings were analysed. GPT-4o and human fitters provided recommendations for trial lens parameters based on patient data. The recommendations were compared with the final fitting parameters to assess accuracy. Additionally, the fitting time and costs for each fitter were recorded. Statistical methods were applied to compare GPT-4o's performance with human fitters.
Results:
GPT-4o achieved 78% accuracy (196/250), comparable to human fitters (experienced ophthalmologist: 83%, optometrists: 85%, general ophthalmologists: 76%). It showed similar precision in key parameters like base curve (BC), reduction, diameter and cylinder power (CP). Interrater reliability between GPT-4o and human fitters ranged from slight to moderate (κ = 0.18-0.60). GPT-4o was more efficient, taking only 11.60 s per case compared to an average of 85.35 s for humans, and reduced costs to $0.03 per case versus $0.33 for Chinese human fitters (p < 0.001).
Conclusion:
In this single-model retrospective study, GPT-4o, evaluated as a representative MLLM, achieved parameter-matching accuracy broadly comparable to that of human fitters while substantially reducing processing time and costs. However, given the slight-to-moderate interrater reliability, retrospective design and absence of external validation, these findings should be interpreted as supporting a preliminary decision-support role rather than autonomous clinical implementation.