Related Experiment Video
Updated: Jun 28, 2026

Photorealistic Learned Landscapes for Augmented Reality
Published on: June 27, 2025
Spectral super-resolution for Parkinson's voice via representation-level methods under mixed-reality acquisition
Milosz Dudek1, Jakub Sikora2, Justyna Krzywdziak2
1Faculty of Electrical Engineering, Automatics, Computer Science and Biomedical Engineering, AGH University of Krakow, al. Mickiewicza 30, Krakow, 30-059, Poland; SoftServe, Poland.

Background And Objectives:
Voice is a practical remote biomarker for Parkinson's disease (PD), but real-world capture often yields low-resolution time-frequency inputs that under-resolve diagnostically salient microstructure. In this controlled empirical comparison, we test whether spectrogram super-resolution (SR) at the feature level performed inside the model rather than via waveform resynthesis improves PD vs. healthy control (HC) discrimination under realistic constraints.
Methods:
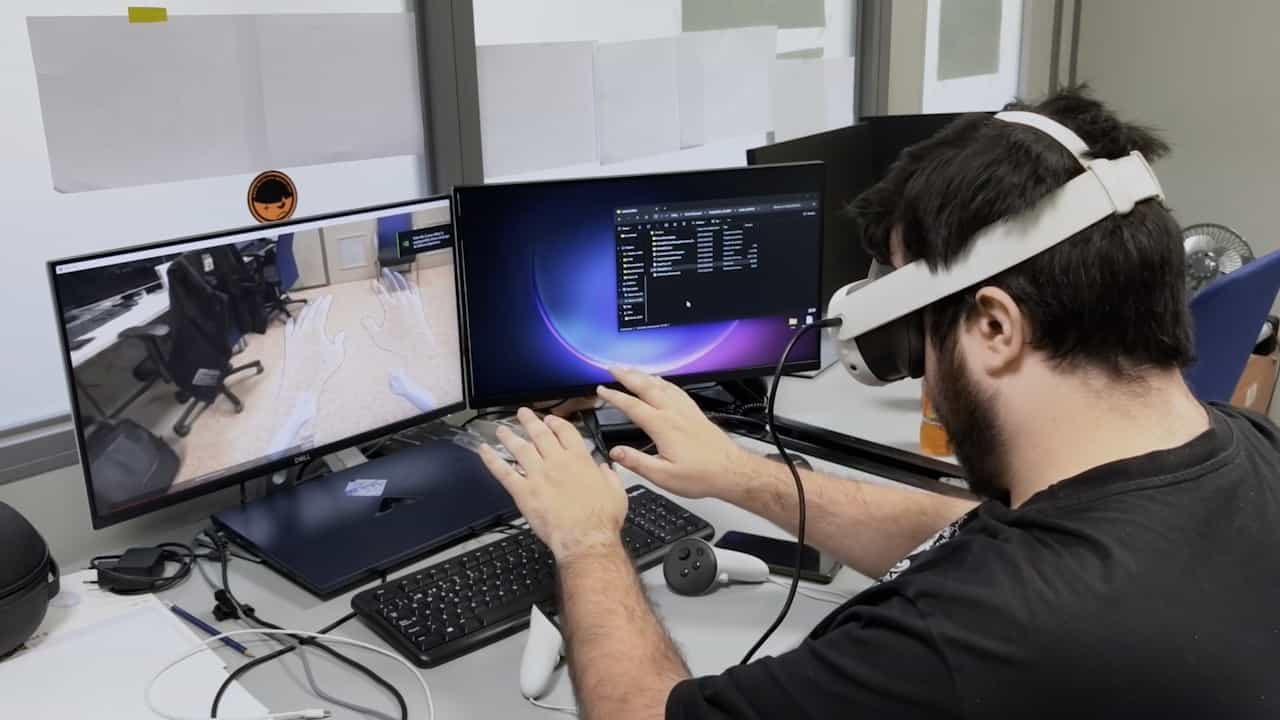
Speech was recorded with a Microsoft HoloLens 2 using a standardized mixed-reality (MR) protocol from 161 speakers (75 PD/86 HC) across five tasks: Task 1 image description, Task 2 question answering, Task 3 story repetition, Task 4 sustained vowels, and Task 5 word repetition (DDK). Raw audio was exported as 48 kHz, 16-bit PCM, downmixed to mono, amplitude-normalized, conservatively trimmed for leading/trailing silence, and resampled to 16 kHz. Log-mel spectrograms (80 bins) were fed to practical ImageNet-pretrained backbones (ConvNeXt-Tiny, ResNet-50, EfficientNetV2-S). We compared six super-resolution (SR) strategies: identity, nearest (deterministic), bilinear SR, kernel/CARAFE-like SR, LIIF-like SR, and a frozen universal feature SR module (AnyUp) that upsamples intermediate feature maps. Evaluation used 5-fold, speaker-disjoint cross-validation with AUROC (AUC) and accuracy (ACC).
Results:
AnyUp was the most consistent top performer, ranking first in 11/15 backbone-task cells. Gains were largest on tasks dominated by fine spectro-temporal cues: for ConvNeXt-Tiny, AnyUp vs. identity improved sustained vowels (Task 4) by ΔAUC 0.030/ΔACC 0.070 and DDK (Task 5) by ΔAUC 0.054/ΔACC 0.045. Macro-averaged over tasks, AnyUp outperformed identity by +0.025 AUC/+0.045 ACC (ConvNeXt-Tiny), +0.015/+0.027 (ResNet-50), and +0.052/+0.048 (EfficientNetV2-S). Representative best-in-class results include AUC/ACC of 0.899/0.886 (Task 4) and 0.927/0.897 (Task 5) for ConvNeXt-Tiny+AnyUp, and 0.940/0.903 (Task 5) for ResNet-50+AnyUp.
Conclusions:
Densifying spectrogram representations with a frozen, universal feature super-resolution module yields consistent, compute-efficient improvements in PD voice classification under MR-standardized acquisition, with the largest benefits on sustained vowels and DDK. The contribution is empirical rather than architectural: we compare practical representation-level SR choices rather than introduce a new SR module. Feature-level super-resolution is therefore a pragmatic alternative or complement to bandwidth extension when waveform synthesis is unnecessary. At a macro level, the observed accuracy gains (e.g., +0.045 for ConvNeXt-Tiny) suggest that representation-level SR may be operationally useful in low-resolution clinical-audio settings.
Related Concept Videos
 01:12
Double Resonance Techniques: Overview
Spin decoupling is usually achieved by...
 01:21
Perceiving Loudness, Pitch, and Location
Place theory, or place coding, suggests that different pitches are heard because various sound waves activate specific locations along the cochlea's basilar membrane. The brain determines the pitch of a sound by identifying...