Related Experiment Video
Updated: Aug 12, 2026
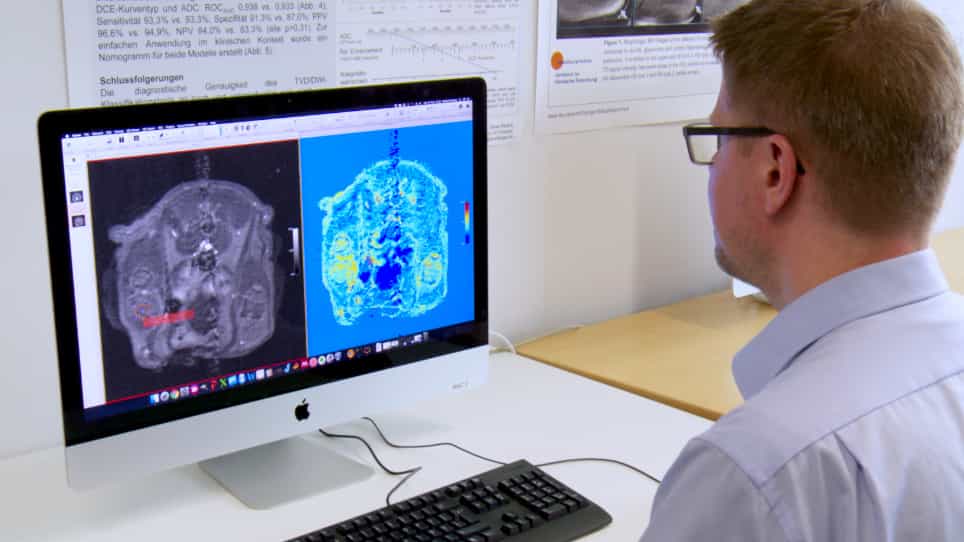

Machine Learning Algorithms for Early Detection of Bone Metastases in an Experimental Rat Model
Published on: August 16, 2020
Data Extraction From Oncology Imaging Reports by Large Language Models: A Comparative Accuracy Study
Lea P Passweg1, Johannes M Schwenke2, Christof M Schönenberger2
1Division of Medical Oncology, University and University Hospital Basel, Basel, Switzerland.

Purpose:
Manual data extraction from clinical text is resource-intensive. Locally hosted large language models (LLMs) may offer a privacy-preserving solution, but their performance on non-English data remains unclear. We investigated whether the accuracy of locally hosted LLMs is noninferior to human accuracy when determining metastasis status and treatment response from German radiology reports.
Methods:
In this retrospective comparative accuracy study, five locally hosted LLMs (llama3.3:70b, mistral-small:24b, qwq:32b, qwen3:32b, and gpt-oss:120b) were compared against humans. A ground truth was established via duplicate human extraction and adjudication of discrepancies by a senior oncologist. The study was conducted at a tertiary referral hospital in Switzerland. We randomly sampled 400 radiology reports from adult patients with cancer (computed tomography, magnetic resonance imaging, positron emission tomography) generated between January 2023 and May 2025 and split them into a prompt optimization set (n = 100) and test set (n = 300). Primary outcomes were noninferiority (5 percentage points [pp] margin) of LLM classification accuracy compared with human accuracy for metastasis status (presence/absence by anatomic site) and treatment response categories. Secondary outcomes included accuracy for primary tumor diagnosis and radiologic absence of tumor.
Results:
The analysis included 400 reports from 317 patients. In the test set (n = 300), the human accuracy for metastasis status was 98.4% (95% CI, 98.0 to 98.8). All LLMs were noninferior; gpt-oss:120b performed best (97.6% accuracy; difference, -0.8 pp [90% CI, -1.3 to -0.3 pp]). For response to treatment, the human accuracy was 86.0% (95% CI, 83.2 to 88.8). All LLMs were inferior; the most accurate model, gpt-oss:120b, achieved 78.3% (difference, -7.7 pp [90% CI, -11.6 to -3.8 pp]).
Conclusion:
In this study, LLMs were noninferior to human accuracy for classification of metastasis status but were inferior for response to treatment assessment.
