Related Experiment Video
Updated: Aug 14, 2026
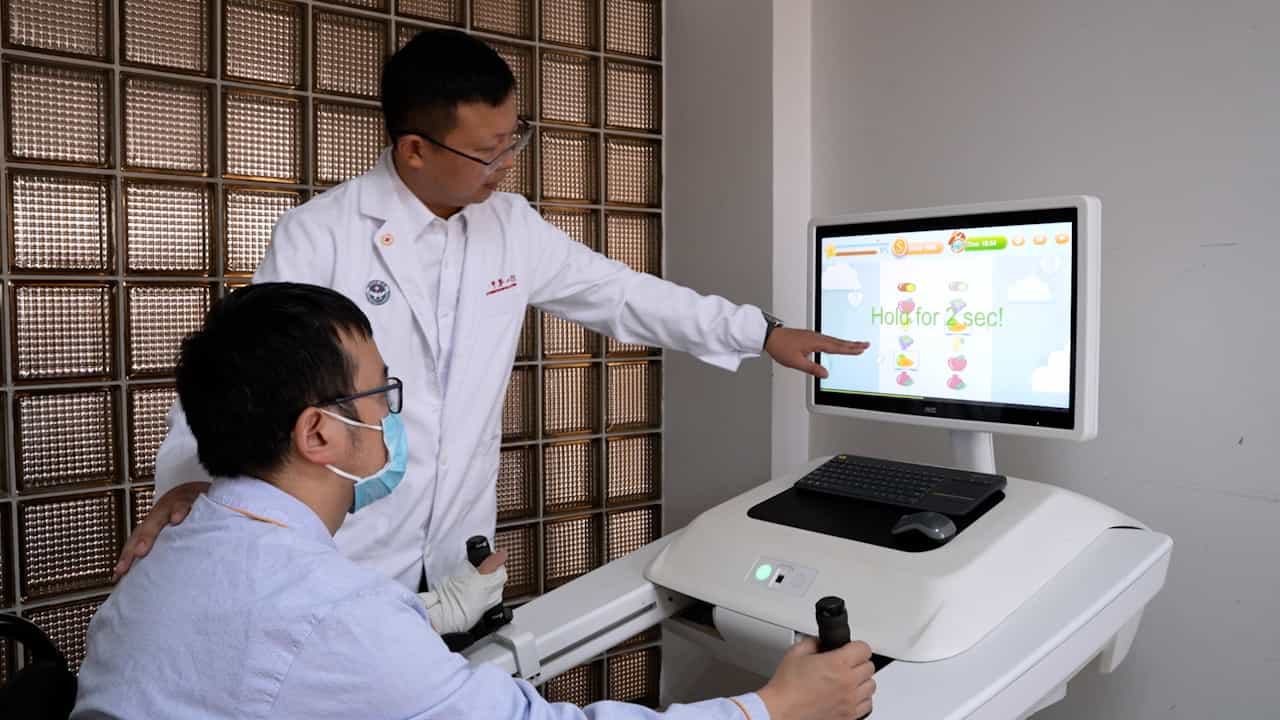

Application of a Dual Upper Limb Task-Oriented Robotic System for the Functional Recovery of the Upper Limb in Stroke Patients
Published on: October 11, 2024
Language-Guided Dual-Mode Policy for Dual-Arm Manipulation
Jianghao Sun1, Pengjun Mao1, Yu Wang1
1School of Mechanical and Electrical Engineering, Henan University of Science and Technology, Luoyang 471000, China.

Abstract:
Dual-arm robot manipulation tasks are highly complex, and different tasks can be categorized as dual-arm synchronous coordination or asynchronous sequential execution. Existing action-generative policies adopt a fully parameter-sharing single-network architecture in multi-task learning, overlooking the differences between these two task types in terms of temporal dependencies and action distributions, which leads to cross-mode interference. To address this limitation, we propose LGDM (Language-Guided Dual-Mode Policy), a language-guided dual-mode policy framework. Under shared language embeddings, it parallelly constructs dual-conditional branches for language routing and visual perception. The execution layer selects independent synchronous or asynchronous policy branches according to routing signals and outputs actions by combining them with perceptual features, thereby explicitly decoupling the two motion modes. Specifically, the model organizes three functional modules around language embeddings as a hub: (1) a language mode routing layer that predicts motion modes from temporal information in semantics and provides mode-selection signals to the execution layer; (2) a vision perception layer that injects semantic information into the visual backbone via FiLM, enabling task-aware dynamic feature modulation; and (3) a dual-mode execution layer that builds independent synchronous and asynchronous policy branches, selects the corresponding branch according to routing, and generates actions with the modulated features. On the RoboTwin 2 dual-arm manipulation benchmark comprising six synchronous and asynchronous tasks, LGDM outperforms existing baselines, achieving an absolute improvement of 14.5 percentage points over RDT, and maintains robust execution performance under unseen temporal-coordination instruction variants at inference time.

