Related Experiment Video
Updated: Sep 16, 2026
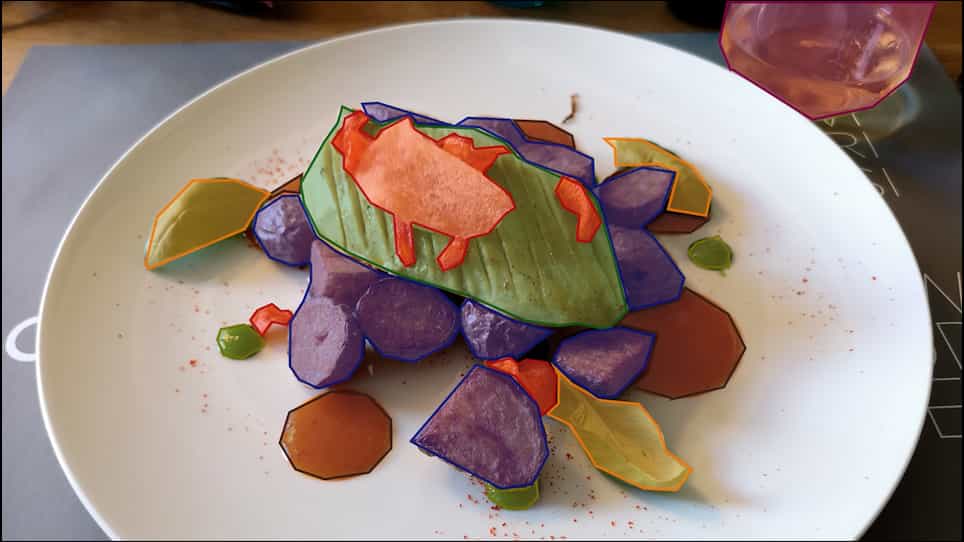

Deep Neural Networks for Image-Based Dietary Assessment
Published on: March 13, 2021
Food Intelligent Quality and Safety Analysis: From Data-Driven to Data-Mechanism Hybrid-Driven Paradigm
Zheng-Yong Zhang1,2, Rui Zhang1, Wen-Qi Yan1
1School of Management Science and Engineering, Nanjing University of Finance and Economics, Nanjing 210023, China.

Abstract:
In recent years, numerous studies have reported on intelligent analytical applications for food quality and safety. To identify the underlying patterns and development trends in this field, this paper presents a comprehensive review from the perspectives of both data-driven and mechanism-driven paradigms. Under the data-driven paradigm, detection modalities may involve either single-modal or multimodal approaches. By integrating measured detection data with appropriate intelligent learning algorithms, specific tasks for food quality or safety assessment can be achieved. Research efforts in this area encompass the development of detection techniques, optimization of measurement parameters, construction of high-dimensional spectral features, design of feature extraction methods, selection and tuning of algorithms, and formulation of multimodal data fusion strategies. This paradigm is characterized by high computational speed and superior prediction or classification efficiency. Nevertheless, it is constrained by several limitations, including poor model interpretability, limited extrapolation and generalization capabilities, and a heavy reliance on high-quality annotated data. In contrast, the data-mechanism hybrid-driven paradigm integrates physical laws and other prior knowledge as constraints that are deeply embedded into neural network training. By combining data-driven mining capabilities with theoretical prior knowledge, this approach achieves improved predictive performance and decision-making reliability. This paradigm offers notable advantages, such as enhanced interpretability, greater trustworthiness, improved data efficiency, and reduced computational costs. It is particularly well-suited for small-sample or data-sparse scenarios, and thus represents a promising and important direction for future research in this domain.