Related Experiment Video
Updated: Sep 19, 2026
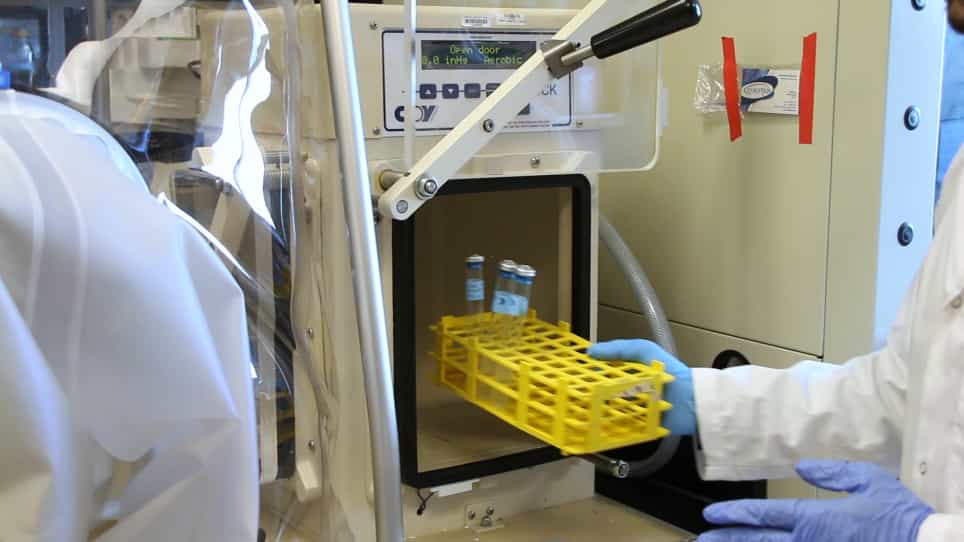

An Anaerobic Biosensor Assay for the Detection of Mercury and Cadmium
Published on: December 17, 2018
Benchmarking Statistical Methods for Environmental Chemical Mixtures: Prediction, Interaction Detection, and an
Aderonke Gbemi Adetunji1,2, Emmanuel Obeng-Gyasi1,2
1Department of Built Environment, North Carolina A&T State University, Greensboro, NC 27411, USA.

Background:
Human populations are exposed to complex chemical mixtures, making interaction detection a central challenge in environmental epidemiology. We benchmarked methods for prediction and recovery of interaction structure.
Methods:
Eight approaches-main-effects Lasso (glmnet_main), interaction Lasso (glmnet_int), hierNet, Random Forests, Bayesian Kernel Machine Regression (BKMR), quantile g-computation (qgcomp), weighted quantile sum regression (gWQS) and SuperLearner-were evaluated across eight linear/nonlinear, additive/interaction, continuous/binary data-generating processes (500 replicates each). Every method completed in all 500 replicates of all eight scenarios. Prediction was assessed on held-out test data using observed-outcome and oracle-referenced metrics; interaction detection was assessed against three known pairwise interactions among 45 candidate pairs, using both hard selection and a threshold-free ranking criterion. BKMR was evaluated at 2000 versus 25,000 MCMC iterations with multi-chain convergence diagnostics. Sensitivity analyses varied sample size, exposure correlation, signal strength, and interaction form. BKMR was also applied illustratively to six metals and prevalent diabetes in NHANES.
Results:
In additive settings, observed-outcome prediction was similar across methods, but oracle-referenced continuous-outcome error differed by up to six-fold. With interactions, interaction-aware methods clearly outperformed additive-only approaches on the continuous oracle-referenced metrics: in LMI, the oracle MSE was 1.57 for hierNet and 1.87 for glmnet_int against 3.80 for glmnet_main and 4.94 for qgcomp. glmnet_int and hierNet showed comparable sensitivity; hierNet had a modestly lower mean per-replicate false discovery proportion in paired comparisons, while pooled false discovery favored hierNet in the continuous scenarios and glmnet_int in the binary ones; pooled false discovery rates were 0.79 to 0.82 in every interaction scenario, so roughly four in five selected pairs were false. In the scenarios without true interactions, the pooled false discovery rate was exactly 1. Under threshold-free ranking, BKMR was competitive with the penalized methods (pair-ranking AUC: 0.758 to 0.781 across the four interaction scenarios). BKMR's apparent instability at 2000 iterations reflected inadequate sampling: 93% of monitored parameters had a Gelman-Rubin statistic above 1.1 and the minimum effective sample size was 7.5, whereas at 25,000 iterations the median statistic was 1.02 and the oracle MSE in LMI fell from 6.38 to 2.08. In NHANES, lead, manganese, and iron had the highest posterior inclusion probabilities, with predominantly nonlinear exposure-response functions.
Conclusions:
Method choice matters most when interactions are present. Interaction-aware methods are preferable when joint effects are relevant, selected interactions require replication given the high false discovery burden, and BKMR comparisons should report sampling budgets and convergence diagnostics rather than treating a short chain as characteristic of the method.
Related Concept Videos
 01:23
Sampling Plans
Random sampling is a method where each member of the population has an equal chance of being selected for the sample. It involves selecting individuals randomly, often using random number generators or lottery-type methods. For example, when analyzing the properties of a...
 01:25
Statistical Methods for Analyzing Epidemiological Data