Related Experiment Video
Updated: Sep 19, 2026

Xenopus laevis as a Model to Identify Translation Impairment
Published on: September 27, 2015
A trainable language model with potential to modulate translation rates in non-model organisms by generating upstream
Alexander D Duggan1,2, Matthew P Newman1,3, David R McMillen1,2,3
1Department of Chemical and Physical Sciences, University of Toronto Mississauga, Mississauga, Ontario, Canada.

Abstract:
Tuning protein expression in non-model organisms is often constrained by the lack of validated genetic parts and predictive design tools. Translational tuning through the modulation of upstream untranslated regions (5'-UTRs) offers a potentially organism-agnostic route, but existing methods typically rely on mechanistic assumptions, prior knowledge that may not be available in non-model contexts, or the screening of sequence libraries. Here, we present a simple generative approach for creating synthetic 5'-UTR libraries based solely on the genomic sequence statistics of any desired organism. The method uses a sliding-window n-gram language model applied to native 5'-UTR sequences to produce novel sequences that preserve organism-specific base distributions and motifs without hard-coding specific motifs or mechanistic rules into inflexible statistical templates. We have applied this approach to the model bacterium Escherichia coli and the non-model probiotic Limosilactobacillus reuteri. Libraries of approximately 1,000 sequences were generated for each organism, from which about 100 unique sequences were experimentally tested for translation of a fluorescent reporter protein. In both organisms, the synthetic libraries yielded a broad range of translation levels from this relatively small number of tested variants. Sequences derived from an organism's own genomic statistics provided a more uniformly distributed range of translation rates in that organism than sequences derived from the other species. Correlations of individual sequence performance across the two species were weak, and thermodynamic predictions of ribosome binding strength showed very little predictive power, especially in the non-model L. reuteri. The results demonstrate that simple statistical language model approaches applied to genomic data can generate functional translational regulatory sequence libraries without detailed mechanistic knowledge or explicit reference to consensus motifs. The approach requires minimal computational resources, avoids reproducing native sequences, and can be readily applied to any organism with a sequenced genome. This strategy may lower technical barriers to expression tuning in non-model organisms.
Related Concept Videos
 02:28
Leaky Scanning
 02:33
Initiation of Translation
First, the initiator tRNA must be selected from the pool of elongator tRNAs by eukaryotic initiation factor 2 (eIF2). The initiator tRNA (Met-tRNAi) has conserved sequence elements including modified bases at...
 01:29
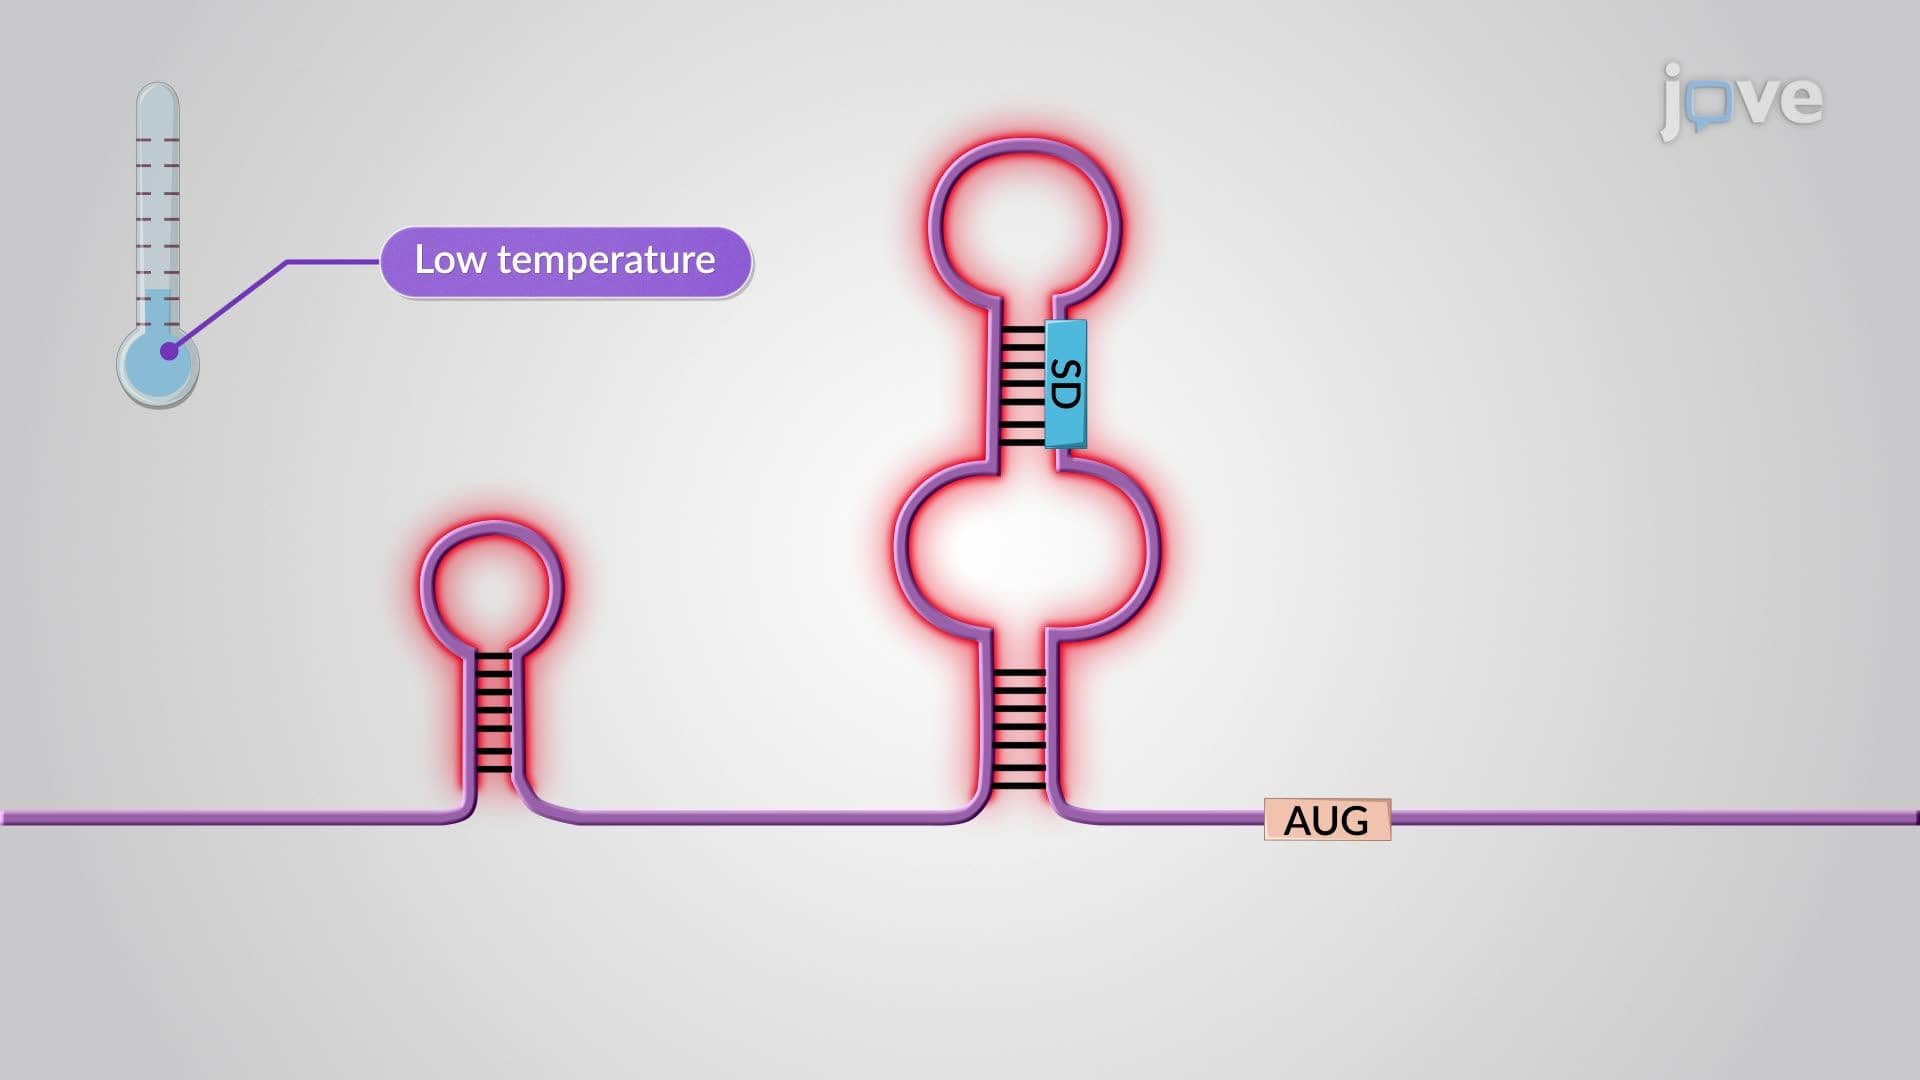
Translational Regulation
 02:24
Ribosome Profiling
Applications of ribosome profiling
Ribosome profiling has many applications, including in vivo monitoring of translation inside a particular organ or tissue type and quantifying new protein synthesis levels.
The technique helps...
 01:29
Translation in Prokaryotes
 01:23
Regulation of Expression at Multiple Steps