Related Experiment Video
Updated: Sep 19, 2026


Selecting Multiple Biomarker Subsets with Similarly Effective Binary Classification Performances
Published on: October 11, 2018
Partial VOROS: A Cost-aware Performance Metric for Binary Classifiers with Precision and Capacity Constraints
Christopher Ratigan1, Kyle Heuton2, Carissa Wang2
1Department of Mathematics, Tufts University, Medford, MA, USA.

Abstract:
The ROC curve is widely used to assess binary classifiers. Yet for some applications, such as alert systems for monitoring hospitalized patients, conventional ROC analysis cannot meet two key deployment needs: enforcing a constraint on precision to avoid false alarm fatigue and imposing an upper bound on the number of predicted positives to represent the capacity of hospital staff. The usual area under the curve metric also does not reflect asymmetric costs for false positives and false negatives. In this paper we address all three of these issues. First, we show how the subset of classifiers that meet precision and capacity constraints occupy a feasible region in ROC space. We establish the polygonshaped geometry of this region. We then define the partial area of lesser classifiers, a performance metric that is monotonic with cost and only accounts for the feasible region. Averaging this area over a desired distribution for cost parameters results in the partial volume over the ROC surface, or partial VOROS. In experiments predicting mortality risk from vital sign history on several datasets, we show this cost-aware metric can outperform alternatives at ranking classifiers for in-hospital alerts.
Related Concept Videos
 01:52
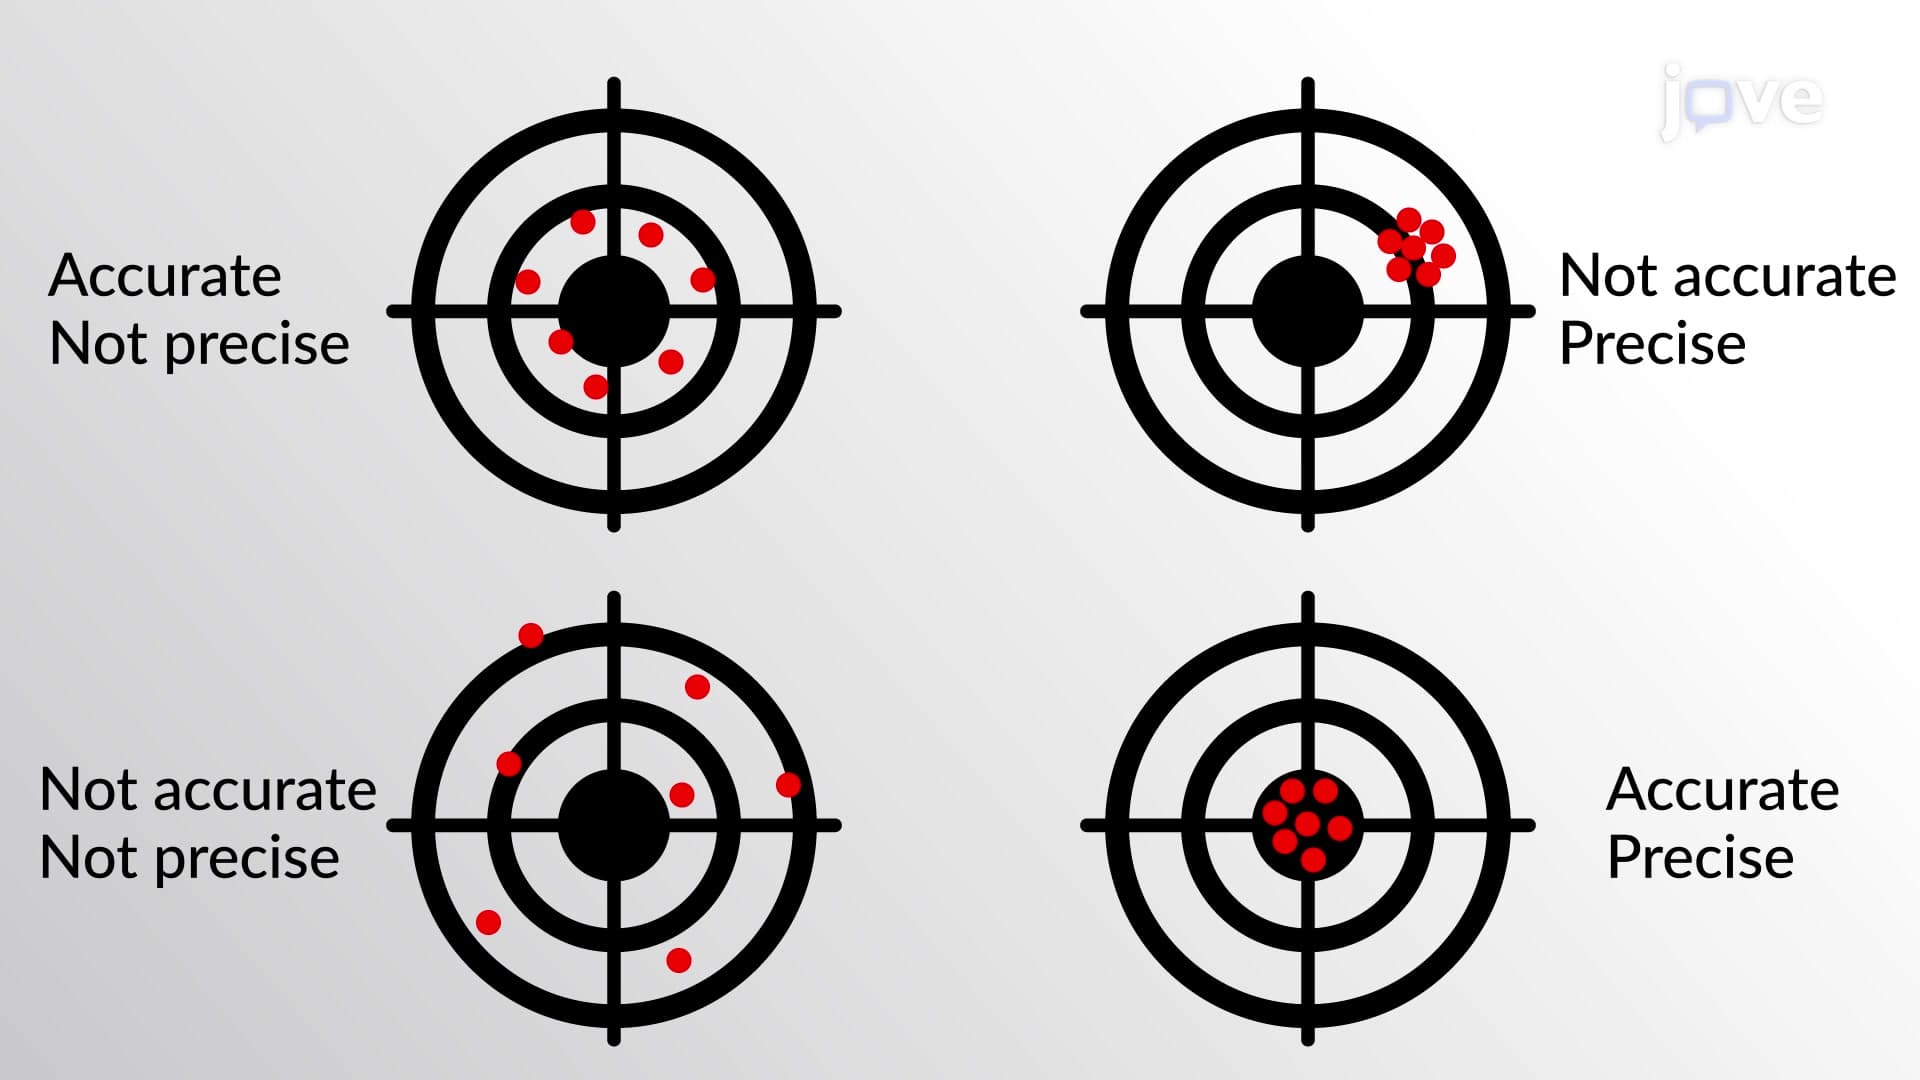
Accuracy and Precision
01:52Accuracy and Precision
 01:13
Sensitivity, Specificity, and Predicted Value
Sensitivity is the...
 01:28
Accuracy, limits, and approximation
Accuracy is defined as the closeness of the measured value to the true or actual value. In engineering mechanics, repeated measurements are taken during theoretical or experimental analyses to ensure that the result is precise and accurate.
The accuracy of any solution is based on the...
 01:19
Expected Frequencies in Goodness-of-Fit Tests
 01:03
Prediction Intervals
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
The...