Related Experiment Video
Updated: Sep 24, 2026
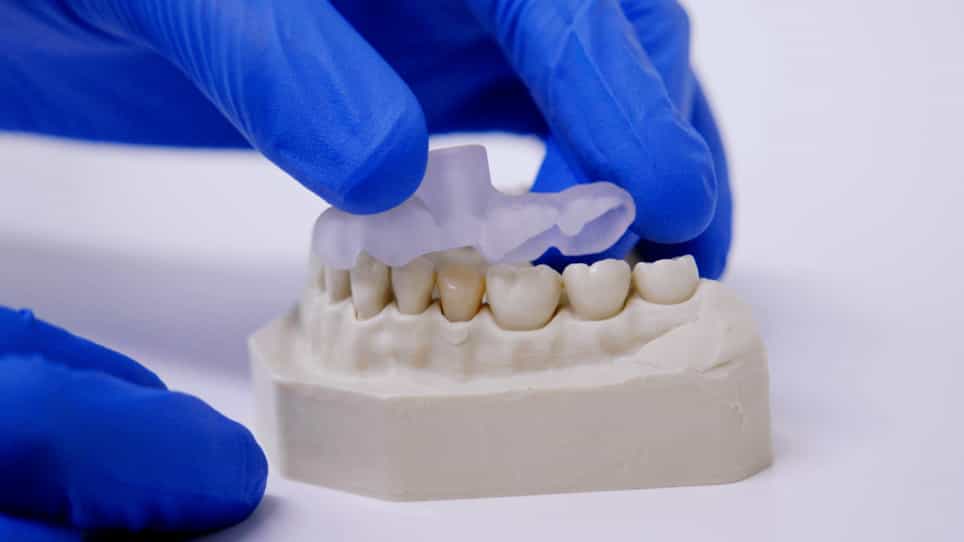

Guided Endodontics: Three-Dimensional Planning and Template-Aided Preparation of Endodontic Access Cavities
Published on: May 24, 2022
Before 'Expert-Level' Performance: Reproducibility and Reference-Standard Concerns in Evaluating Large Language
Satya Ranjan Misra1, Rupsa Das1
1Department of Oral Medicine & Radiology, Institute of Dental Sciences, Siksha 'O' Anusandhan University, Bhubaneswar, Odisha, India.

Abstract:
Recent claims of expert-level endodontic diagnostic performance by large language models require cautious interpretation. In a 40-case, text-only comparison, methodological concerns limit reproducibility and clinical generalisability. The reported testing period preceded the public release of GPT-5, making clarification of the exact model version, platform, access dates, and settings essential. Use of a single endodontist as the reference standard demonstrates agreement with one clinician rather than independently verified diagnostic accuracy. Binary yes/no vignettes may also simplify the diagnostic task and do not reflect routine multimodal assessment incorporating radiographic interpretation. Single-query testing prevents evaluation of response consistency, while perfect accuracy in a small sample remains compatible with considerable statistical uncertainty. These findings are therefore best viewed as preliminary evidence of high concordance under controlled conditions. Future studies should use transparent model reporting, repeated runs, consensus reference standards, and clinically representative multimodal cases before expert-level performance is inferred.

