Related Experiment Video
Updated: Sep 24, 2026

A Novel Bayesian Change-point Algorithm for Genome-wide Analysis of Diverse ChIPseq Data Types
Published on: December 10, 2012
New frontiers in the p-hacking practices: assessing the effect of data peeking practice on type-I error rate through
Francesca Freuli1,2, Stefano Noventa3,4, Luigi Lombardi1
1Department of Psychology and Cognitive Science, University of Trento, Trento, Italy.

Abstract:
Data-peeking, the practice of stopping data collection once significant results are obtained, poses a significant threat to the credibility of research by increasing the likelihood of observing and publishing false positive results. The effect of this practice on scientific reliability has traditionally been assessed through Monte-Carlo simulations, which suffer from some methodological issues (e.g., Monte-Carlo standard error is often overestimated). This paper presents a computational model that, through a series of convolutions between normal and truncated normal distributions, estimates the increase in false-positive rates due to data-peeking practice, overcoming the issues of the simulation method. The performance of the computational model was compared against Monte-Carlo simulations under different conditions, including alpha levels (0.05, 0.025, 0.01, and 0.001), sample sizes (40, 80, 160, and 320), and numbers of interim analyses (1 to 10). The results confirmed the computational model's accuracy and reliability, showing that computational values fell within two standard deviations of the simulated means. In conclusion, the proposed model not only presents an faster and error-reducing approach to estimating the effects of data-peeking practice but also provides guidelines for the development of similar models to examine other forms of p-hacking, thereby improving the understanding and study of their effects.
Related Concept Videos
 01:09
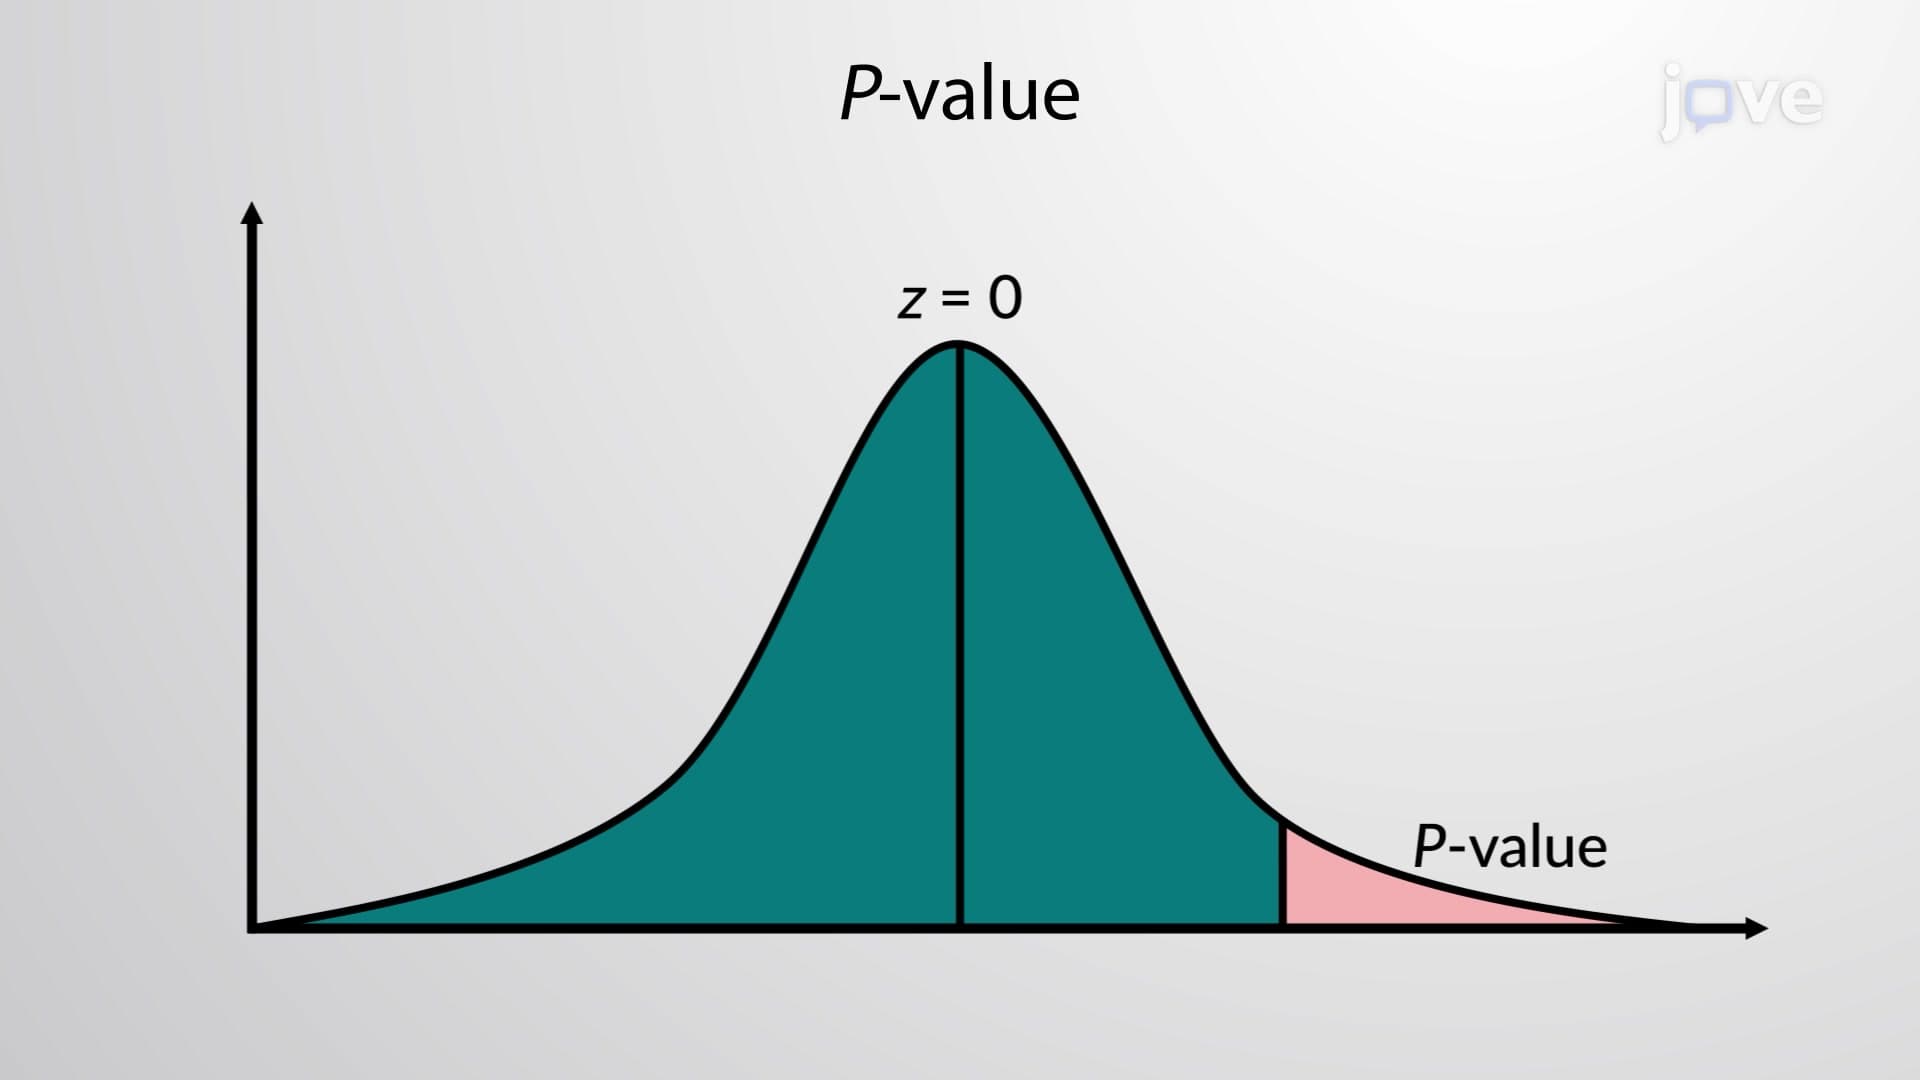
Decision Making: P-value Method
First, a specific claim about the population parameter is proposed. The claim is based on the research question and is stated in a simple form. Further, an opposing statement to the claim is also stated. These statements can act as null and alternative hypotheses: a null hypothesis would be a neutral statement while the alternative hypothesis can have a...
 01:14
Errors In Hypothesis Tests
 01:12
Types of Errors: Detection and Minimization
Absolute error in a measurement is the numerical difference from the true or central value. Relative error is the ratio between absolute error and the true or central value, expressed as a percentage.
Errors can be classified by source, magnitude, and sign. There are three types of errors: systematic, random, and gross.
Systematic or...
 01:15
Systematic Error: Methodological and Sampling Errors
Sampling errors originate from improper sampling methods or the wrong sample population. These errors can be minimized by refining the sampling strategy. Defective instruments or faulty calibrations are the sources of instrumental...
 01:13
Accuracy and Errors in Hypothesis Testing
In hypothesis testing, the probability of making a Type I error, denoted as α, is commonly set at 0.05. This significance level indicates a 5% chance...
 01:16
Statistical Inference Techniques in Hypothesis Testing: Parametric Versus Nonparametric Data
Parametric statistics, as the name suggests, assumes that data follow a specific distribution, often a normal distribution. This assumption enables robust hypothesis testing and estimation. Parametric methods, like the Student's t-test or Goodness-of-fit test, are frequently employed in biostatistics due to their robustness. For instance, comparing...