Related Experiment Videos
A Knowledge-Data Design of Fuzzy Rule-Based Models

Abstract:
Machine learning (ML) models, including rule-based architectures dominant in the technology of fuzzy sets, are constructed with the aid of intensive usage of data. Quite often, knowledge about the system/problem is available and offers some tangible benefits to the construction of the models. The relevance of knowledge becomes of paramount importance when the data do not fully represent the problem and are not distributed across the overall input space. Under these circumstances, data-based ML models will very likely fail when being deployed in a real-world environment. The current intensively studied paradigm of physics-informed ML has emerged to support the design of models augmented by available knowledge describing some global relationships, invariants, and regularities stemming from the underlying physics of the phenomenon/system. It has already been shown that through such holistic data-knowledge perception and ensuing synergistic development, the performance of resulting ML models visibly improved. The impactful and far-reaching objective of this study is to establish an original knowledge-data unified design environment. We demonstrate and quantify how ML models are built by minimizing a carefully generalized (extended) loss function involving both data and knowledge (with the latter being conveyed in the form of a so-called reference model). We develop an additive loss function that exhibits flexibility, and its hyperparameter controls a tradeoff between the reliance on data and knowledge. A systematic way of optimizing the hyperparameter in the loss function and striking a balance between the guidance delivered by data and knowledge is investigated. Along with a general development methodology, the study introduces an original and detailed way of constructing fuzzy rule-based models when taking advantage of data and knowledge. The detailed design processes of building conditions of rules with the aid of the modified fuzzy clustering and an extended optimization of linear functions forming the conclusions of the rules are discussed. Illustrative examples are covered, showcasing the substantial reduction of the values of the loss function to about 25%-30% over the performance of only data-based constructed ML models.
Related Concept Videos
 01:34
Woodward–Hoffmann Selection Rules and Microscopic Reversibility
 01:28
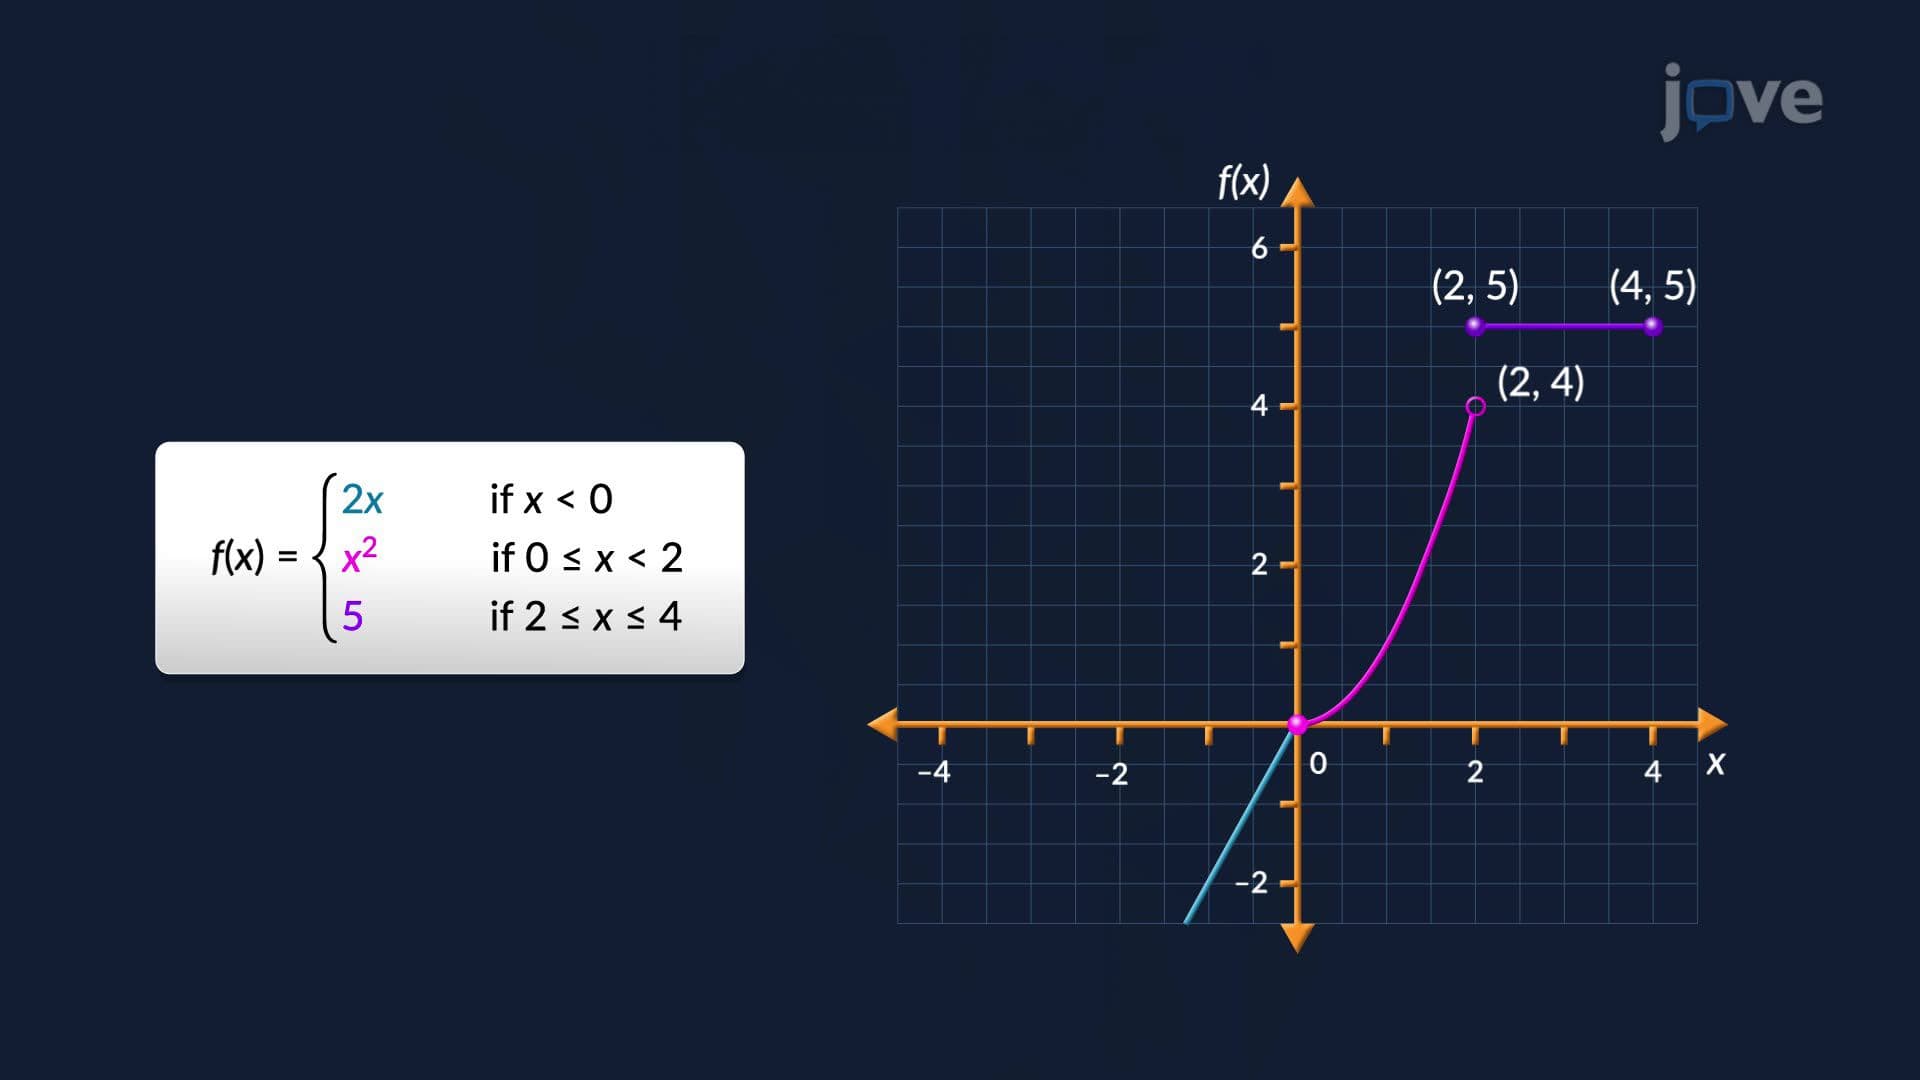
Piecewise-Defined Functions
 00:59
Inductive Reasoning
 01:29
Rules for Defining Functions
 01:08
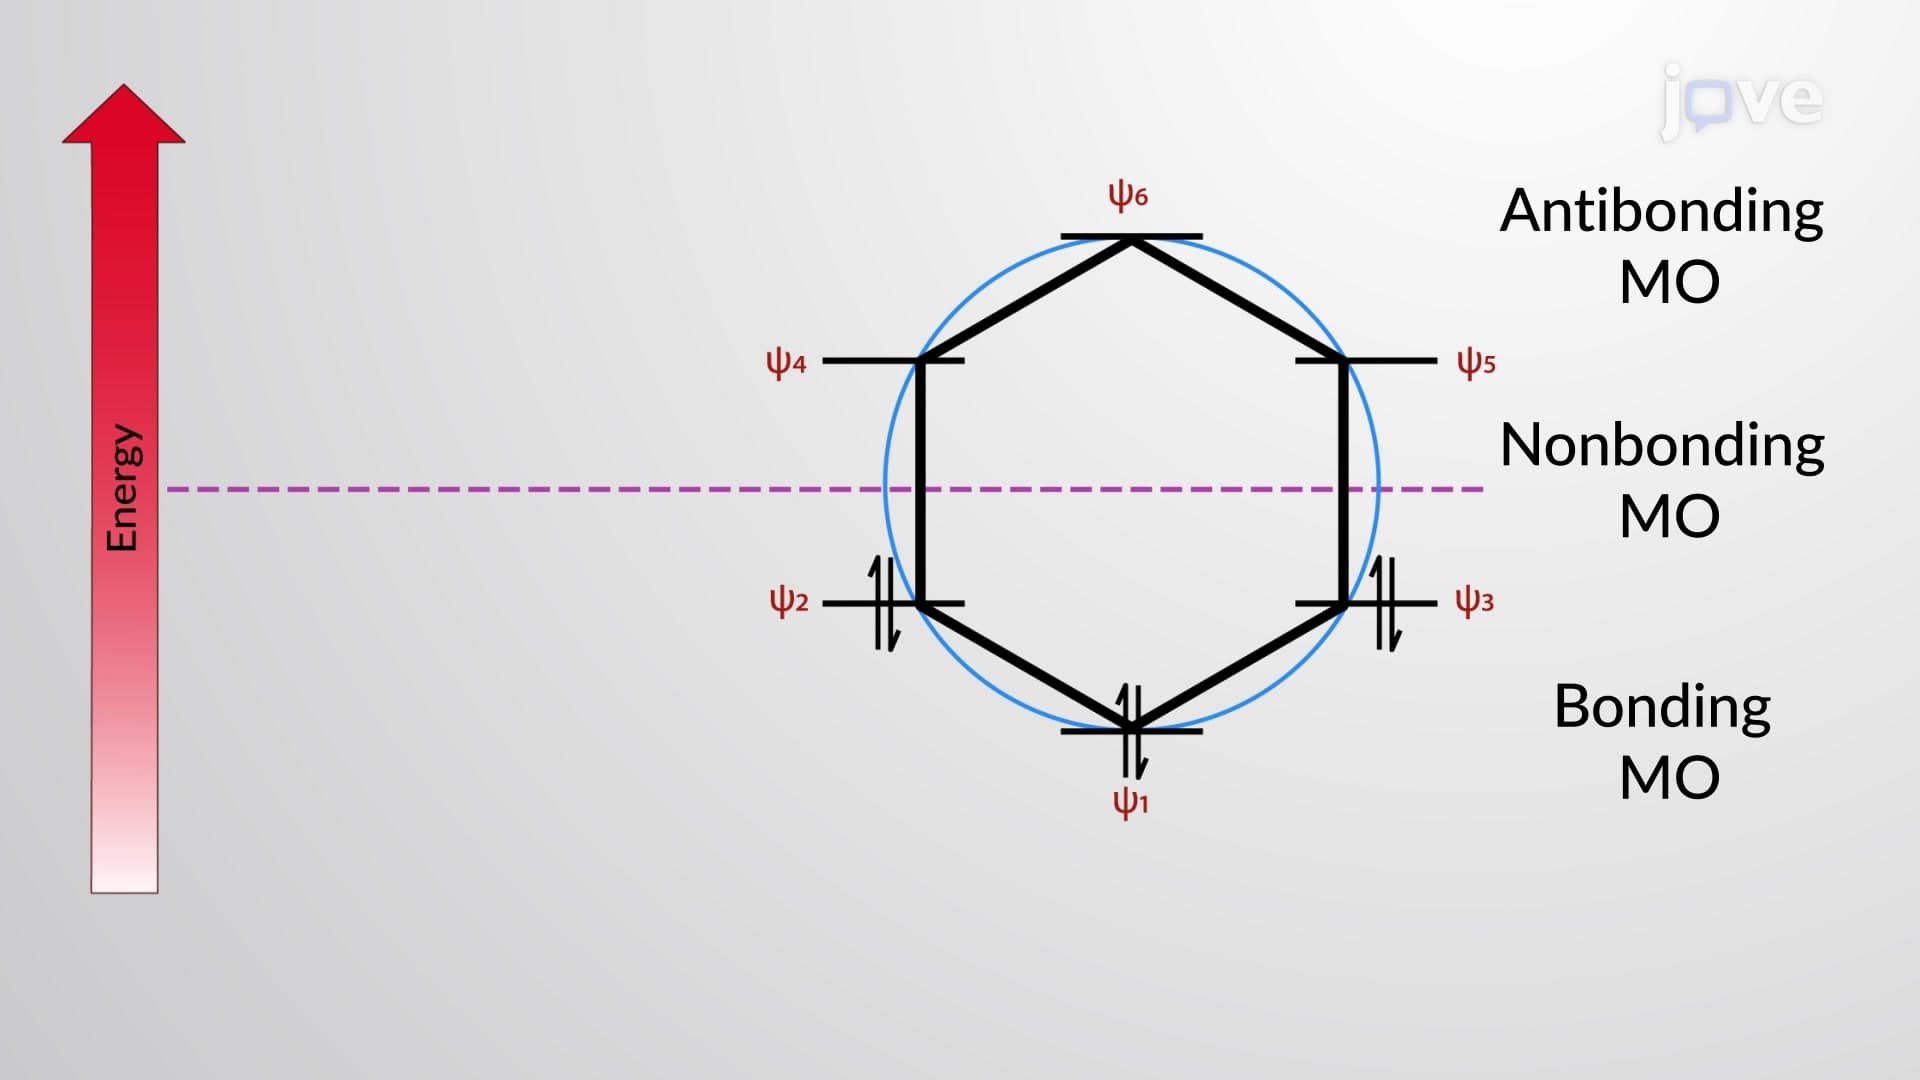
Hückel's Rule Diagram of π MOs: Frost Circle
A Frost circle is constructed by drawing a polygon whose number of edges is equal to the number of carbons of the given cyclic system, with one of the vertices pointing down. Then, a circle is drawn enclosing the polygon so that...
 01:25
Models of Health Promotion and Illness Prevention I
The health belief model (HBM) attempts to predict health-related behavior in specific belief patterns. According to the HBM, a person's...