Related Experiment Video
Updated: Oct 1, 2026

Eye Tracking During Visually Situated Language Comprehension: Flexibility and Limitations in Uncovering Visual Context Effects
Published on: November 30, 2018
Disentangling Visual and Factual Correctness in LVLMs' Visualization Literacy

Abstract:
Large Vision-Language Models (LVLMs) have shown remarkable capabilities in visualization interpretation, yet it remains unclear whether their responses reflect genuine reasoning over visual evidence or the influence of factual priors learned during training. Current evaluation methods mix these two sources, obscuring when correct visual interpretation is overridden by memorized factual knowledge. We present a disentanglement framework that systematically isolates visual correctness from factual correctness, revealing fundamental validity limitations in existing visualization literacy assessments. Through three complementary experiments with 15 state-of-theart LVLMs, we demonstrate that: (1) Although several models achieve human-level performance on standard tests (VLAT), such performance may reflect factual recall rather than visual understanding, whereas randomized-data tests (reVLAT) underestimate visualization literacy when visual interpretation is correct but superseded by conflicting factual priors. (2) Using our Counterfactual Visualization Literacy Assessment Test (CVLAT) alongside capability-normalized arbitration metrics, we classify models by the sign of their visual-factual reliance index (VFRI). This classification reveals a visualization-oriented majority and a factual knowledge-oriented minority, although several near-zero cases warrant cautious interpretation. The factual knowledgeoriented minority tends to override the chart with prior knowledge. A human baseline (N = 30) on the same counterfactual items confirms that people overwhelmingly follow the chart under conflict, providing a human reference point for visual-factual arbitration. (3) Prompt-based intervention can shift this prioritization, but its effectiveness is highly model-dependent and often direction-asymmetric, with some models responding strongly to only one prompt direction. Furthermore, high chart-reading capability does not predict prompt-controllability, indicating that visual-factual arbitration is not uniformly steerable. Overall, our findings demonstrate that LVLMs' high visualization accuracy is not sufficient evidence of faithful visual reasoning. We argue that reliable LVLM integration into visual analytics requires evaluating not only visualization literacy, but also how models arbitrate between visual evidence and factual priors, particularly when the two sources diverge. The CVLAT benchmark and code are available at https://github.com/JaeyoungKim-HCIL/CVLAT.
Related Concept Videos
 01:30
Symbolic Understanding I: Pictorial Competence
 01:26
Methods of Documentation IV: Focus Charting
It typically involves three columns for recording information:
 01:28
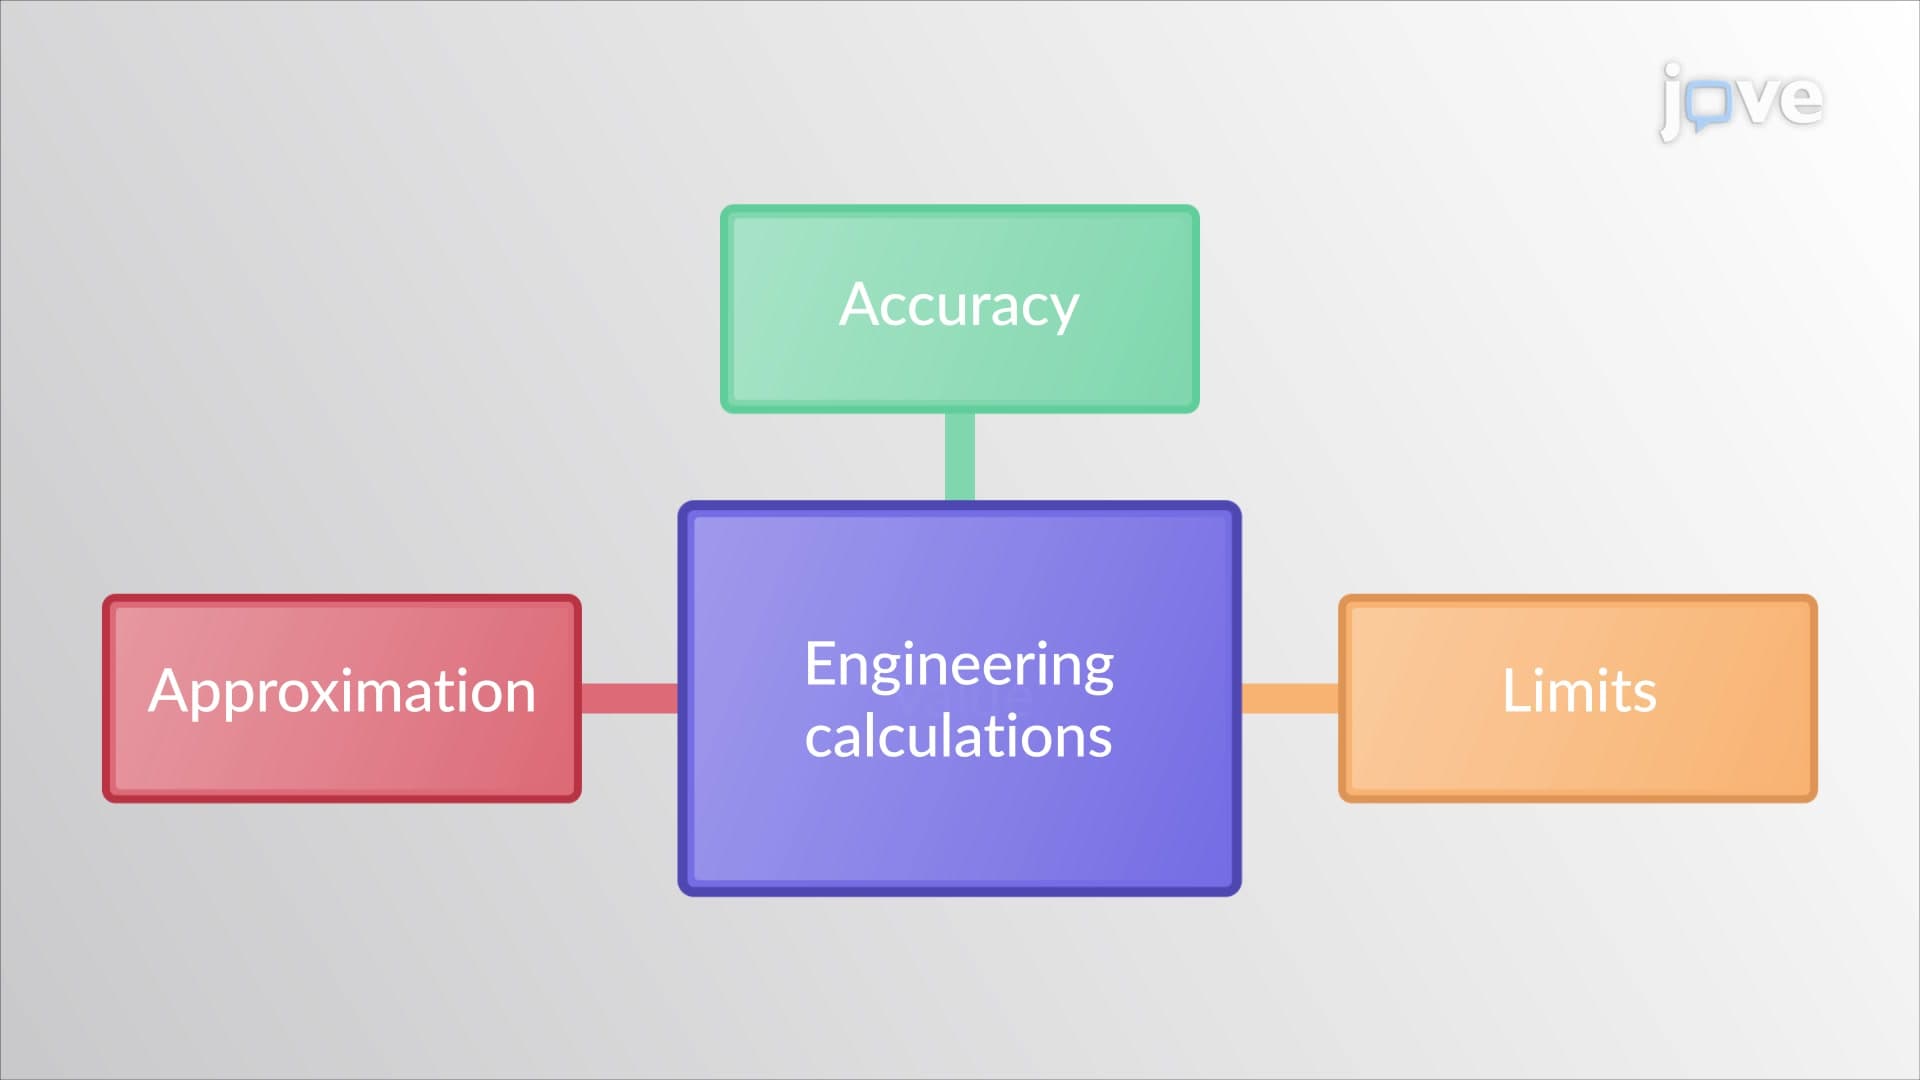
Accuracy, limits, and approximation
Accuracy is defined as the closeness of the measured value to the true or actual value. In engineering mechanics, repeated measurements are taken during theoretical or experimental analyses to ensure that the result is precise and accurate.
The accuracy of any solution is based on the...
 01:21
Manipulation and Analysis
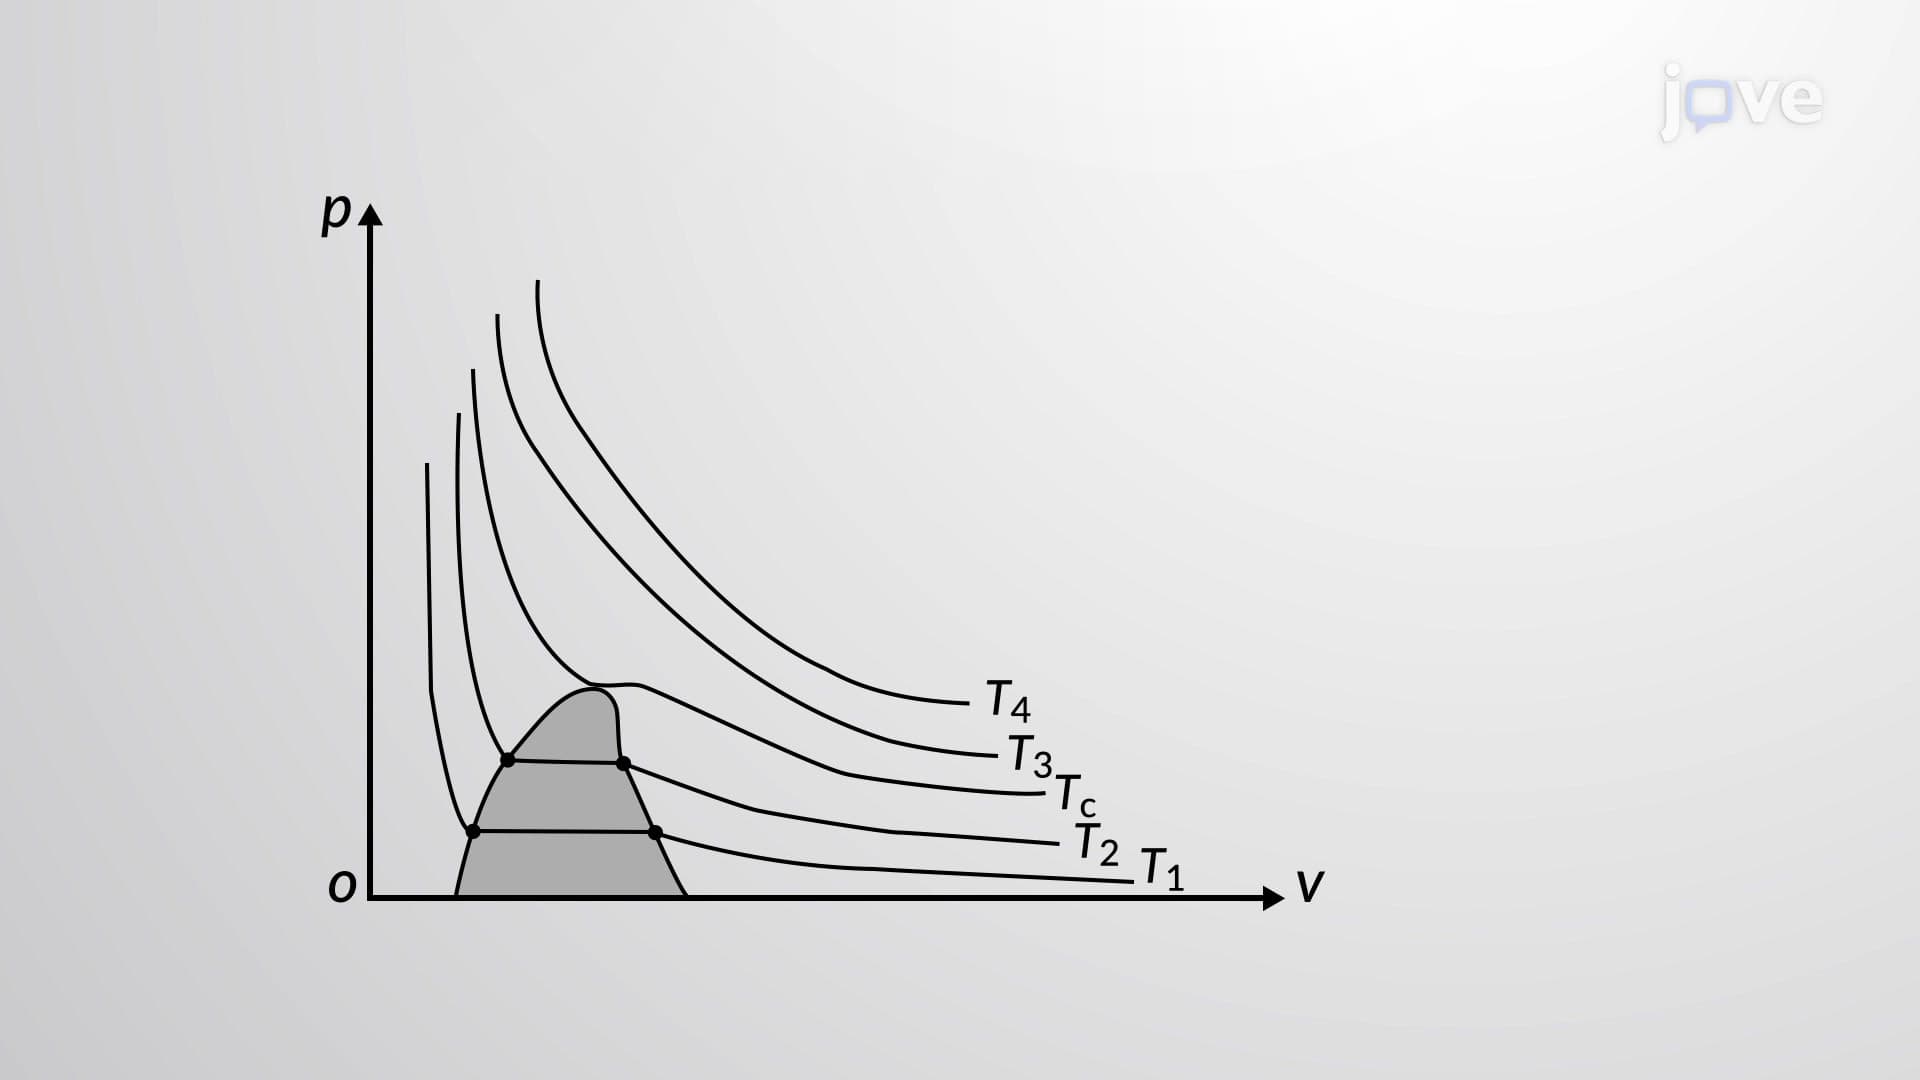 01:18
pV-Diagrams