Related Experiment Videos
Full-Batch Gradient Descent Outperforms One-Pass SGD: Sample Complexity Separation in Single-Index Learning
Filip Kovačević1, Hong Chang Ji2, Denny Wu3,4
1Institute of Science and Technology Austria.

Abstract:
It is folklore that reusing training data more than once can improve the statistical efficiency of gradient-based learning. However, beyond linear regression, the theoretical advantage of full-batch gradient descent (GD, which always reuses all the data) over one-pass stochastic gradient descent (online SGD, which uses each data point only once) remains unclear. In this work, we consider learning a -dimensional single-index model with a quadratic activation, for which it is known that one-pass SGD requires samples to achieve weak recovery. We first show that this factor in the sample complexity persists for full-batch spherical GD on the correlation loss; however, by simply truncating the activation, full-batch GD exhibits a favorable optimization landscape at samples, thereby outperforming one-pass SGD (with the same activation) in statistical efficiency. We complement this result with a trajectory analysis of full-batch GD on the squared loss from small initialization, showing that samples and gradient steps suffice to achieve strong (exact) recovery.
Related Concept Videos
 01:27
Gradient Fields
 01:24
One-Compartment Open Model: Wagner-Nelson and Loo Riegelman Method for ka Estimation
On...
 01:07
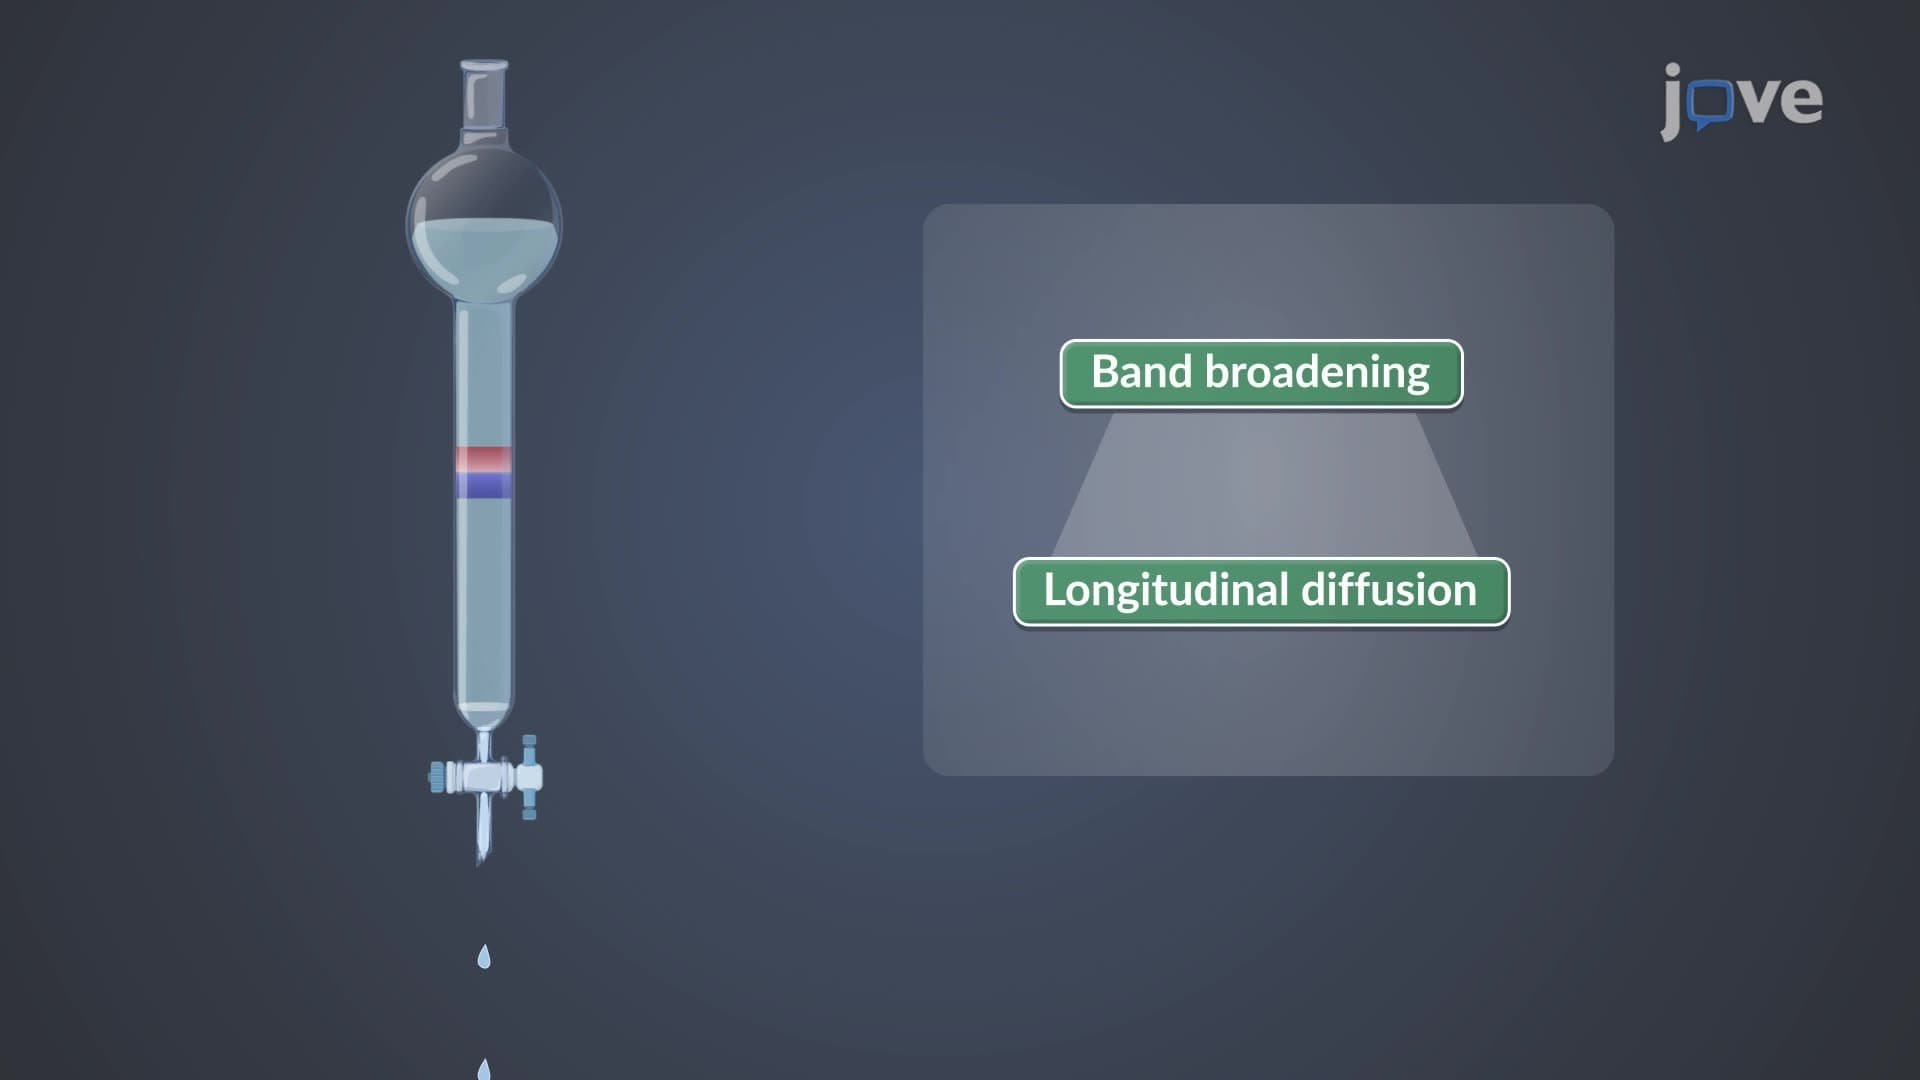
Diffusion on Chromatography Columns
Longitudinal diffusion occurs when the solute molecules in the mobile phase diffuse from the more concentrated center of the chromatographic band to the more dilute regions on either side, both towards and against the flow direction. This...