Related Experiment Video
Updated: Oct 11, 2026
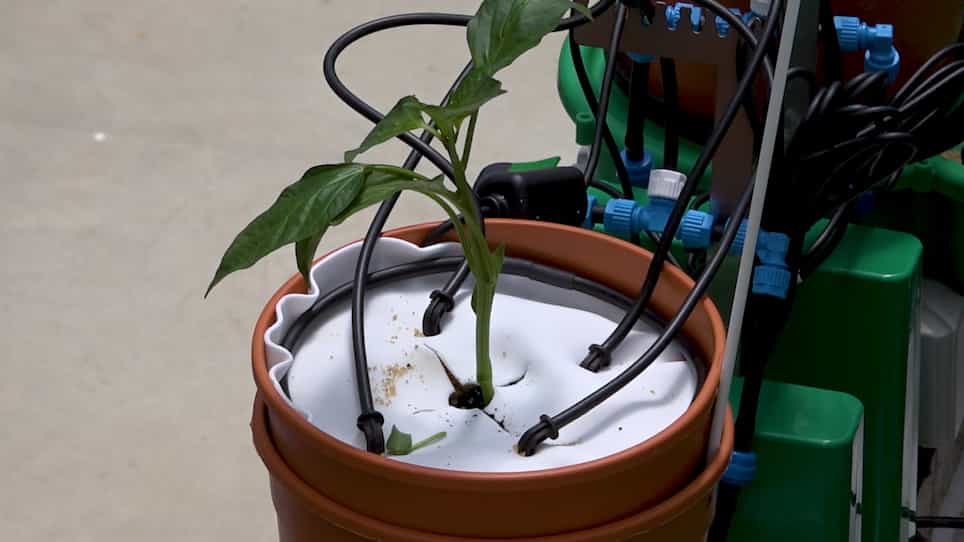

A Telemetric, Gravimetric Platform for Real-Time Physiological Phenotyping of Plant–Environment Interactions
Published on: August 5, 2020
Benchmarking ensemble and deep learning models for drought-responsive gene prioritisation in rice using multi-omics
Kumanan N Govaichelvan1, Dharini Pathmanathan2, Rabiatul Adawiah Zainal-Abidin3
1Institute of Biological Sciences, Faculty of Science, Universiti Malaya, Kuala Lumpur, Wilayah Persekutuan Kuala Lumpur, Malaysia.

Abstract:
Identifying drought-responsive genes is critical for climate-resilient crop breeding, yet computational gene-trait association often relies on single-omics or generalized genomic datasets. Optimal algorithm selection for high-dimensional, small multi-omics datasets also remains a persistent challenge. We present a machine learning framework that extends the QTG-Finder feature set by integrating transcriptomic and proteomic features to classify drought-responsive genes in rice. Using MBKBase annotations, we evaluated the ability of these models to prioritise 336 drought-responsive genes among 2,416 abiotic stress-associated genes, of which the remaining 2,080 constituted an operational background set. We tested four algorithms: Random Forest, XGBoost, one-dimensional convolutional neural network, and multilayer perceptron, while addressing severe class imbalance and assessing model stability. Tree-based ensemble methods achieved higher performance than the deep learning models in this dataset, which showed early overfitting. The fine-tuned Random Forest achieved a recall of 0.67 and an AUC-ROC of 0.87 under nested cross-validation, conditional on a feature matrix assembled before gene-level data splitting. Across repeated evaluations of a small internal holdout of 10 genes, mean accuracy and recall were 0.90 and 0.63; this set is too small to support a generalizability claim and is reported only as a consistency check. The newly added transcriptomic and proteomic features improved recall from 0.47 to 0.67 compared with genomics alone. Feature importance and ablation analyses indicated that transcriptomics-derived features, particularly measures of expression distribution, magnitude, and direction, contributed most to predictive performance. Functional enrichment analysis supported the biological relevance of the prioritised genes. These results demonstrate the value of multi-omics integration for gene prioritisation in small tabular datasets while highlighting current limitations of deep learning in this setting.
Related Concept Videos
 02:41
Responses to Drought and Flooding
 01:59
Plant Breeding and Biotechnology