Related Experiment Video
Updated: Oct 15, 2026
From Voxels to Knowledge: A Practical Guide to the Segmentation of Complex Electron Microscopy 3D-Data
Published on: August 13, 2014
Test-time optimization for domain adaptive open vocabulary segmentation
Ulindu De Silva1, Didula Samaraweera1, Sasini Wanigathunga1
1University of Moratuwa, Bandaranayake Mawatha, Moratuwa, 10400, Sri Lanka.

Abstract:
We present Seg-TTO, a novel framework for zero-shot, open-vocabulary semantic segmentation (OVSS), designed to excel in specialized domain tasks. While current open-vocabulary approaches show impressive performance on standard segmentation benchmarks under zero-shot settings, they fall short of supervised counterparts on highly domain-specific datasets. We focus on segmentation-specific test-time optimization to address this gap. Segmentation requires an understanding of multiple concepts within a single image while retaining the locality and spatial structure of representations. We propose a novel self-supervised objective adhering to these requirements and use it to align the model parameters with input images at test time. In the textual modality, we learn multiple embeddings for each category to capture diverse concepts within an image, while in the visual modality, we calculate pixel-level losses followed by embedding aggregation operations specific to preserving spatial structure. Every pretrained backbone, vision-language encoder and decoder weight stays frozen, no training or target-domain data is used, and no adapted state is carried from one test image to the next. Our resulting framework termed Seg-TTO is a plug-and-play module. We integrate Seg-TTO with state-of-the-art OVSS approaches (CAT-Seg and CLIP-DINOiser, spanning three model variants) and evaluate across 22 challenging OVSS tasks from the MESS benchmark, covering a range of specialized domains. Our Seg-TTO demonstrates clear performance improvements, with mean gains of 1.8, 2.6 and 1.6 mIoU over CAT-Seg-B, CAT-Seg-L and CLIP-DINOiser respectively, improving on 20 of the 22 datasets for both CAT-Seg variants, with relative improvements of up to 57% and 27% on individual specialized-domain datasets for CAT-Seg-B and CAT-Seg-L respectively, establishing new state-of-the-art. Our code, the exact LLM-generated attribute sets, and models will be released publicly.
Related Concept Videos
 01:17
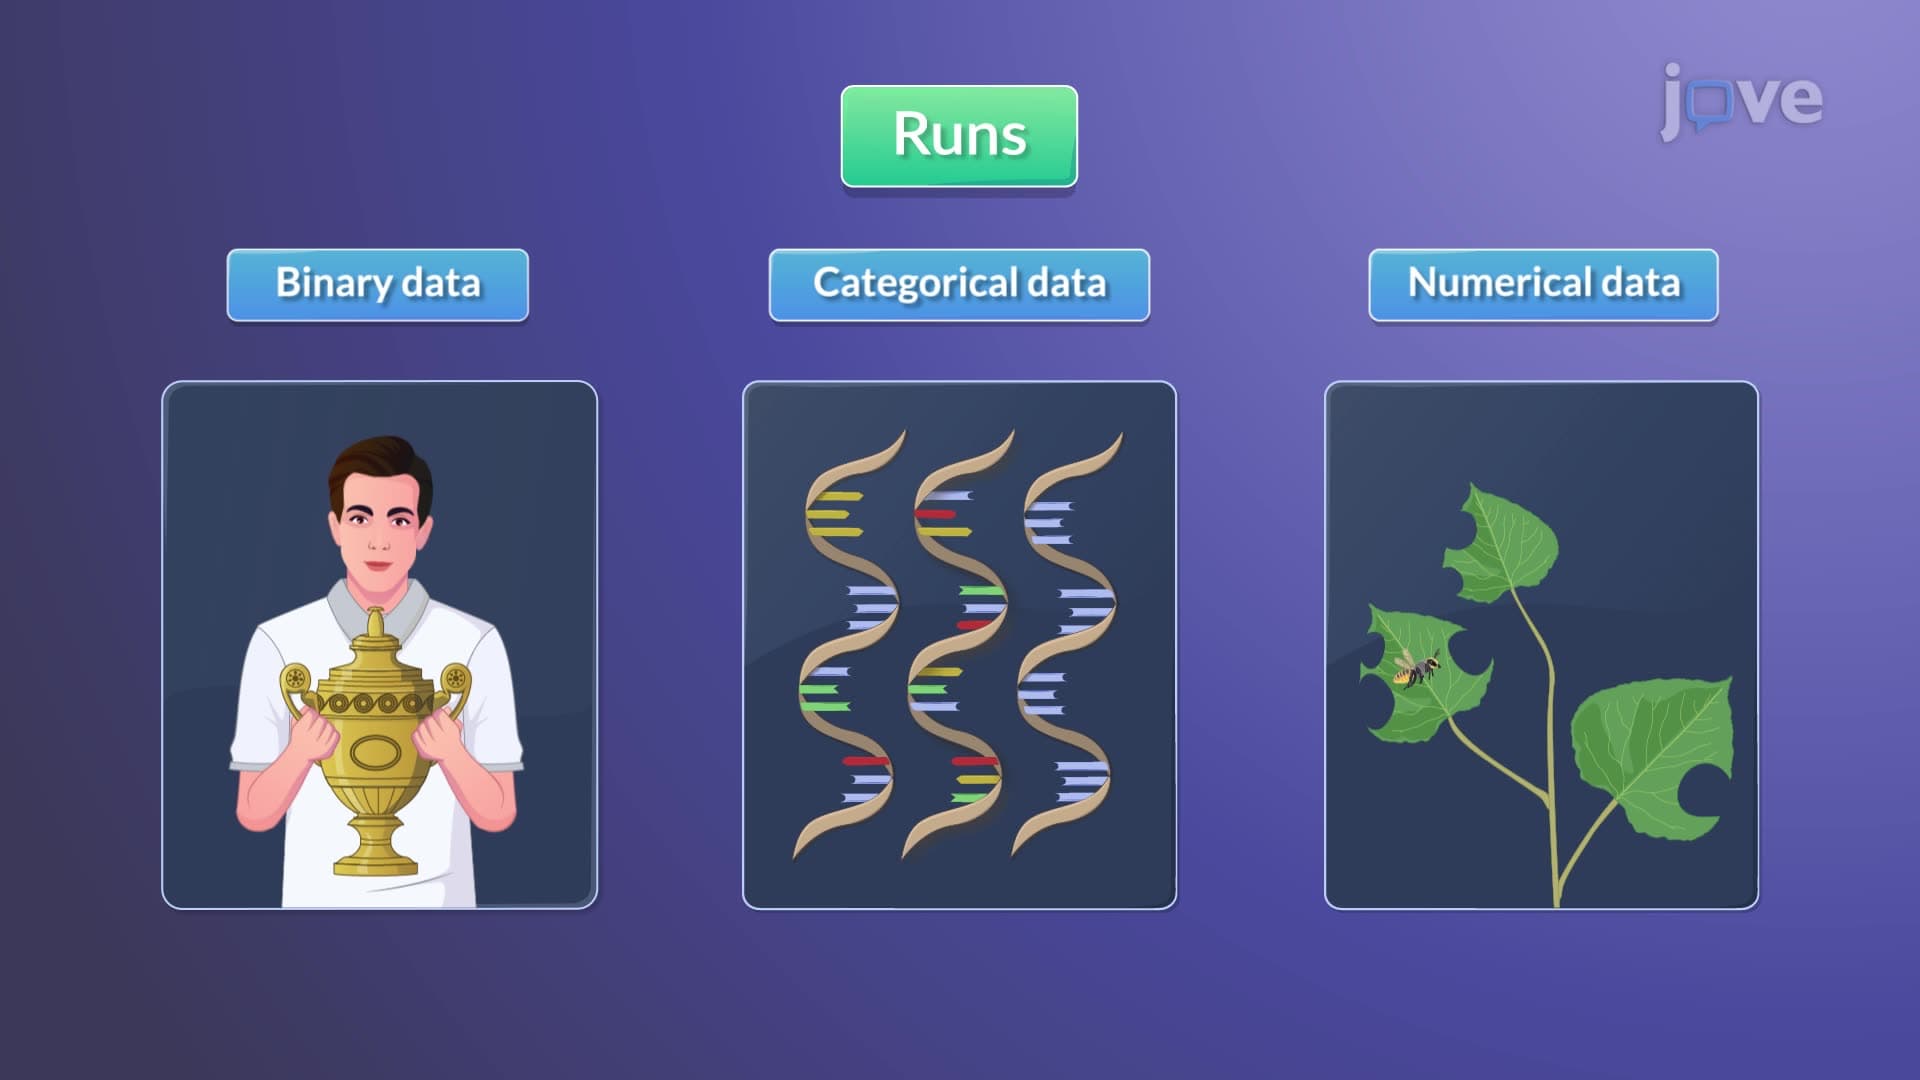
Wald-Wolfowitz Runs Test I
The test works...
 01:17
Wald-Wolfowitz Runs Test II
For binary data, runs are identified using symbols such as + and −, or equivalently, 1s and 0s. In...