Related Experiment Video
Updated: Oct 25, 2026
Exploring the Role of Deontic Reasoning and World Knowledge in Wason´s Selection Task
Published on: July 22, 2025
CODER: Data-efficient activation of mathematical reasoning via difficulty-aware core-set
Lei Wang1, GuoAo Liu1, XiaoYong Zhao1
1Beijing Information Science & Technology University, 102206, Beijing, China.

Abstract:
Large language models (LLMs) demonstrate remarkable performance in mathematical reasoning tasks, yet their fine-tuning process typically relies on substantial volumes of high-quality annotated data. Under conditions of limited computational resources and sparse data, they are highly susceptible to overfitting and catastrophic forgetting. Inspired by the classic textbooks used in human education from primary to secondary school, which embody a natural difficulty progression, this work suggests that constructing hierarchical data covering key knowledge nodes can effectively facilitate the activation of a model's logical reasoning capabilities with minimal sample cost. This paper proposes CODER, a data-efficient fine-tuning framework based on difficulty-aware set construction and collaborative regularisation. First, we constructed Math-Core-700 from a candidate pool spanning the full primary-to-university curriculum - textbook exercises, provincial mock examinations, publicly released competition problems and introductory university mathematics such as calculus. This dataset features a complete difficulty gradient spanning fundamental operations to advanced abstract concepts. By purposefully incorporating final-stage examination questions and competition proof problems, we facilitated the model's transition from simple pattern mimicry to enhanced logical reasoning. Secondly, we devise a collaborative fine-tuning strategy that leverages DoRA to decouple the magnitude and direction of parameter updates, while integrating NEFTune to inject noise into the feature space to promote manifold distribution smoothing. Empirical results provide supportive evidence that this approach achieves 90.6%(mean) and 82.9% (pass@16) accuracy on GSM8K and AMC 23 respectively using only 700 samples, achieving competitive or superior performance compared to standard LoRA baselines trained on the MATH dataset (7.5k samples) and TAL-SCQ5K dataset (5k samples). This finding suggests that during downstream fine-tuning, data filtering strategies based on a knowledge-grounded Difficulty-Aware Core-Set can potentially mitigate the diminishing returns associated with data scale. Consequently, they enable the effective activation of model capabilities without relying on extensive labelled data, thereby exploring new pathways for popularising high-performance large model training in resource-constrained environments.
More Related Videos
Related Concept Videos
 01:16
Deductive Reasoning
 01:30
Reasoning
Inductive reasoning involves deriving generalizations from specific observations. This type of reasoning helps form beliefs about the world. For example,...
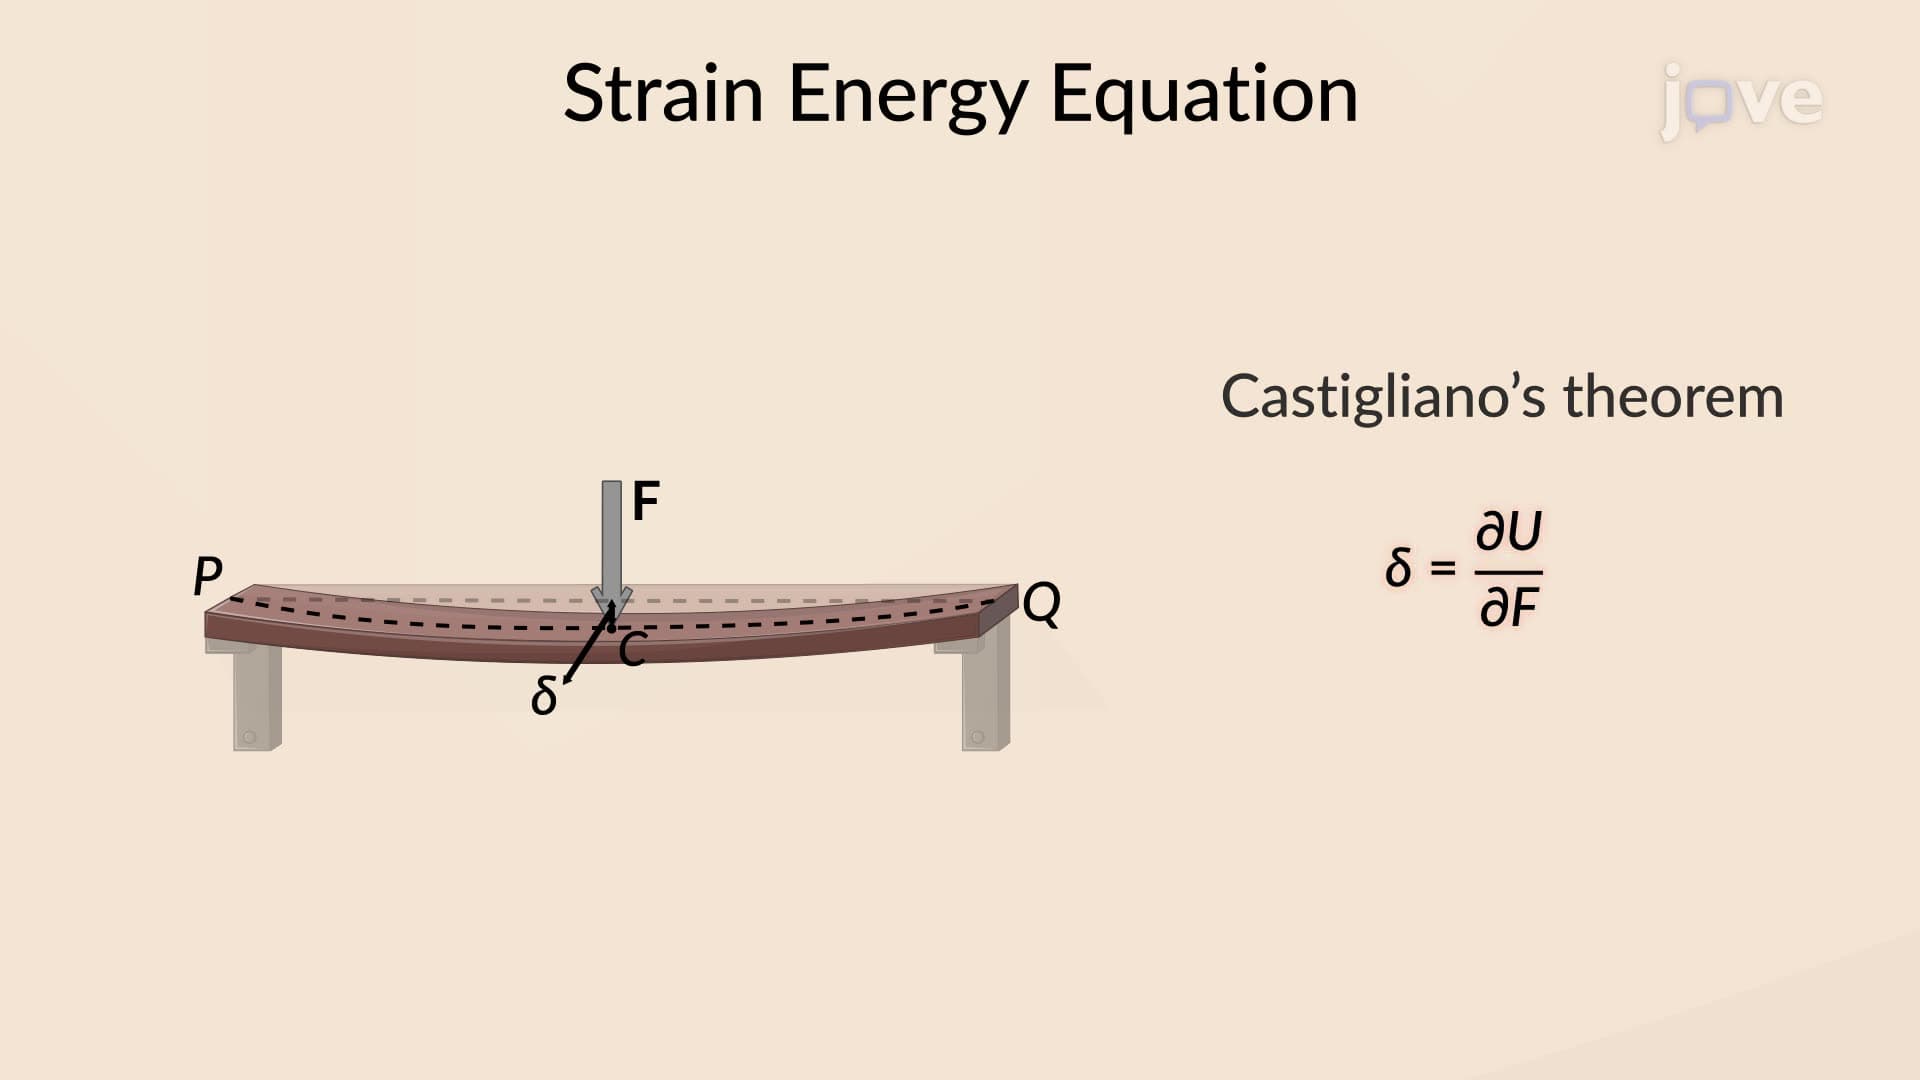 01:14
Castigliano's Theorem: Problem Solving
 00:59
Inductive Reasoning
 01:27
Associative Learning
Classical conditioning, also known...
 01:16
Preoperational Thought IV: Numbers